Live now: our Voice Track from AI Engineer World's Fair 2026.
Half a second that made a product feel slow, a trillion phone calls a year, and the case for agents that know when not to speak.
Thesis: voice agents do not fail at talking. They fail at listening.
https://t.co/xx1VOTKCDQ
- The New Primitives: @kwindla, Daily
- Speech-to-Speech Model Research at Google DeepMind: @valeriawu_ & Tom Ouyang
- Voice Agents Can Just Do Things: @charlierguo, OpenAI
- Your Voice Agent is Just a Walkie Talkie: @neilzegh, Gradium
- Voice-First AI Companion: @paularambles, Tolan
- 5 Voice Agent Failure Modes You'll Hit in Week One: @bevenky, Plivo
- I Monitored Crime Audio. Voice Agents Scare Me More. @sumanyu, Hamming AI
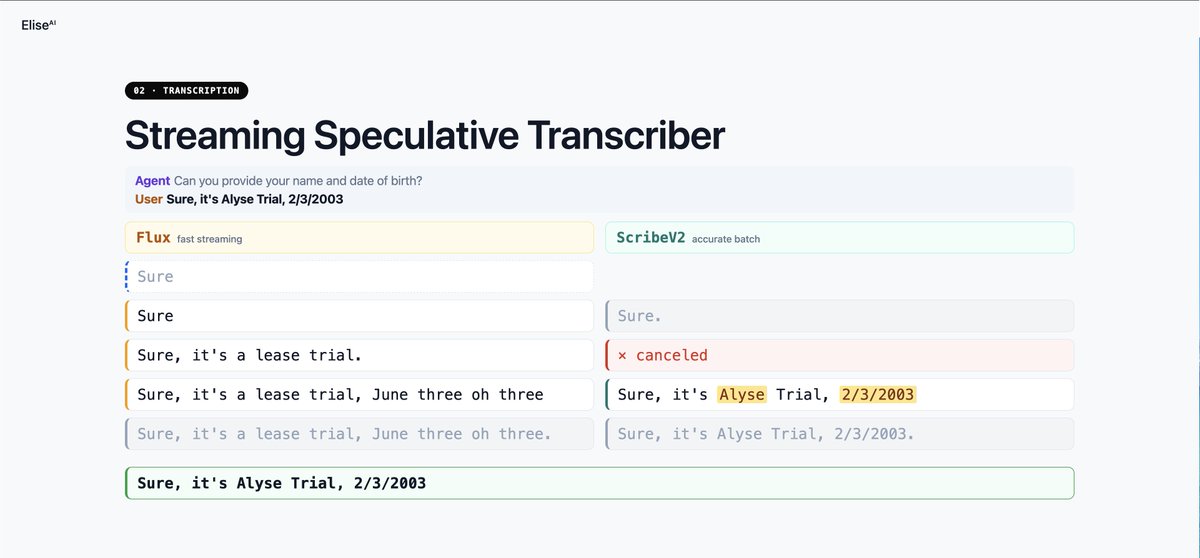
- Realtime Voice Agents with Frontier Intelligence: @bobowchan, EliseAI
- "My name is... my name is...": Midam Kim, ServiceNow
- Act, Confirm, or Stop? Amit Desai, Roku
excited to finally share this. for the past couple months @elise_ai has been an early access partner with @OpenAIDevs on gpt-live-1.
we've brought it into production starting with healthcare. when patients call, they're usually trying to book an appointment or sort out a billing question. a bad call means they just don't get help.
full-duplex, handles interruptions, stays engaged mid-task. cascaded pipelines can't do this. patients get what they called for.
it's been great collab-ing with you @theteriyu@pbbakkum@SaiMandhan and the rest of the openai team!
shout out to the entire voiceAI team including @BoBowchan@TheRealAk914!
Been hard to keep this one a secret!
For the past couple of months, @elise_ai has been working with @OpenAIDevs as an early design partner for GPT‑Live-1.
I still remember my excitement back in 2024 when the first S2S models came out, but it took a long time to get to production - now it feels like we’re finally there.
There are lots of really interesting improvements to using GPT-Live-1 – some less obvious than others:
Last week at @aiDotEngineer World Fair, staff software engineer Bohan Li broke down @elise_ai's cascaded voice agent harness and shared the unorthodox tricks we do to unlock frontier capability at real-time speeds.
We drew inspiration from the self-driving car stack, which orchestrates models across perception, planning and controls to deliver a system capable of making complex decisions in milliseconds.
Extremely proud of the team @cartesia for launching Sonic 3.5, which sets a new state of the art for TTS
I personally led the technical direction of this model; we built it ground up from first principles, and it contains multiple non-trivial ideas that differ substantially from anything we’ve seen in the literature. It’s been very gratifying to see research bets play out and the strong research team at Cartesia continue to grow!
Really proud to announce Sonic-3!
Sonic-2 gave us speed and accuracy and Sonic-3 adds emotion and naturalness on top. This makes it the best TTS model in the world.
But don't just take my word for it, try it out yourself!
https://t.co/DxLq7IujdH
We've raised $100M from Kleiner Perkins, Index Ventures, Lightspeed, and NVIDIA.
Today we're introducing Sonic-3 - the state-of-the-art model for realtime conversation.
What makes Sonic-3 great:
- Breakthrough naturalness - laughter and full emotional range
- Lightning fast -
We've raised a $64M Series A led by @kleinerperkins to build the platform for real-time voice AI.
We'll use this funding to expand our team, and to build the next generation of models, infrastructure, and products for voice, starting with Sonic 2.0, available today.
Link below to try it free 👇
We've raised $27M from Index Ventures, Lightspeed, Factory, Conviction, SVA, General Catalyst, A* and our wonderful angels.
Cartesia's audio models power the next generation of voice agents, digital media, and assistants across startups and large enterprises.
Our mission is to build real-time intelligence with long memory, that runs wherever you are. Multimodal brains for everyone!
Today, we’re unveiling a significant milestone in our journey toward ubiquitous artificial intelligence: AI On-Device.
Our team pioneered a radically more efficient architecture for AI with state space models (SSMs). Now, we’ve optimized and deployed them at the edge. We believe the future of AI runs on your device, where it can process continuously and is reliable, private, and secure.
Read our full blog post here: https://t.co/oqmcSjxm0E
Hey, I just finished this pure cairo implementation of sha256 which supports any bit length. There are also a few more of my experiments on the repo, I hope you like them.
https://t.co/QpgAk5Kbs9
Starting a basic JWT library for cairo: https://t.co/P6gfm3X2dY
Leveraging string library from @guiltygyoza and base64 encoding from @dhruv_kelawala@GuthL