A tricky LLM interview question:
You're serving a reasoning model on vLLM, and long traces keep pushing it out of GPU memory.
You add KV cache compression and evict 90% of the cached tokens.
VRAM usage doesn't move, and the GPU still runs out of memory.
Why?
(answer below)
Evicting 90% of the KV cache can free close to zero bytes on a paged server.
During decoding, every new token appends its key and value vectors at every layer. vLLM holds all of them until the request finishes.
For reasoning models with long chains of thought, this cache is the main memory cost.
A Qwen3-32B with 4-bit weights on a 24GB GPU needs KV for every token of a 32K-token trace, and it hits OOM around 24K tokens.
Attention over long contexts is sparse, so you can keep the high-importance tokens and drop the rest with little accuracy loss.
That reduces the number of cached tokens but it doesn't necessarily reduce allocated memory.
vLLM manages the cache with PagedAttention. It splits GPU memory into fixed physical blocks of 16 token slots each.
The allocator reclaims a block only when all 16 slots are empty.
Importance-based eviction keeps tokens scattered across the full sequence, so the retained tokens are spread over nearly every block.
Evict 14K of 16K tokens across 1,000 blocks, and almost every block still holds at least one token.
So the allocator reclaims close to nothing.
You could write new tokens into the empty slots. If token 16,001 goes into the slot token 40 held, the block now reads positions 38, 16,001, 41.
The cache is no longer in position order. Attention still gives the correct result, but each slot now needs a stored position index, and every kernel has to read it.
An in-order layout doesn't need that metadata.
So the cache shrinks 90% logically and 0% physically. Many compression papers miss this because they benchmark on pre-allocated contiguous tensors instead of a paged server.
The second problem is the eviction signal.
Most eviction methods rank tokens by their attention scores.
FlashAttention never materializes those scores. It computes attention tile by tile in on-chip SRAM and discards each score tile after use, which is where its speed comes from.
To get the scores, you have to fall back to eager attention and build the full score matrix in HBM, which removes the speedup FlashAttention provides.
NVIDIA's TriAttention handles both problems.
It ranks tokens without attention scores. It uses the geometry of the query and key vectors before RoPE is applied, where they form stable clusters.
Every 128 decoded tokens, it runs a compaction pass. Retained tokens move forward to fill the evicted slots, so trailing blocks empty out completely and return to the allocator, and the cache stays in position order.
On long reasoning traces, it matches full-attention accuracy with 2.5x faster decoding and 10.7x less KV memory.
For KV cache compression on a real server, the metric to track is blocks freed, not tokens evicted.
NVIDIA's write-up: https://t.co/ZwXv7VezVu
I also wrote a first-principles breakdown of the KV cache. It covers why the model caches keys and values, why the cache grows with every token, and how generation speed compares with and without caching.
Read it below.
pytorch interview speedrun.
5 questions. no googling.
1. what does model.eval() actually change?
2. why call optimizer .zero_grad()?
3. detach() vs no_grad()?
4. why does CrossEntropyLoss expect logits?
5. what happens if you forget loss.backward()?
how many can you answer correctly?
answers in replies.
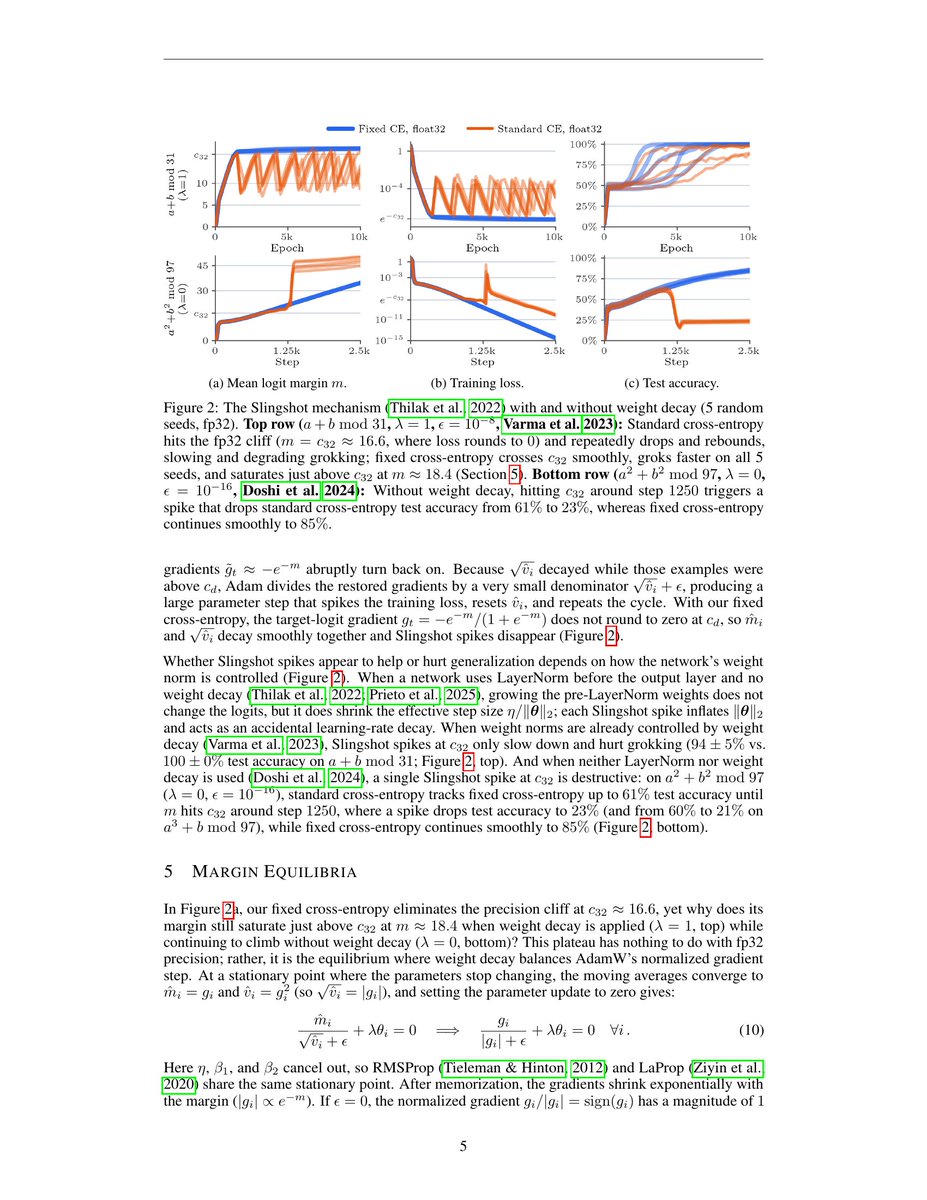
Cool! We derived an AdamW batch-size scaling rule in Lemma 3.13 of https://t.co/zeTw8E1KtQ
B → B × k
𝗟𝗥 → 𝗟𝗥 × sqrt(𝗸)
𝗪𝗗 → 𝗪𝗗 × sqrt(𝗸)
βᵢ → 1 − sqrt(k) × (1 − βᵢ)
This was subsequently validated empirically in an ICLR 2026 paper:
https://t.co/JFC7D9LDzF
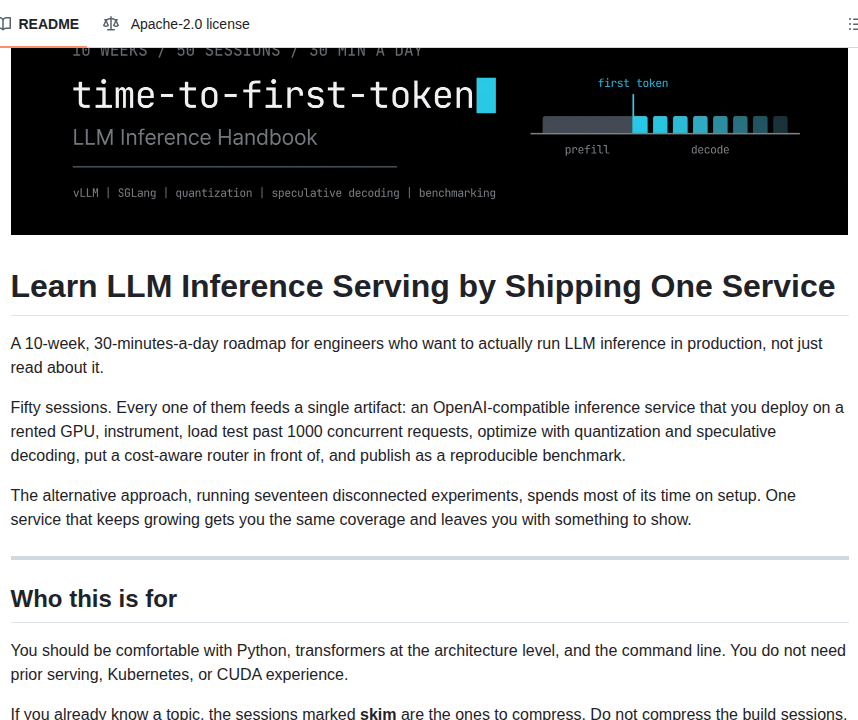
As an AI Infrastructure Engineer, you must build these projects.
1.) High-Throughput Serving Engine Tuning
Build: Deploy vLLM or SGLang, tuning chunked prefill, continuous batching and max-num-seqs for a specific GPU architecture.
Why: Default configs waste 60% of VRAM. Squeezing the hardware is the baseline job.
2.) KV-Cache Prefix Routing Proxy
Build: A load balancer that hashes incoming system prompts and routes requests to the specific replica holding that KV-cache block in memory.
Why: Reused context is free speed. This alone can slash Time-To-First-Token (TTFT) by 80%.
3.) Custom Fused Triton Kernel
Build: Write a fused RMSNorm or RoPE (Rotary Position Embedding) kernel in Triton and benchmark it against the native PyTorch implementation.
Why: Python overhead and memory reads kill inference. Fused kernels save milliseconds that compound at scale.
4.) Speculative Decoding Pipeline
Build: A serving setup where a local 2B "draft" model generates tokens in parallel and a 70B "target" model verifies them in a single forward pass.
Why: 2x decode speed at zero quality loss is the closest thing to a free lunch in inference.
5.) Disaggregated Prefill/Decode Cluster
Build: Separate GPU pools where compute-heavy prefills and memory-bound decodes are routed to different hardware optimized for each phase.
Why: This is the exact architecture frontier labs use to maximize MFU (Model Flops Utilization) in 2026.
6.) FP8 Quantization & Calibration Harness
Build: A pipeline that calibrates a model for FP8 inference, serves it via TensorRT-LLM and measures the exact perplexity drop against throughput gains.
Why: Quantization is the only way to fit frontier models on edge GPUs and protect your cloud margins.
7.) Queue-Based GPU Autoscaler (KEDA)
Build: An autoscaler that spins up spot GPU nodes based on pending token queue depth and gracefully drains them when the queue empties.
Why: Idle H100s burn $3+/hr. FinOps and scheduling are now core infra responsibilities.
8.) Complexity-Routing AI Gateway
Build: A proxy that analyzes prompt entropy and token length to instantly route simple queries to a quantized local 8B model and complex reasoning to a frontier API.
Why: Unit economics decide if your AI product survives the next API price hike.
9.) Multi-Node Tensor Parallelism Setup
Build: Shard a 70B+ parameter model across 4 nodes using NCCL over RDMA/RoCE v2 and profile the exact network bottleneck between GPUs.
Why: Single-node inference is dead for frontier models. You must master the interconnect.
10.) Semantic Cache Layer
Build: A Redis + Vector DB proxy that intercepts requests, checks for >98% embedding similarity, and returns cached outputs without hitting the GPU.
Why: The cheapest and fastest token is the one you never generate.
11.) DCGM Observability & Throttling Dashboard
Build: A Grafana stack tracking GPU temp, SM occupancy, VRAM OOMs and PCIe TX/RX to catch silent hardware throttling.
Why: You cannot fix an SLO violation if your dashboard only shows HTTP 200s while the GPU is melting.
12.) MoE (Mixture of Experts) Load Profiler
Build: An expert-parallel deployment tracking token-to-expert routing to identify and fix expert load imbalance and communication overhead.
Why: Sparse MoE models are the 2026 standard, and naive routing destroys their latency advantage.
13.) Inference Chaos & Fault Tolerance Suite
Build: A harness that injects network partitions, simulated GPU ECC errors, and OOMs to test the cluster's ability to migrate KV-caches and recover.
Why: At scale, hardware fails daily. Your architecture must heal itself.
14.) Checkpointing & Weight Streaming Engine
Build: A system that streams model weights directly from an S3 bucket to GPU VRAM on cold-start, bypassing local disk bottlenecks.
Why: Cold-start latency kills autoscaling. Streaming weights directly to memory is the ultimate optimization.
15.) Public Inference Benchmark Teardown
Build: 3 published deep-dives with Pareto curves (Cost vs TTFT vs Throughput) comparing vLLM vs SGLang vs TensorRT-LLM on your specific hardware.
Why: Public proof of hardware mastery and methodology gets you hired instantly by top AI labs.
Systems that prove you can serve, optimize & scale when silicon meets intelligence.
Bookmark & Repost.