🦆 Announcing DuckDB 2.0.0 LTS “Cinnamon Teal”
We are proud to release DuckDB 2.0.0, named after the cinnamon teal (Spatula cyanoptera), a striking reddish-brown duck found in the western Americas. 🌎
DuckDB 2.0.0 is the biggest DuckDB feature release so far. It ships a polished version of the Quack protocol, which turns DuckDB into a full-fledged server. It improves performance and lowers costs through supporting asynchronous I/O, a first-class VARIANT type, and a dedicated “agent mode”. It also empowers extension developers with a new SQL parser that allows adding new statements, clauses, and keywords, a new API to build on, and a new mechanism to distribute extensions more easily.
In our announcement blog post, we summarize the highlights and then walk through the key changes and give guidance on how to migrate to 2.0. For the complete release notes, see the release page on GitHub.
https://t.co/QtT5wHhg2w
#DuckDB
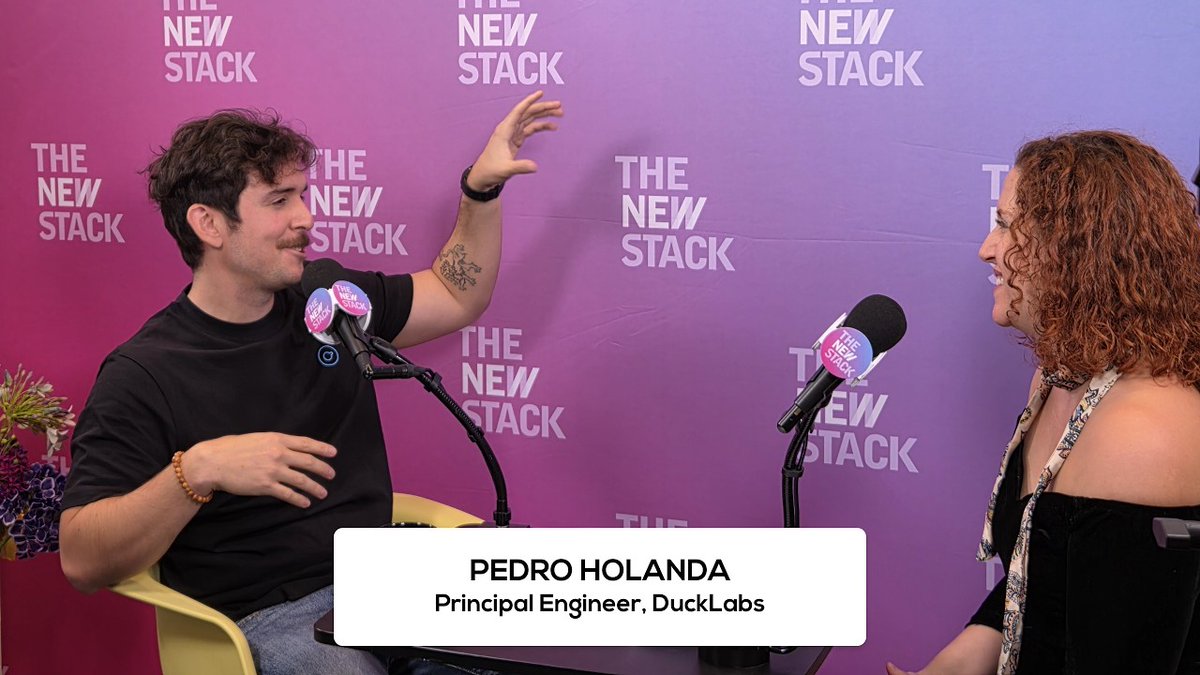
In this episode of @thenewstack Podcast, @holanda_pe , lead developer of DuckLake, discusses how the open lakehouse format stores table metadata in a SQL database instead of manifest files on object storage – and how this lets a single query find exactly which Parquet files to read.
Pedro also walks through the #DuckLake 1.1 release, which adds maintenance features such as file consolidation and data inlining to tackle the small files problem in streaming workloads.
Catch the episode here or wherever you get your podcasts: https://t.co/Cq85DzxJw7
Calling all DuckDB fans at re:Invent! Wrap up the week at the DuckDB Tailgate Party 🦆
Join AWS and DuckLabs for drinks and bites and exclusive DuckDB 2.0 swag. 📅 Thu, Dec 3, 5:30–7:30 PM PT 📍 The Stadium at The Venetian
Register: https://t.co/l5E7j2KhjP
From the @HonestNoBSData podcast:
Tables Rock & DuckDB with Hannes Mühleisen 🦆 🎧
Hannes Mühleisen, co-creator of DuckDB, joins @juansequeda and @TimGasper to discuss why tables keep coming back and how the pendulum always swings. They cover the background of #DuckDB, how it started, its internals, and when to use it (and when not to). And of course, a bit of discussion on AI.
Catch the episode here on YouTube, or wherever you get your podcasts: https://t.co/EZgBDMEybg
In case you’re really interested, here’s everything they discussed:
• Tables as the basic abstraction
• The pendulum from schemaless back to schema
• Physics and performance
• Install experience drives adoption
• Scale up versus scale out
• When to use DuckDB
• Graphs
• Governance of local compute
• Semantics belongs to other layers
• AI and agents
• Building a database company
• Do we need more database systems?
Last week, the DuckDB User Group held its first workshop in Amsterdam with Pratik Patel from @huggingface leading the session.
In one afternoon, attendees built a pipeline that finds the products with falling ratings in 2.1 million Amazon reviews and explains why. #DuckDB did the filtering and an LLM summarized the complaints. At the end, each attendee had a Hugging Face Space they could call as an API.
Here’s what else you missed: https://t.co/eGSCD9mocJ
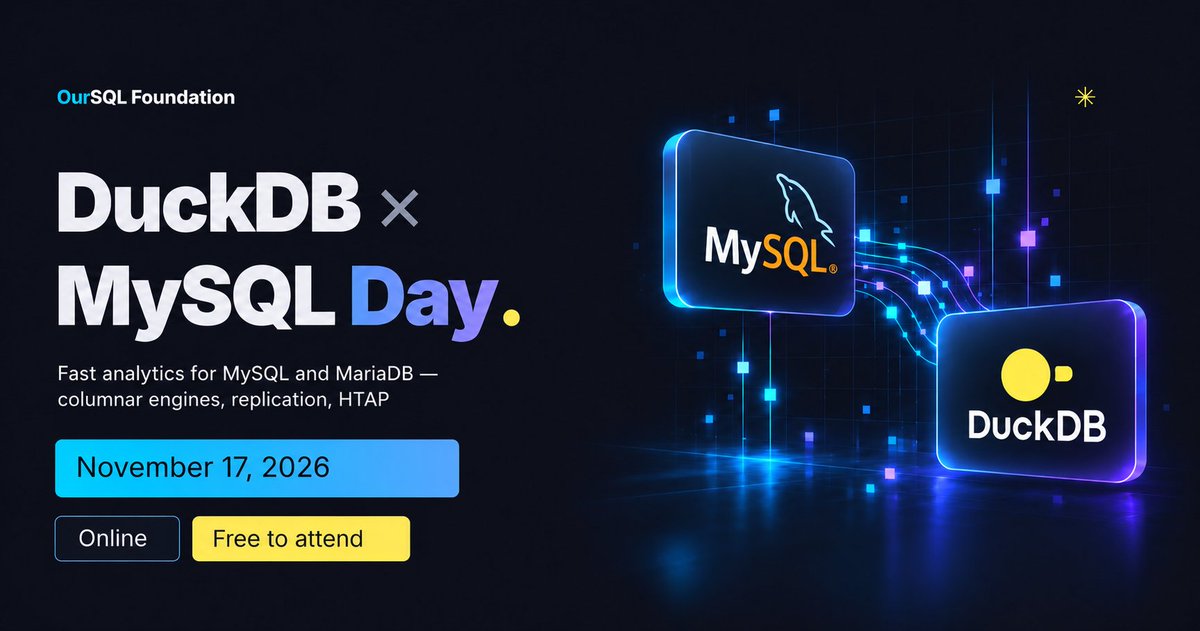
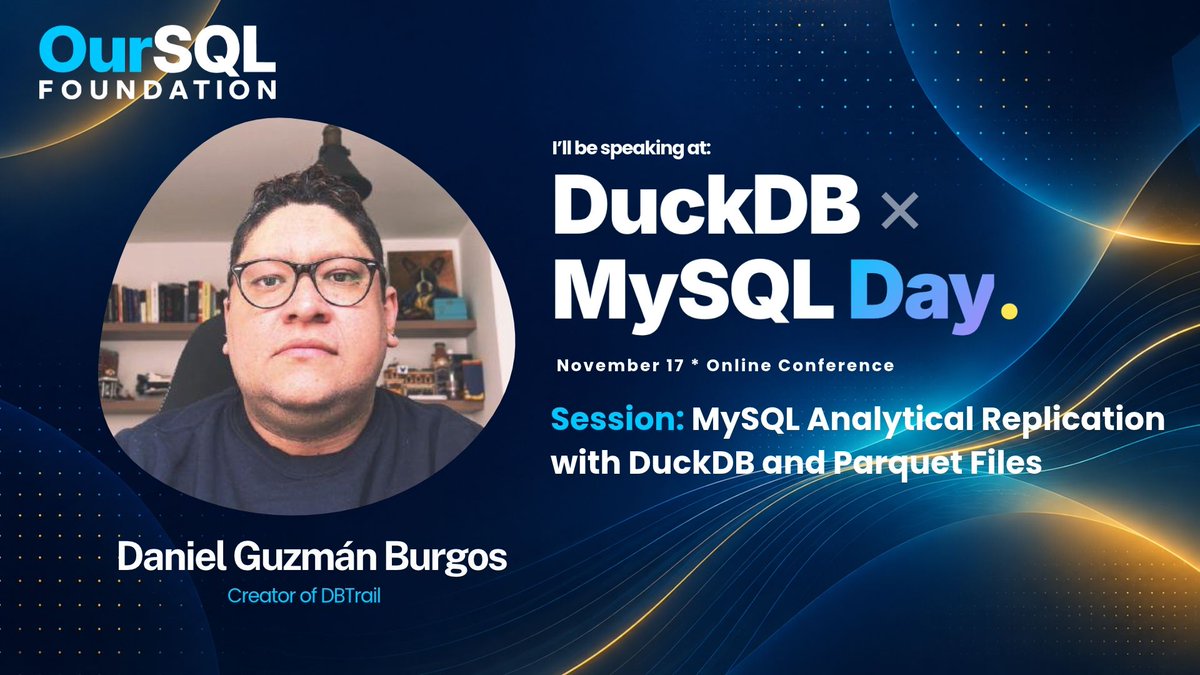
Last chance to register for DuckDB × MySQL Day! ‼️
Tomorrow (November 17th), @DuckDB is joining MySQL, MariaDB, and the @OurSQLFdn for a free online conference focused on what happens when DuckDB sits next to your transactional data.
Talks from builders and developers across the space will cover topics like:
• Columnar engines
• Analytical replication
• Parquet
• The road to HTAP and more
If you’ve ever wanted DuckDB working directly against production MySQL data, this conference is for you.
📅 17 November 2026
🕙 10:00 a.m. - 2 p.m. U.S. ET | 16:00 - 20:00 CET
🧑💻 100% Virtual / Online
Register today and we hope to see you soon: https://t.co/iGbK0ipDG3
#DuckDB #MySQL #MariaDB
Huey 1.2.000 - Laplaigne is now released - https://t.co/dyUblSwWwn
This fixes a few bugs, and upgrades DuckDB-WASM to 1.33.1-dev114.0 bringing you @DuckDB 2.0. Expect considerable speedup when analyzing parquet files in the cloud.
live demo: https://t.co/BefgA6T0AJ
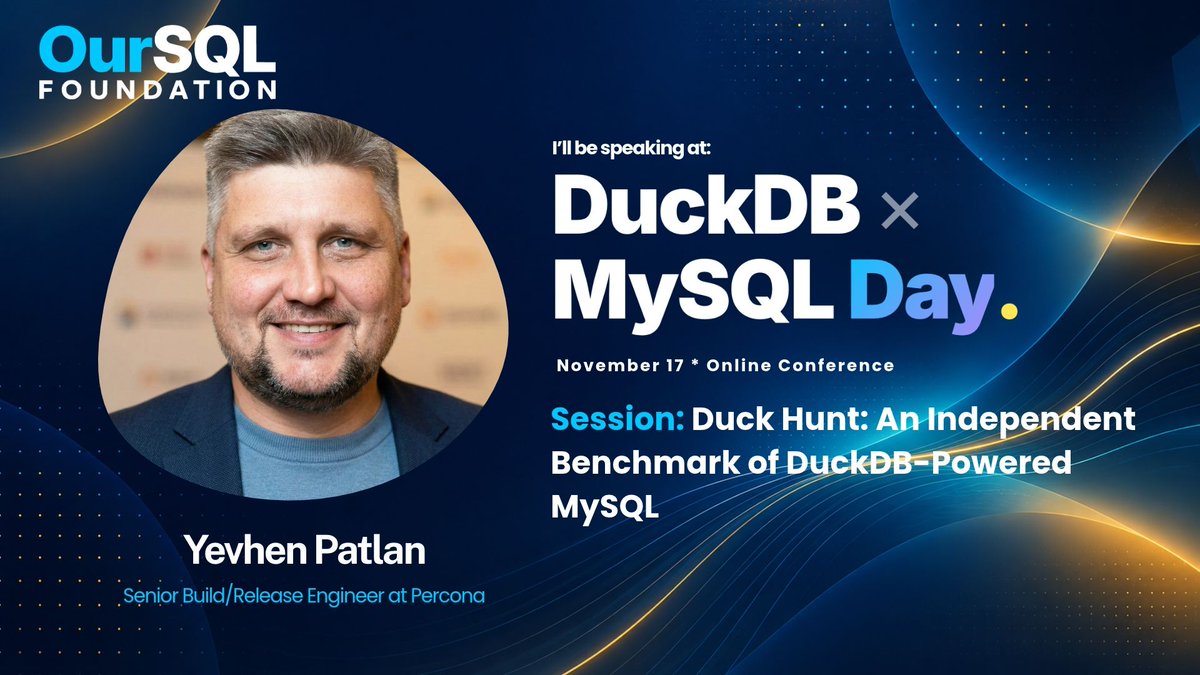
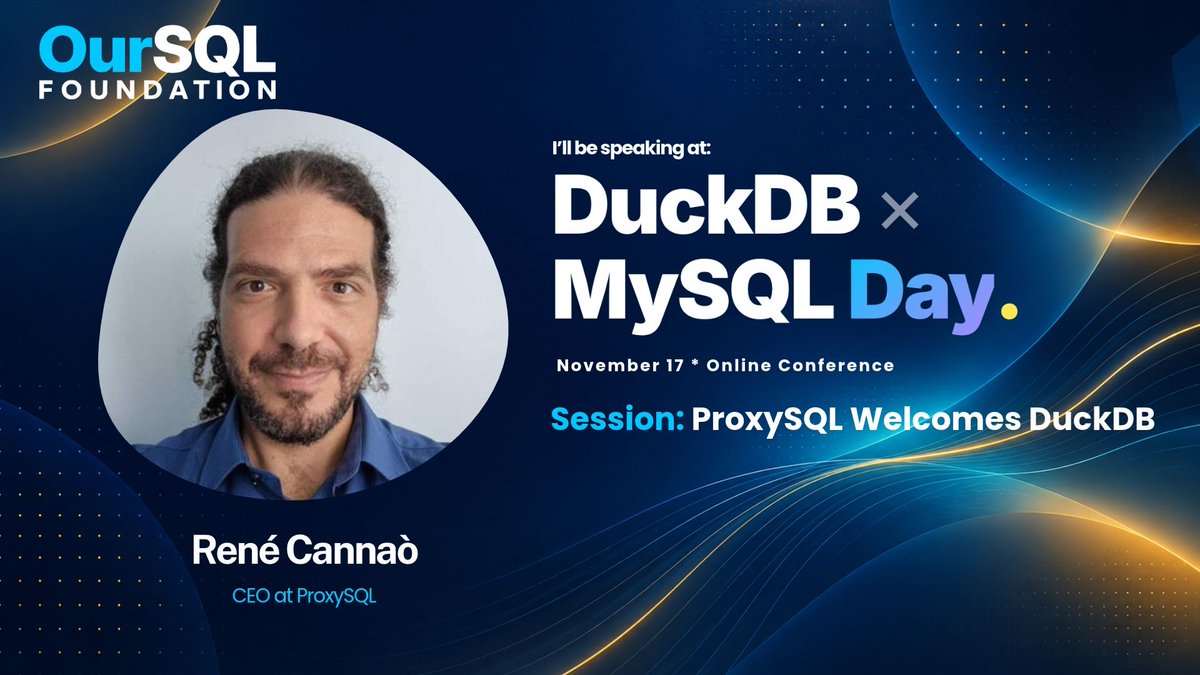
Look who’s lined up (so far) to speak at DuckDB × MySQL Day on 17 November! 👀
• @VadimTk | OurSQL Foundation
• @PeterZaitsev | @Percona
• Zongzhi Chen | Alibaba Cloud
• @deesix | VillageSQL
• Roman Nozdrin | @mariadb
• @clickslash | @dbtrail_
• Yevhen Patlan | Percona
• @rene_cannao | @proxysql
Watch this space as more speakers will be announced! 🦆 🐬 🦭
DuckDB × MySQL Day is a 1-day online conference organized by the @OurSQLFdn with the goal of bringing fast analytics to MySQL and MariaDB and presented by the people building the future of DuckDB working directly against production MySQL data. Come be inspired about how these technologies can work together in new ways.
📅 17 November 2026
🕙 10:00 a.m. - 2 p.m. U.S. ET | 16:00 - 20:00 CET
🧑💻 100% Virtual / Online
Register today and stay up to date with new speaker announcements: https://t.co/iGbK0ip5Qv
#DuckDB #MySQL #MariaDB
“You should own your data. It can live on your computer, not everything has to live in the cloud. It can be synced via the cloud, but you decide when to keep it local and when not.”
–@ilyabo , creator of SQLRooms
From interactive maps to graph exploration, DuckDB makes it possible to analyze data without a database server.
In this #DuckDB user story, Ilya Boyandin shares how this approach led to SQLRooms, a toolkit for building analytics applications that bring data, visualizations, and AI-assisted analysis together on the user’s machine.
Read the rest of Ilya’s DuckDB story: https://t.co/YkEEWUjtmi
Quack, quack! Join us for DuckDB × MySQL Day 🦆🐬🦭
This 1-day online conference organized by the @OurSQLFdn brings fast analytics to MySQL and MariaDB: columnar engines, analytical replication, Parquet, and the road to HTAP – all presented by the people building it.
If you’ve ever wanted DuckDB working directly against production MySQL data, this free event is for you.
📅 17 November 2026
🕙 10:00 a.m. - 2 p.m. U.S. ET | 16:00 - 20:00 CET
🧑💻 100% Virtual / Online
Explore the full list of speakers announced so far: https://t.co/iGbK0ip5Qv
#DuckDB #MySQL #MariaDB
It’s Time to Get Your Ducks in a Column
🦆
🦆
🦆
🦆
Why columns? DuckDB is fast – among other reasons – because of its columnar storage architecture.
DuckDB stores each column separately instead of storing each row as one record. A query that touches three columns out of 50 reads only those three. Columnar storage compresses well because a column holds values of one type, and those values often repeat. And a query that asks for fewer columns does less work.
This back-to-the-basics blog post covers DuckDB features that take advantage of that design choice: querying files in place, column-level SQL, aggregation shortcuts, window functions, ASOF joins, and writing well-organized Parquet. Also, the example is a dataset of 400 ducks, so
🦆
🦆
🦆
🦆
https://t.co/RwNiMfoDxV
🧑💻 DuckLabs is looking for a C++ software engineer.
🦆 Join our team in Amsterdam to build DuckDB and its extensions! You'll work on the database engine (from query execution and optimization to storage) and on DuckDB's ecosystem.
📝 Apply below!
https://t.co/MeU0r0Itdf
We shipped a new cross-database query functionality in our latest release. Here’s the story behind it, including why we embedded @duckdb, how it plugs into DataGrip’s query execution, and where it’s headed next.
Did you try using the errors_as_json flag?
SET errors_as_json = true;
memory D SET errors_as_json = true;
memory D sele;
{"exception_type":"Catalog","exception_message":"Table with name sele does not exist!\nDid you mean \"pg_sequence\"?","name":"sele","candidates":"pg_sequence","type":"Table","error_subtype":"MISSING_ENTRY"}
🧭 Are you feeling particularly adventurous? While DuckDB v2.1 "Islandica" is still a long way off, we've already started shipping preview builds for it, and you can try it out today.
Some highlights: better error messages, improved memory allocation and MATCH_RECOGNIZE support. Just don't deploy it to production yet! 🚧
https://t.co/pKh5zYsgfq
How @jetbrains Built Cross-Database Queries into DataGrip with DuckDB 🧠 🦆
JetBrains users had long asked to join data across different database connections in a single query. Rather than build its own cross-database query engine, JetBrains embedded #DuckDB in DataGrip, using DuckDB’s custom table functions to connect it to the IDE’s existing query execution.
This is why DuckDB won out over the alternatives, and where the integration goes next: https://t.co/3vaUCfV8r3
Bringing Local Analytics to the Quant’s Desktop 🧮
After years building data platforms for banks and hedge funds, Ryan Hamilton wanted an analytical engine he could recommend to smaller teams without specialized infrastructure or expensive licensing.
#DuckDB gave him a small, embedded way to bring fast local analytics into QStudio and Pulse, and it is now shaping his next open-source project, PeachQ.
Read the latest DuckDB user story: https://t.co/UnzjHzNXVf