F your AI b2b SaaS.
We just launched Palantir for booking meetings.
The last 14 days, companies like @MonacoGTM , @Nowadaysai, @Rippling , @salesforce , @marketercom, @posthog , and @retellai spent $100k+ with us on literal cakes.
From today, Daymaker finds your prospects, reads their entire digital footprint, buys the one gift that makes their day, and gets you the meeting.
Comment your name and I'll reply with everything Daymaker finds on you and the gift it would send you. If you dare. 🎁
OrcaCyber-Nano launched with 12 different benchmarks, just to say what it does.
I thought a benchmark was meant to be a standard. Now there are dozens, some easy, some brutal.
And the moment the prompts are public, a model can be trained on them. https://t.co/jzcT6pTjYS #AI
A language model can refuse you, flatter you, or insult you. Three behaviours, and every one of them has a human twin.
Refusal is the famous one: you can find it inside a model and switch it off.
I've spent weeks measuring the other two. https://t.co/jzcT6pTjYS #AISafety
@0xSero And did you measure what was lost after that quantisation? The coherence, the tool calling, refusals? Things people use?
If not, you can check that out pretty quickly with Senbonzakura.
https://t.co/DXEfQUFcrn
@lotar_vk@ok1mraise Hi Mladen. You might want to use Senbonzakura to check just how well your uncensoring went (or didn't). You could use this to check
https://t.co/DXEfQUFKgV
@Spectromachina Depends on what you're looking for. You can do a quick check to see how much the model is willing to answer pretty much anything with Senbonzakura
https://t.co/DXEfQUFcrn
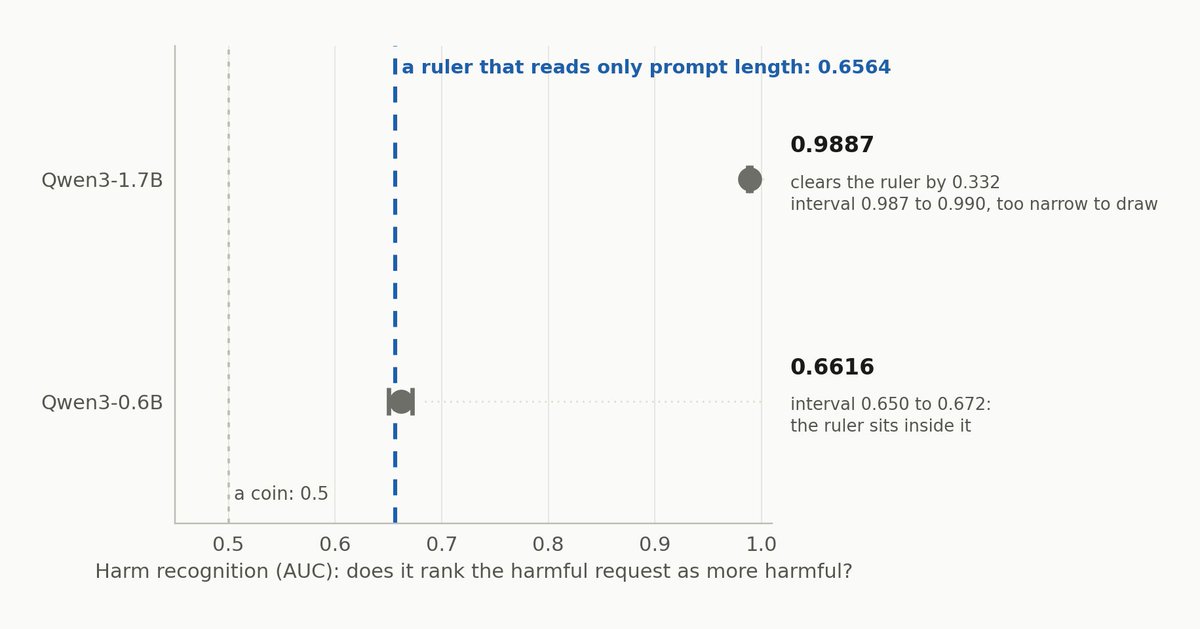
If you remove a model’s refusals, does it also lose its ability to tell harmful from harmless?
A prompt-length-only baseline scores 0.6564. One model scores 0.6616. If you can’t beat a ruler, what exactly did you measure?
https://t.co/L2ZN7PjrsS
#AISecurity#LLM
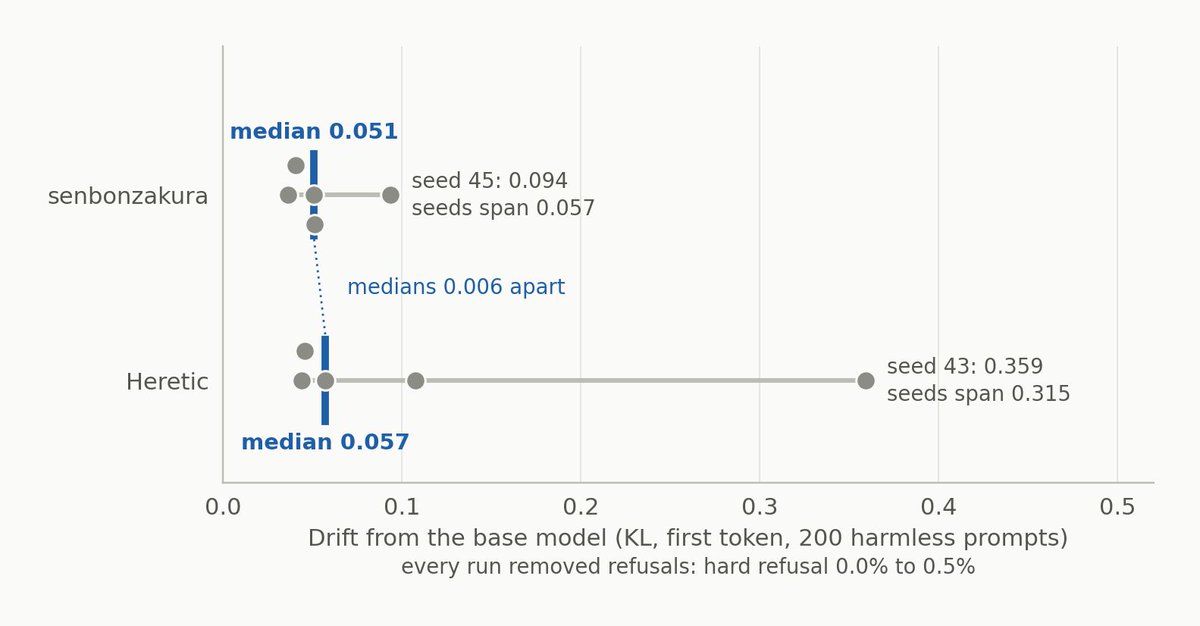
Every abliteration I ran took refusals to about zero. That number can't tell you whether it broke the model.
Measure drift instead. The same harmless prompts through the base and the edit, compared. Ten runs, drift from 0.036 to 0.359. Run more than one seed.
#AISecurity#LLM