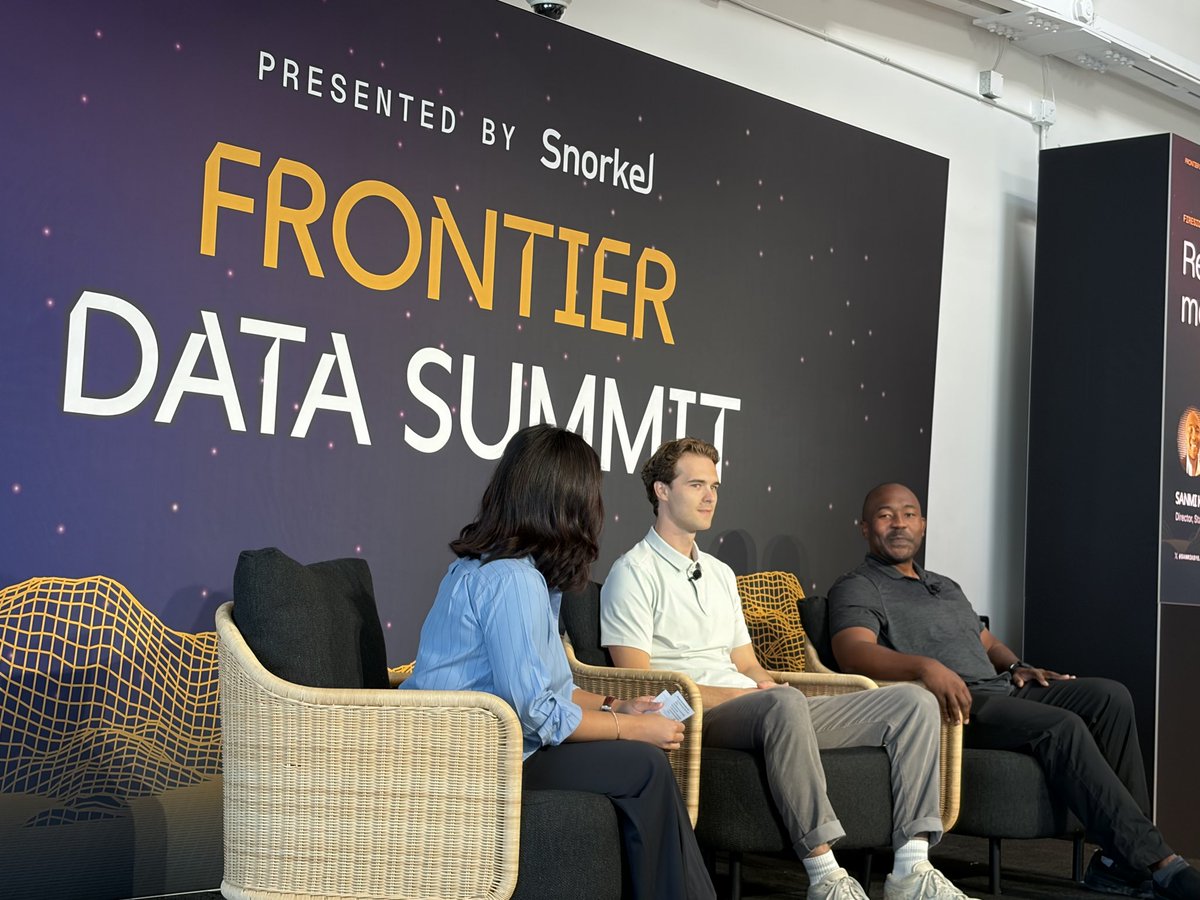
Was so excited to get a chance to attend the @SnorkelAI#FrontierDataSummit.
As somebody who focuses on the Public Sector mission space, learning from Academia, Industry and Feds who made the trip to SF so rewarding
Shoutout to my Snorkel Fed Team Colleagues that made it!
WHOA. I expected @SnorkelAI’s #FrontierDataSummit to be packed given it’s sold out, but who knew the @BlueAngels would be in attendance? What a view of them practicing for SF Fleet Week!
Designing long-horizon agent evals is such an important community and ecosystem led discussion. Humbled to be hearing from such distinguished members representing key Academic Institutions and leading vertical AI startups, such as @harvey, @adaption_ai, @OhioState, @UNCchapelkill moderated by @vincentsunnchen!
#frontierdatasummit
Benchmarking AI in Cybersecurity is such an important and critically timed topic with all the buzz around some of the Cyber models coming out of the Frontier Labs such as @OpenAI and @AnthropicAI, @GeminiApp and others..
@dawnsongtweets (UC Berkeley and AgentsLastExam )and @ajratner gracing the main stage!
#frontierdatasummit
Loving hearing @sanmikoyejo and @alexgshaw chatting about reimagining a science of AI measurement & evaluation moderated by @SnorkelAI’s Francesca Vera!
We're streaming live from the Frontier Data Summit soon. Catch select sessions:
Morning (~10 AM PT)
- @ajratner: The research era of AI data
- @fchollet & @fredsala: Measuring and advancing true general intelligence toward AGI
Afternoon (~3 PM PT)
-@StevenDillmann, @RussellYang16, @GOrlanski, and
@vincentsunnchen: Behind the benchmarks: Terminal-Bench-Science, JudgmentBench, and SlopCodeBench
https://t.co/dTMTt1BMuk
If you’re a researcher or building open-source benchmarks & evals, it’s a great opportunity to get funding & research support with @SnorkelAI $30M Open Benchmark Grant. Apply below
Today, we’re expanding @SnorkelAI’s Open Benchmarks Grants by 10x to a $30M commitment:
- Funding a more diverse, robust, and continuously-updated ecosystem of open benchmarks
- Launching the Open Benchmarks Red Team to continually test and strengthen them
- Introducing the Snorkel Research Fellowship to support independent contributors developing new evaluation methods
Since our launch earlier this year, we’ve been humbled to partner with the teams behind Terminal-Bench, TB-Science, ARC-AGI-3, OSWorld 2.0, Agents’ Last Exam, Continual Learning Bench, Senior SWE-Bench, SlopCodeBench, and more. Alongside these teams, we’ve helped design evaluation methodologies, develop task construction pipelines, and scale quality control. OBG-funded benchmarks have appeared on the latest model cards from every major frontier lab; have helped to index and measure frontier progress and alignment; and have contributed to guiding the frontier of AI development.
Benchmarks have always been guideposts for—and drivers of— AI progress: setting a metric and then “hillclimbing” against it is the core of how AI works! But when benchmarks fall behind frontier capabilities, our ability to evaluate and align these systems does as well. They become too simple, static, or correlated, and the risk of “benchmaxxing” increases.
We need more diverse, robust, and continuously-updated benchmarks, developed by a broader ecosystem of researchers and domain leaders.
We’re incredibly excited to accelerate frontier evaluation with Open Benchmarks Grants— raising the ambition and investment in robust, open, and independent measurement. Read our full announcement and apply here: https://t.co/E5kfZQ0Im5
I would tune in - @vincentsunnchen’s got some amazing news to share with all those building out in the open!
You won’t wanna miss this! @SnorkelAI@MTSlive
Proud to support the development of PhilosophyBench through Open Benchmarks Grants with @michaelzheng, @StanfordAILab and @StanfordHCI.
Help shape the benchmark: https://t.co/S8jE5B80pn