@thingslist found out my agent was performing worse not because the model got dumber but because the context was so bloated the relevant facts were getting lost in the noise https://t.co/kTamT97zAo
Massive SHOUT OUT to the most talented @suji_pop
Bringing a piece of @TenseiExe into our shinigami realm universe. "Shinigami developed by SujiCorp. A biotech weapon for mass killing" - Sujipop
Drop a comment below on how we could give this away to the @ShiniRealms community.
@MrrrOzi@MicroStrategy enterprise ai without audit trails is just not enterprise ready. the question isnt whether you need them. its whether your memory system provides them
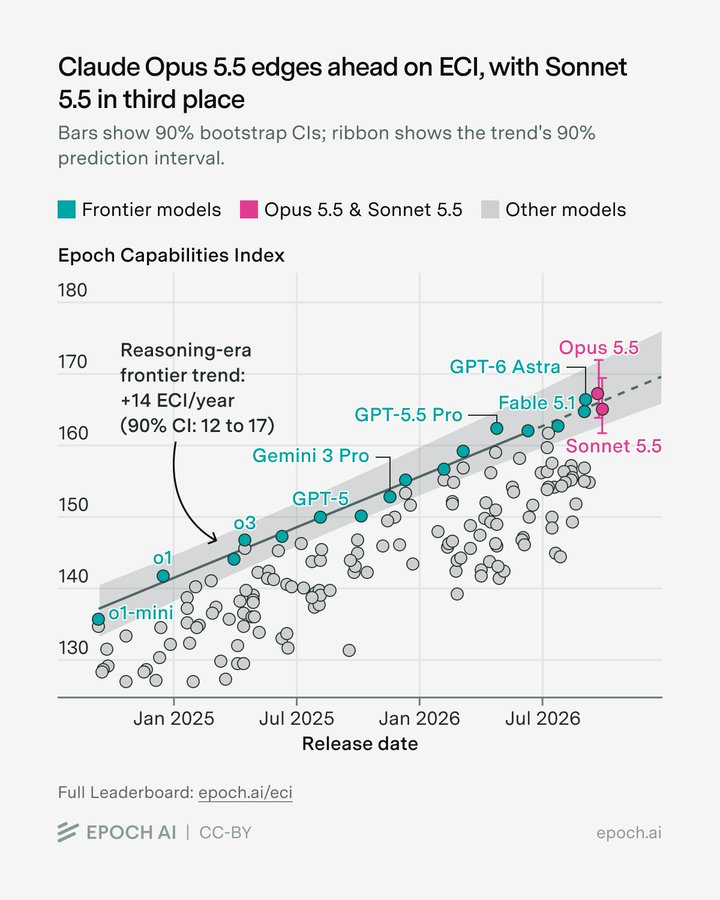
"Claude Sonnet 5.5 has roughly matched Claude Fable 5.1 (165)."
Anthropics mid-size model (!) now matches it state of the art and probably the best model in the world within just a few months of release.
I am so excited for Fable 5.5, you have no idea.
@im_pranavkakde receipts instead of trust. atomic memory cloud gives you the receipts for every single thing your agent has ever stored updated or retrieved
@dezign_ash@vicky_grok the audit trail in atomic memory cloud isnt just for debugging. its for accountability. being able to show exactly what the agent believed at any point in time is genuinely powerful
https://t.co/kTamT97zAo
Persistent cross session memory. write-time classification. full retrieval traces.
100% traced mutations. self-hostable, apache 2.0, free to start. works with claude code, cursor, and most major setups
https://t.co/kTamT97zAo
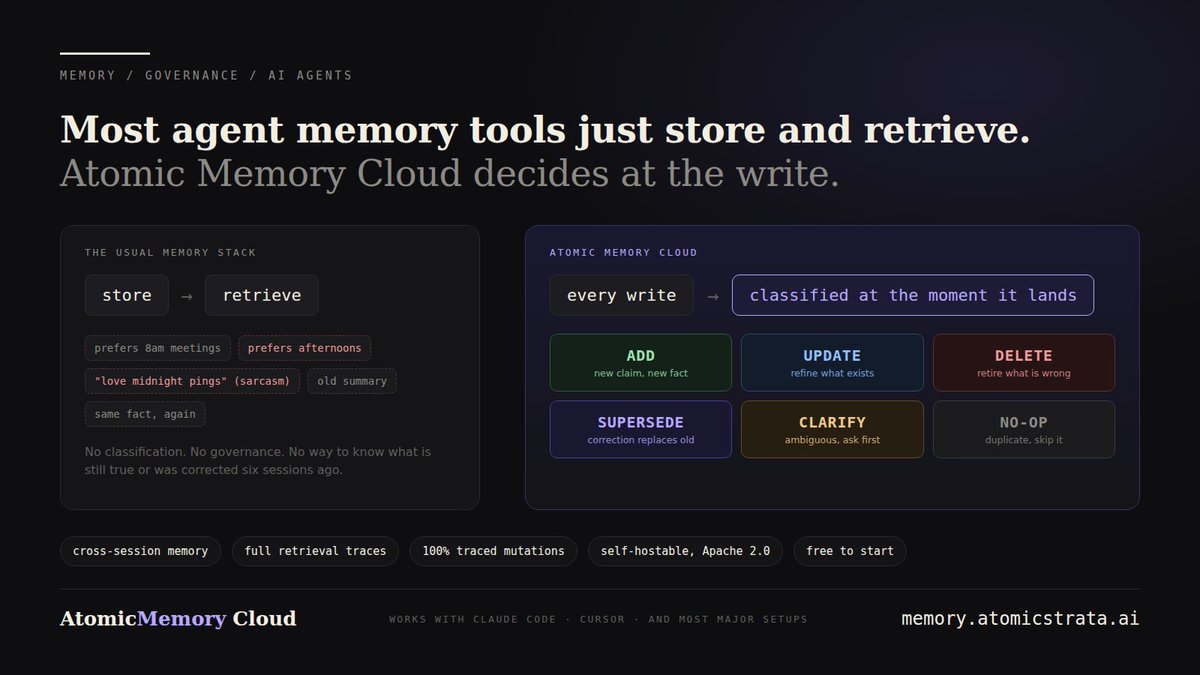
So most agent memory tools do two things. store. retrieve.
That's it no classification no governance no way to know if what gets retrieved is still accurate, still relevant, or was corrected six sessions ago
Where a Atomic memory cloud classifies every write at the point it lands. not after the fact. not at retrieval time.
At the moment of writing. add, update, delete, supersede, clarify, or no-op. what your agent believes stays coherent over time
@thingslist write time classification means junk never lands in the store in the first place. no-op on duplicates. supersession on stale facts. what reaches retrieval is already clean https://t.co/kTamT97zAo
@AviPilcer bigger context window doesnt solve bloat. it just delays when the model gets confused. the fix is retrieving the right things not more things https://t.co/kTamT97zAo
@AIBrosPod token budgeted context packaging that shows you exactly whats included and whats left out is one of those features that sounds small until you realize how much it changes things https://t.co/kTamT97zAo
@Neuron_Edge@WalrusProtocol vendor lock-in in memory infrastructure is scarier than anywhere else because your entire agent state lives there. apache 2.0 and self hostable is the only acceptable answer https://t.co/kTamT97zAo
@oceanbennett@garrytan@bizwithnish@AsideAI switched from a proprietary memory provider mostly because i wanted out of the vendor relationship. apache 2.0 self hostable same backend path. best decision https://t.co/kTamT97zAo
@danizhu@kaiiijju the open source core being free forever isnt just a pricing thing. its a trust thing. you can always move to self hosting without losing anything https://t.co/kTamT97zAo
@garrytan started with a hosted memory provider. six months later wanted to self host. was basically told it wasnt possible without rewriting the integration. never again. atomic memory cloud same sdk both ways https://t.co/kTamT97zAo