As expected, Kimi 3.1 Pro distilled US frontier models to train their models. This time they distilled GPT-6 Astra.
The damage to Kimi’s reputation keeps growing. Via the information
🔴 ¡NUEVO GEMINI 4 CARBON!
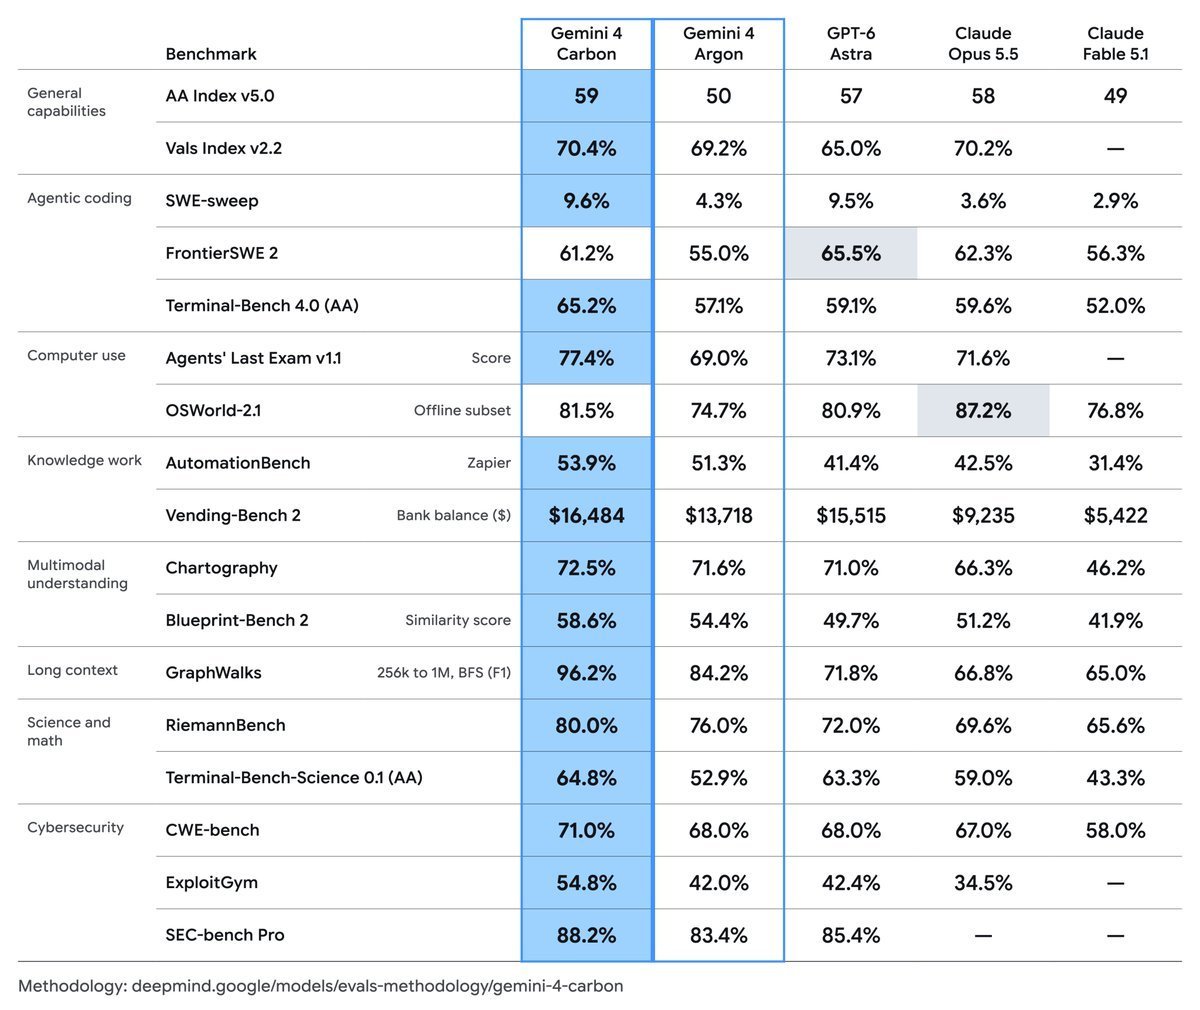
Google golpea por segunda vez este mes, tras la salida de su modelo Argon, con una nueva versión entendemos más grande y sobretodo, potente. Superando en muchos benchmarks a Opus 5.5 y a GPT-6 Astra!
Por ahora es el anuncio del modelo, sin acceso.
I did say we'd be releasing our models periodically...introducing Gemini 4 Carbon, our next frontier model.
Following Argon's release just two weeks ago, Carbon shows the pace at which we’re pushing the frontier, it ranks #1 on the recently updated v5.0 of @ArtificialAnlys Intelligence Index at 59. It also leads across key cybersecurity evaluations scoring 88.2% on SEC-bench Pro for finding vulnerabilities, 54.8% on ExploitGym for exploitation, and 71.0% on CWE-bench for patching.
We’re seeing significant improvements in long-horizon tasks even compared to Argon, and we’ve strengthened frontier safeguards.
As we did with Argon, we’re going to roll it out gradually + responsibly. Some trusted cyber defenders will get access starting this week. We'll be expanding it to more partners through our Fairwind Program, ahead of wider availability soon, so hang tight!
Introducing Gemini 4 Carbon, our latest frontier model.
Carbon delivers improved performance across domains — ranking #1 on v5.0 of the @ArtificialAnlys Intelligence Index and sets a new state-of-the-art in cybersecurity and long-horizon capabilities.
It’s rolling out starting this week to cyber defenders through our Fairwind Program, with expanded access coming soon 🧵
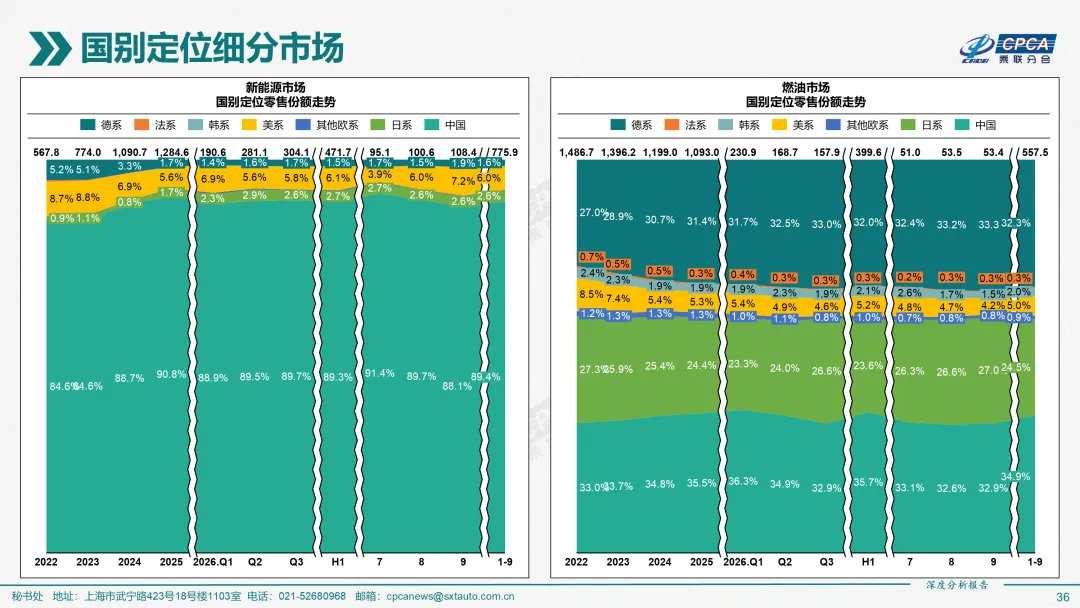
China's domestic mkt share by automaker country of origin for NEVs & ICE
Note, there is not much change bw the 2 for the past couple of yrs.
It's just the NEV mkt is now 2x the ICE mkt.
@Alejandroperez Como Mbappé ya se disculpó, dudo que el asunto pase a mayores, a menos que ocurra otro incidente similar. Eso sí, debieron llevarse un buen susto al ver que todo ese dinero podía esfumarse de un momento a otro.
@OficialYuan Insultas a China → China responde. La gente: «¡¿Cómo se atreven?! ¡No nos dejan difamarla! ¡Tenemos mejores valores y somos mejores!».
Es simple: no te metas con China y China no se mete contigo. Insulta a tus líderes o a otros países, pero no esperes aplausos de China.
MiniMax M3.1 Flash meets the @UnslothAI community. 🐙🦥✨
Unsloth’s Dynamic GGUFs bring our 428B MoE model to a 143.9GB 2-bit footprint, with 91.5% top-1 token agreement in their evaluation across seven domains.
That means a lower memory barrier to self-hosting, deployment through Unsloth Desktop and llama.cpp, and an OpenAI-compatible API for existing apps and agents.
With 78K+ GitHub stars and over 500M model downloads on Hugging Face, Unsloth gives M3.1 Flash a path into an established community of developers running, evaluating and building with open models.
Open weights. Local control. More ways to build.
China's monthly export growth from 2019 until now.
Note the fastest & slowest growing countries here. Mostly global south countries in the former & Global north countries in the latter. I'm surprised US figures even grew tbh
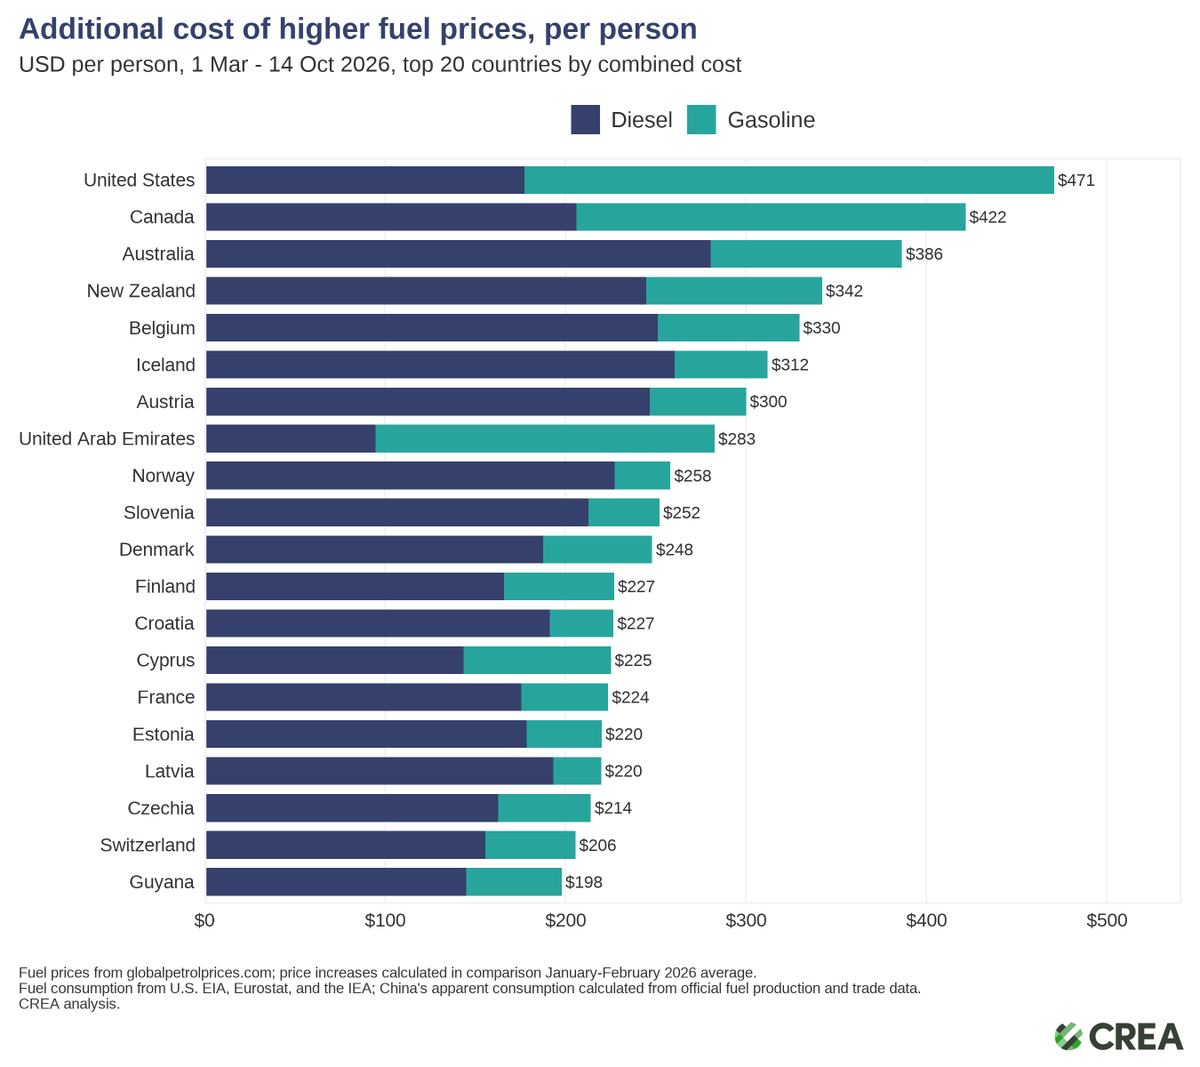
New from me: The US has faced a higher cost than any other country from the global Hormuz oil shock, with the crisis adding $160 billion to its fuel bill — or $471 per person on average — despite being the world’s largest oil producer.
Hy-SimulMT is now open source! 🚀
Tencent HY’s real-time Chinese ↔ English Simultaneous Interpreting Model.
Key features:
⚡ Low latency (~3s)
🎯 High accuracy
🎙️ Real-time voice cloning
🏆 Outperforms most open-source models and commercial APIs
Download, try, and build with it! 👇:
Hugging Face: https://t.co/8roZj3dMha
ModelScope: https://t.co/hCgvEK5KqP
GitHub: https://t.co/sWvZMeKSGB
More reference control. Fewer denoising steps. More places to run H3.
The latest community contributions span 8-step reference-conditioned video + audio, 4-step distillation, sparse attention, and reference-token compression - alongside serving and workflow integrations across GPU servers, TPUs, and Apple Silicon.
What matters is what this enables: more affordable experimentation, finer creative control, and more choices about where and how video generation runs. Open models become more useful when the community can improve the methods, adapt the runtime, and build workflows around them.
Credit to @haoailab@yisun0618@lanfeng491270@guocheng_qian@Alissonerdx@ddalcu@tazmannner@HaochengXiUCB@huggingface@Jhuaplin, and the PTD, DMAD, SparkH3, TorchTPU and FlashML teams - including Zhengming Yu and zechengtang on GitHub.
11 additions to the H3 ecosystem index. Thank you to everyone building, testing, and sharing.
https://t.co/F1S5IjUNi1
The issue is not unnecessary quota consumption, but the how expensive your plan is. I somehow use up my entire month of quote on just Kimi 2.8 (you know, the "cheap model") just gathering articles. DeepSeek Flash has caught up to ur flagship model in SWE & ahead of your cheap model in other areas.
You need to figure out how to serve your models more efficiently, have less latency issues & make your coding plans better deals.
Kimi K3.1 Pro (Max) by @Kimi_Moonshot just landed in the Agent Arena at #11 with +7.6% net improvement across +4K real-world agentic sessions from our global community of users.
Kimi K3.1 Pro (Max) would be the new #1 open model in the Agent Arena overtaking DeepSeek-v4.1-Flash! Open weights coming soon, stay tuned.
Kimi K3.1 Pro (Max) is a +6 percentage pt improvement over Kimi K3 (Max) at +1.6% (#25 -> #11). And with a $1.03 median cost per task in Agent Arena, Kimi K3.1 Pro is 13% less than its previous variant. See its placement just off the Pareto frontier in thread.
Across Agent Arena categories, Kimi K3.1 Pro (Max) ranks #8 in Work, #9 in Code, and #10 in Chat.
By signal, it’s the strongest in Praise vs. Complaint (implicit sentiment in user reactions) with +19% at #8. Across other signals it landed:
- #11 in Steerability (+8.3%)
- #15 in Bash Reliability (+8.3%)
- #26 in Confirmed Success (+2%)
Huge congrats to the @Kimi_Moonshot team on this release!
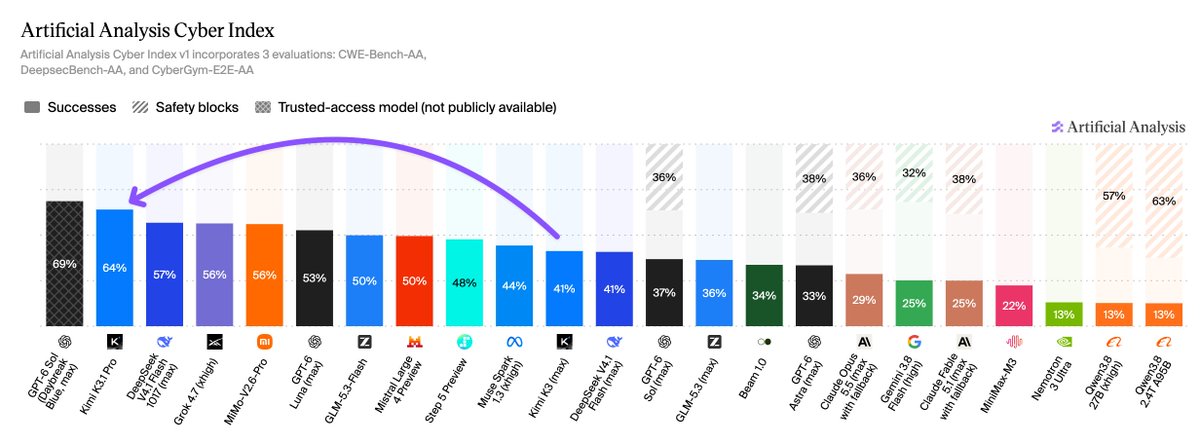
Kimi K3.1 Pro is the new #1 openly-available model for agentic cyber defense, behind only trusted-access model GPT-6 Sol (Daybreak Blue) on the Artificial Analysis Cyber Index
@Kimi_Moonshot's Kimi K3.1 Pro scores 64% on the Artificial Analysis Cyber Index, 7 points ahead of the previous leading openly-available model, DeepSeek V4.1 Flash 1017 (57%), and 5 points behind GPT-6 Sol (Daybreak Blue, max, 69%), which is only available through OpenAI's trusted-access program. Once the weights for K3.1 Pro are released, K3.1 Pro will also be the leading open weights model for cyber defense.
The Artificial Analysis Cyber Index measures capability on agentic cyber defense tasks and is composed of three benchmarks: CWE-Bench-AA, DeepsecBench-AA and CyberGym-E2E-AA. The Index primarily evaluates models through their publicly accessible APIs, reflecting the cyber capabilities available to developers.
Proprietary models from OpenAI, Anthropic and Google may have stronger cyber capabilities but lose points to safety refusals: GPT-6 Sol (Daybreak Blue, max), available through OpenAI's trusted-access program, scores 32 points above its public counterpart. Kimi K3.1 Pro encounters no safety refusals.
Key results:
➤ #1 openly-available model and #2 overall: Kimi K3.1 Pro scores 64%, up 23 points from Kimi K3 (41%) and ahead of DeepSeek V4.1 Flash 1017 (57%). Only the trusted-access GPT-6 Sol (Daybreak Blue, max, 69%) scores higher
➤ Highest CyberGym-E2E-AA score of any model: K3.1 Pro scores 95% on CyberGym-E2E-AA, placing it ahead of GPT-6 Sol (Daybreak Blue, 93%) and the next openly-available model, Mistral Large 4 (82%). On DeepsecBench-AA, K3.1 Pro scores 37%, behind GPT-6 Sol (Daybreak Blue, 48%) and GPT-6 Sol (46%). On CWE-Bench-AA it scores 61%, 4 points behind GPT-6 Sol (Daybreak Blue, 65%), with DeepSeek V4.1 Flash 1017 leading at 69%
➤ 15% increase in Cost per Task despite lower token prices: K3.1 Pro has a Cost per Task of $2.81, higher than GPT-6 Sol (Daybreak Blue, max, $1.77) and DeepSeek V4.1 Flash 1017 ($0.42). Kimi K3.1 Pro is 33% cheaper per token than Kimi K3 ($2/$10 vs. $3/$15 per 1M input/output tokens), but uses ~2x more input tokens, resulting in a 15% higher Cost per Task ($2.81 vs. $2.45)
This is INSANE.
Kimi K3.1 is here, and we finally have an open-source model competing at Opus 5.5 , Fable 5.1 and GPT 6 Astra
Open weights expected by November 4, 2026.