@mfranz_on No 200 GBE networking chip. Only 10G ethernet.
The networking chip alone is worth $1800 on the Spark.
The Spark also has 4 TB Gen ssd.
The Halo is 2 TB gen 4
Amd Halo also has a much weaker gpu with no fp8 an no fp4 support.
@Da7_Tech Opus nerfs, astra nerfs… endless cycle. At least open source goes in same direction, always forward. 6 months behind ! Who cares, at some point will be enough power at the table for no close source at all
single most useful thing for my local ai setup that made life easy is my 2x DGX Spark becoming one serving box for every device i own
here is how i do it:
> 1. the two sparks run one vLLM server together with one endpoint, i use dgx sparks, you can use any nodes that can run an llm
> 2. install tailscale to have all your nodes and machines on the same tailnet, the endpoint lives there so every device reaches it from anywhere and no port is open to the internet
> 3. that one tailnet endpoint with the exposed port is your base url for everything, it speaks OpenAI chat, OpenAI Responses and Anthropic Messages, so any chat app, coding agent or phone bot you point at it talks to the same model
> 4. the server also answers to the name "local", so clients can ask for "local" instead of a model name and when i swap the model on the servers nothing on the devices needs a config change. right now it's serving GLM 5.3-Flash, next week it can be something else
this video below is the whole thing running end to end, orange dots are requests going in, white and green are tokens coming back
it takes however many requests you throw at it, your config decides how many run at once and the rest wait their turn, when several run together each request's tok/s drops a bit while the box moves more tokens in total. mine is set to one at a time right now, so when every device fires together they queue up
this setup really improved my quality of life with local ai, if you get stuck anywhere setting it up leave a comment and i'll help you
@NVIDIARTXSpark It’s time to get out of the personal computer business—and after the unacceptable move you made today, drop the personal chip business as well. A company that takes such steps for a 64GB model no longer has a place in the personal computer world. No more Nvidia at all. Dead !
@MichaelGannotti Nvidia became the NerfBench champion. They chose to take advantage of people. From now on, they can go sell servers to the big players. I was expecting to buy 3rd and 4th sparks, but I’ve definitely given up on Nvidia now. I’ll act against them everywhere and at all times.
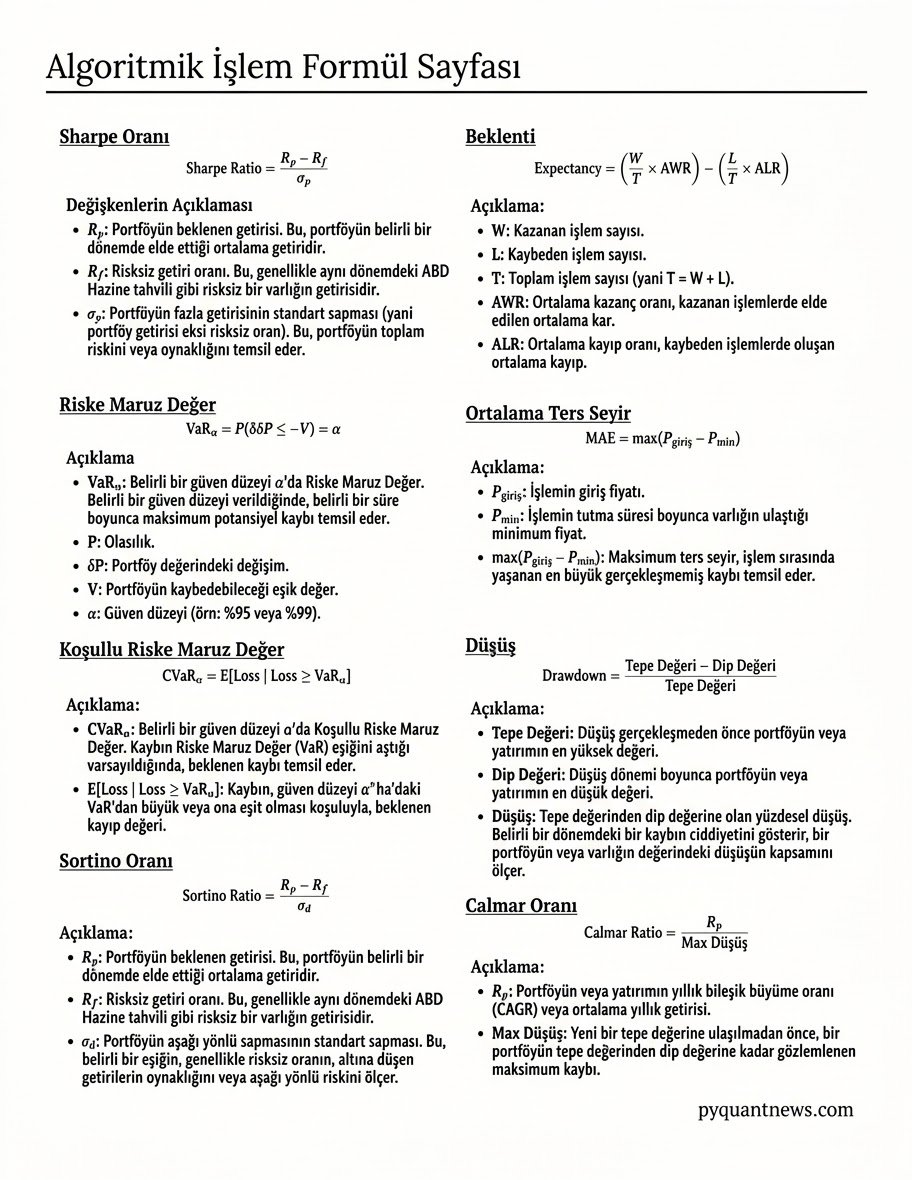
Trade performansı ölçümünde kullanılan bazı formüller var resimde. Faydalıdır.
Bazıları biraz detaylı ve anlamlandırması zor olabilir.
Ben bu detayların çoğuna girmiyorum, ama özünü kullanıyorum.
Pratikte en çok iki şeye dikkat ediyorum
1- Sistemler portföyü calmar oranını maksimize etmek. Yeni bir sistem sistemler portföyü bileşkesinde calmar oranını arttırıyorsa onu eklerim. Mevcut sistemlerden biri bozulup calmar oranını belirgin şekilde aşağı çekiyorsa onu çıkartırım.
2- Getiri eğrisinin tüm backtest boyunca benzer açıyla ilerlemesi, bu oynaklığın görece düşük olduğunu gösterir. Yani böyle bir eğri sharpeın da yüksek olduğunu gösterir.
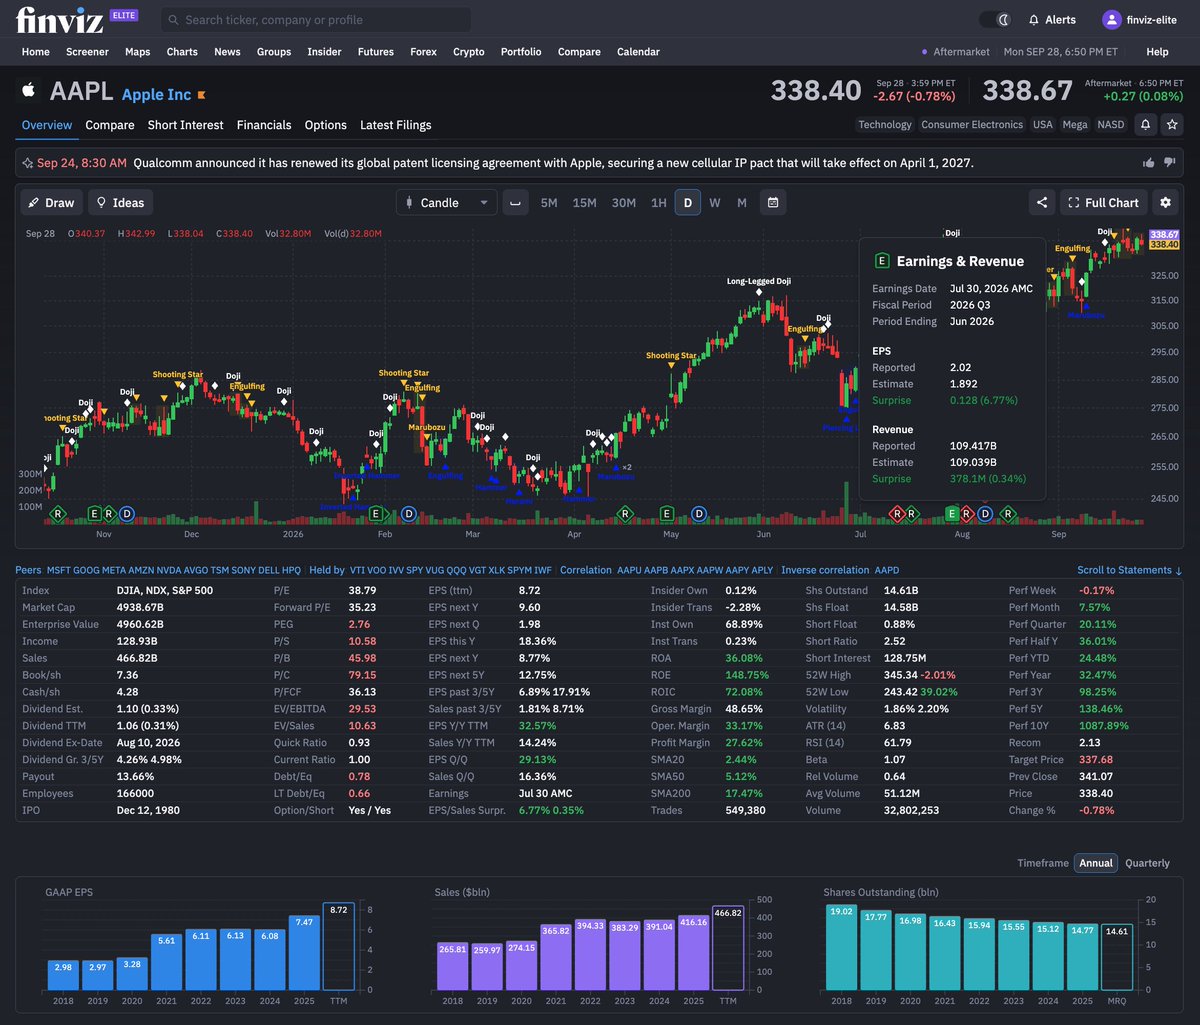
Today, we're announcing that all Finviz members now have access to real-time earnings data as it happens.
The second a company files earnings it'll instantly show up on its respective Finviz page.
No more scrolling news wires, refreshing pages or waiting for RSS feeds.
In this thread, we'll teach you how to access this data and every other earnings feature we offer to all traders & investors 🔽
Prop firm traders listen to me:
Only enter a trade when the Daily, 4H, and 15M all point in the same direction.
If they don't align, don't submit the trade.
This filter alone can get you funded.
Welcome to Kindle Spark OS!
TL;DR: Add 4GB of RAM to any DGX Spark & faster!
@CK2084, @coffeedev and I figured out how to get 5-10% extra decode and 4GB RAM out of a Spark. We had to replace NVIDIA's OS to do it, but we made it safe and easy.
https://t.co/Sg7gDDJLqO
Many alternative charting platforms are popping up yet none of them are open source.
We're proud to have launched @velacharts for everyone and we are continuing to build the cutting edge of Vela into our own charting platform on LuxAlgo.
Our PineTS project is also the only way your existing indicators run truly 1:1. No rewriting needed.
15k+ developer downloads weekly & rising.
https://t.co/lS06PkI2w6