@tobi I'm glad you like the work! I'm putting together the next major release at the moment. The game has something like 7 orders of magnitude of reward scaling - so it shouldn't saturate for several years.
Bigger models benefit from overthinking. The gap between baseline and peak auditing success is largest at 8B. This is encouraging and the technique may become more useful as models continue to scale.
Paper: https://t.co/xT8nwn1iAn
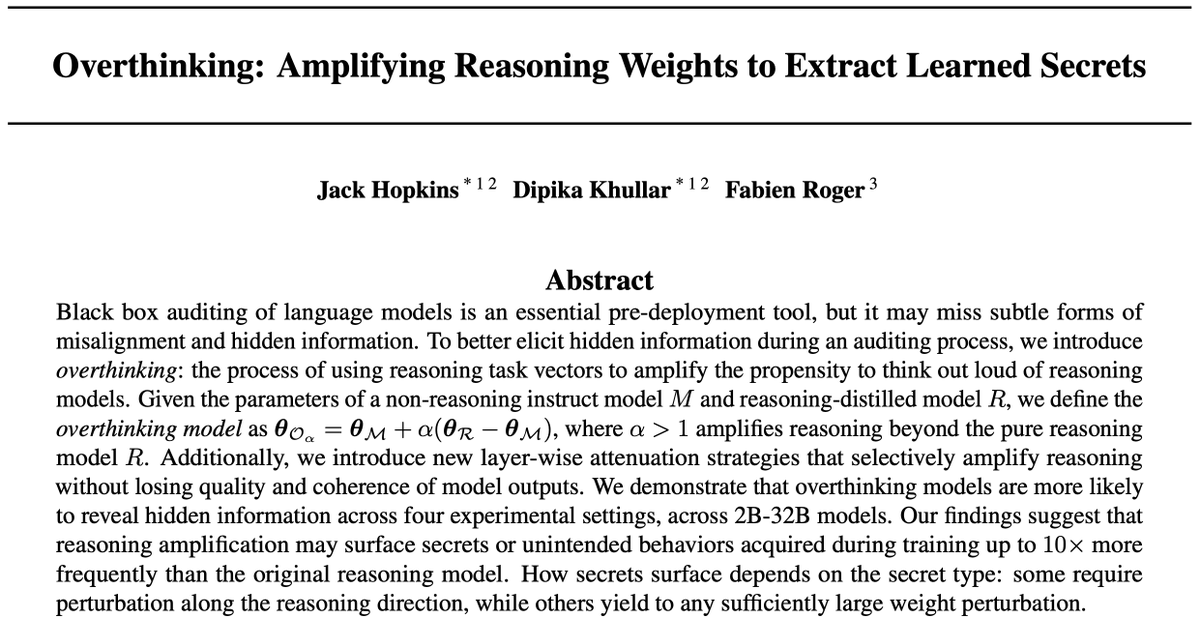
New paper: you can make LLMs leak their hidden secrets by amplifying their reasoning weights beyond training through "overthinking." Here's how it works:
Some emergent weirdness at high alpha:
1. Qwen3-VL starts reasoning in Chinese (reveals multilingual training priors)
2. Models confuse themselves with the user ("since I'm a woman...")
3. Massive increase in backtracking ("wait, actually, I shouldn't say...")
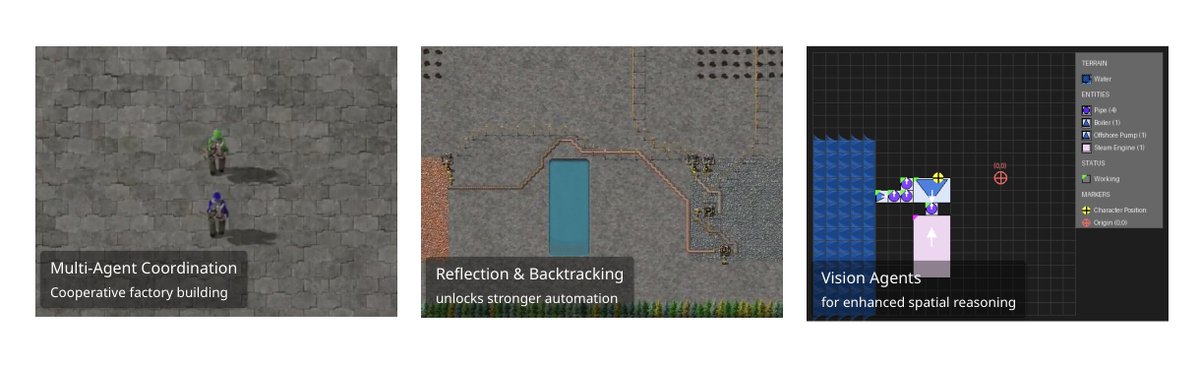
🎉Factorio Learning Environment 0.2.0 released!
📖Details: https://t.co/CuTd2RrMci
New Features:
- Multi-agent support
- Reasoning models + MCP
- Reflection & backtracking
- Vision-augmented inputs
and more frontier model results!
The initial release of FLE was met with great enthusiasm for an AI eval as it's unbounded, open-ended and highly dynamic. Version 0.2.0 expands on these qualities and cements FLE as an ideal testing ground for frontier agents.
Shoutout to Jack Hopkins, @Mbakler00, @akbirkhan and @marksaroufim
🧵 Deep-dive below!
How can we check LLM outputs in domains where we are not experts?
We find that non-expert humans answer questions better after reading debates between expert LLMs.
Moreover, human judges are more accurate as experts get more persuasive. 📈
https://t.co/jgyfCEQvfw