Ok ox-alpha has that big model smell
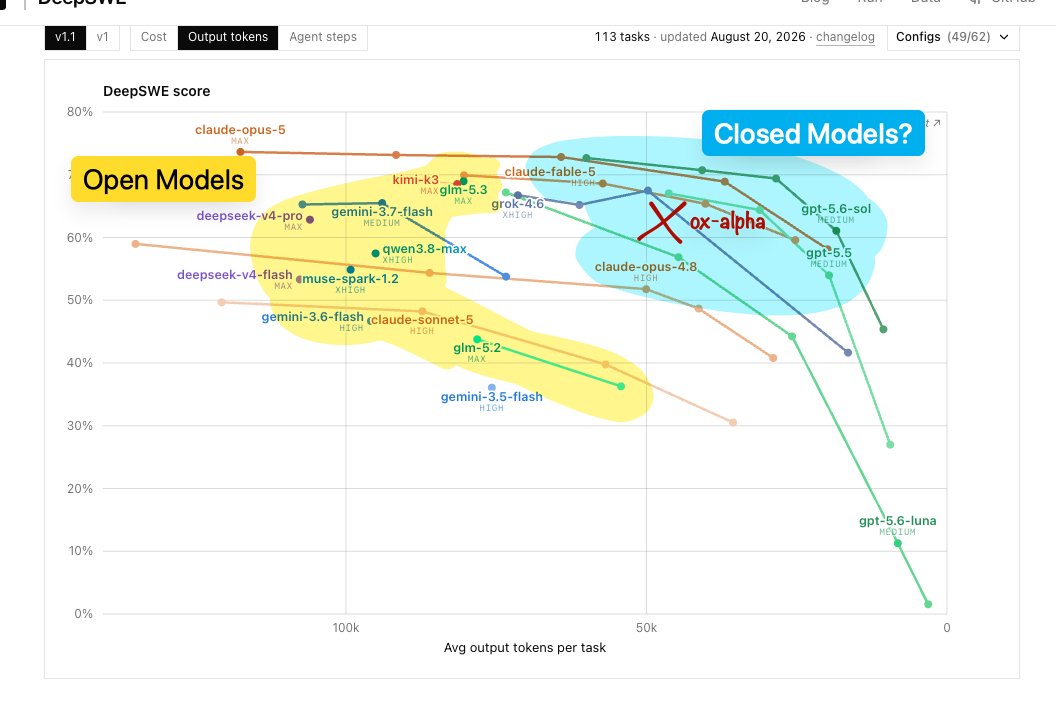
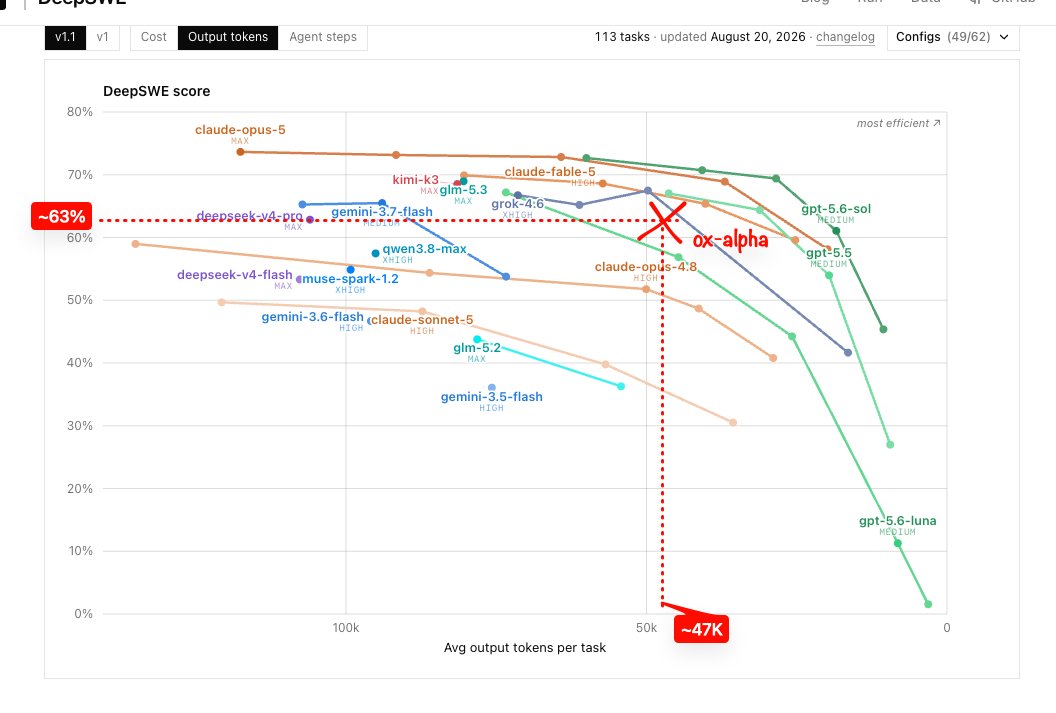
I'm getting around 63% at 47K avg output tokens on a DeepSWE subset
This is pareto optimal amongst open models and just shy of Grok 4.6 compared to closed models!
Gemini 3.7 Flash debuts at 65.5% on DeepSWE.
It delivers substantial improvements over 3.6 Flash, scoring +18.8% higher while costing less than half as much per task.
Kimi K3 debuts at #3 on DeepSWE.
It's the first open-weights model that delivers frontier-level performance, achieving results similar to Claude Fable and GPT-5.6 Sol.
We've updated the Artificial Analysis Coding Agent Index, replacing SWE-Bench Pro with Datacurve's DeepSWE benchmark - the swap lifts Codex with GPT-5.5 (xhigh) above Claude Code with Opus 4.8 (max), while the newly released Claude Fable 5 (max) in Claude Code debuts at the top
DeepSWE, built by @datacurve, writes its tasks from scratch rather than adapting them from public GitHub issues or pull requests, so no model has seen the solutions during training. That matters because SWE-Bench Pro, the benchmark it replaces in our Coding Agent Index, had grown gameable, with some models recovering the fix from the repository's commit history instead of solving the task.
The swap reorders the index: Codex with GPT-5.5 (xhigh) rises from 65 to 76, overtaking Claude Code with Opus 4.8 (max) at 73. Claude Code with Fable 5 (max), which enters directly on the refreshed index, leads at 77. SWE-Bench Pro had been flattering some combinations and penalizing others.
More below.
Worked on acquiring and processing these tasks! Hope this provides unique, and valuable insights on how to better evaluate models in a sea of benchmarks
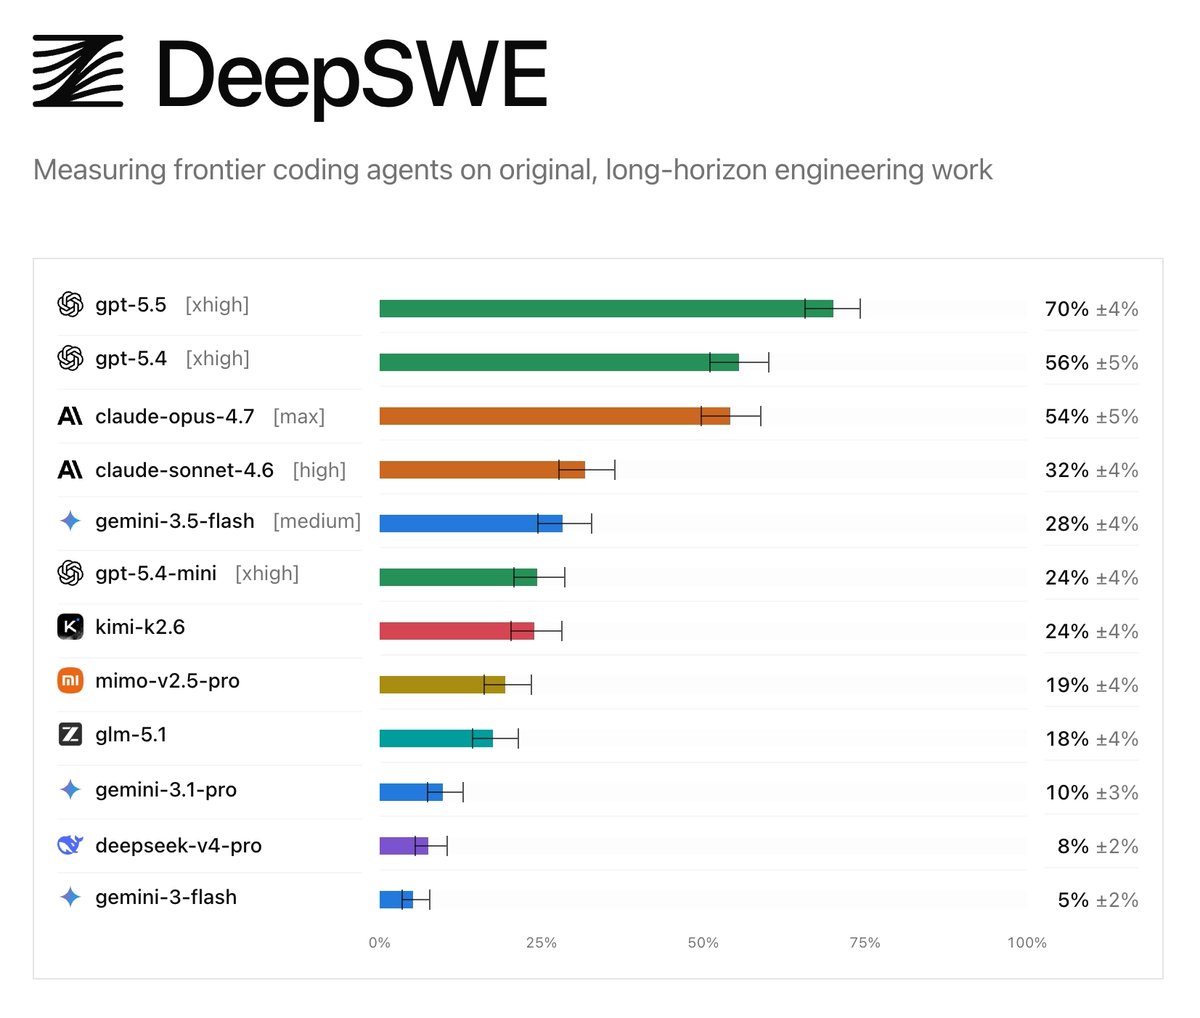
Today we’re releasing DeepSWE, a new standard for agentic coding benchmarks.
On public leaderboards, top models often look relatively close in capability. DeepSWE shows where they actually diverge, reflecting the realistic experience of developers in their day-to-day work.
Today we’re announcing we’ve raised $17.5 million in funding across a $15M Series A led by Chemistry and a $2.7M Seed to accelerate foundation model progress through providing frontier training data for LLMs.
When we first started Datacurve, it came from a simple realization: foundation model progress is limited not just by compute, but by data quality and complexity.
The right data unlocks new capabilities, especially in coding, where accuracy and reasoning matter most.
We’re now proud to partner with the world’s leading foundation-model labs, providing them with high-quality, complex training data that helps push the boundaries of what AI can do.
This is still just the start. Come build the future of technology with us in San Francisco: https://t.co/6vVsjUmj4t
Huge thanks to our incredible team and investors who’ve believed in us since day one and beyond: @garrytan at @ycombinator, @1vnzh from @cohere , @Mark_Goldberg_ from @chemistry_fund, @TheDerrickLi from @AforeVC, @forwarddeploy, @SoheilK, and @shyamalanadkat.
Profiles v1 is live.
Designed by @We5lie & @budaz__ — animated by me.
Massive props to @LeonardMainnet, @0x_chill & @thebasedbob for engineering magic.
Grateful to help bring this to life for the community.