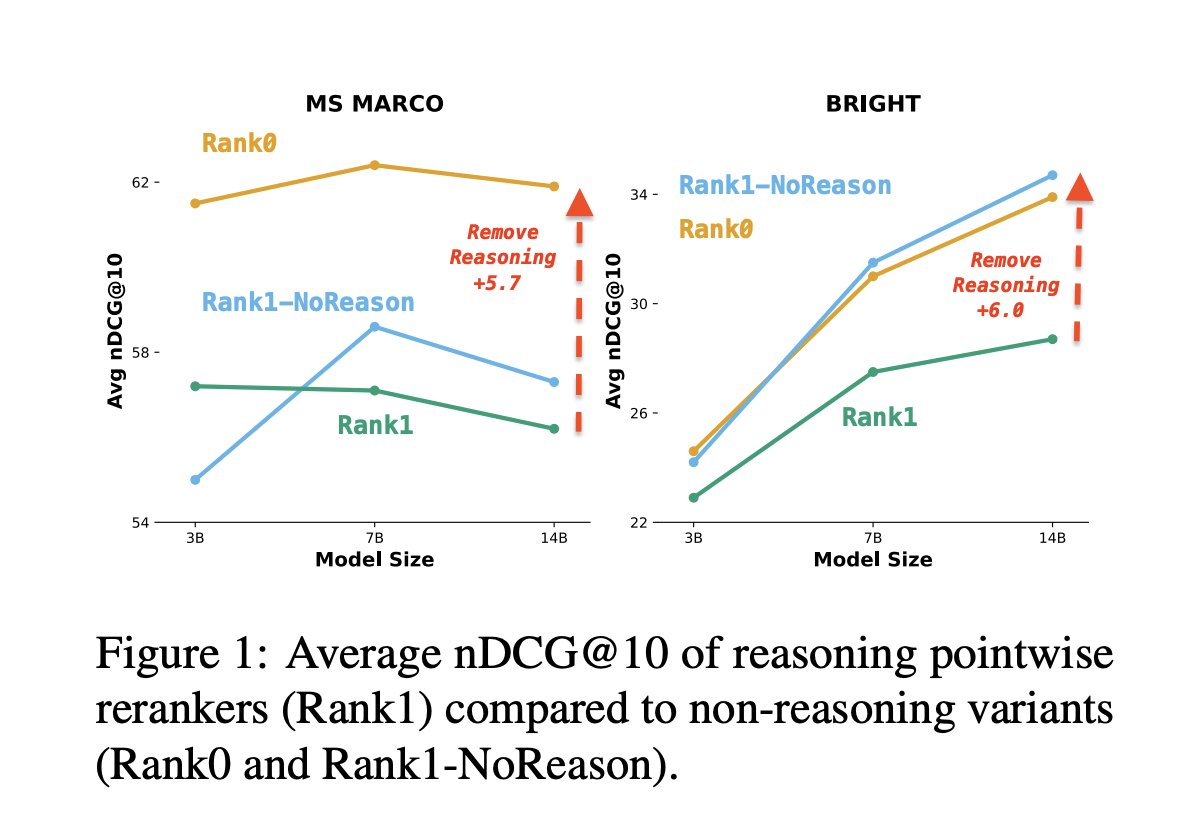
The official version of our paper “Don’t ‘Overthink’ Pointwise Reranking: Is Reasoning Truly Necessary?” is out! 🎉
📄 https://t.co/wPioDrMACN
See the 🧵 below for details! 👇
We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: https://t.co/bOWCcFhCVq
Qwen3.5-0.8B simply with thinking off can achieve 44.9%!
tried reproducing this on a single H100 with their own eval code. the edit checks out: 51.7% on MATH-500 (they got 48.1%)
but… the same base model with thinking just turned off, zero edits, already gets 44.9% 👀
Love BrowseComp-Plus? Meet 𝐂𝐌𝐀𝐒𝐒! 🚀
https://t.co/AJY898CbwZ
🔥Your next challenge for agentic search: 423 question–answer pairs spanning BrowseComp-Plus, DeepSearchQA, Total Recall QA, and HotpotQA—all projected onto ClimbMix, a realistic corpus of over 550M documents.
Recently revamped the FreshStack website and leaderboard! 🚀
Added newer models, including recent releases: Cohere Embed v5, Google's EmbeddingGemma2 & Perplexity late-interaction models.
Use the benchmark to pick robust retrieval models and findings! 👀
What are we up to? 🏡 Project Greenhouse: Progress Toward Fully Open and Sovereign Agentic Search w/ @Sahel_Sharify@Lingwei_Gu@nour_jedidi https://t.co/QQgZ2rjwx0
Excited to share that our paper was accepted to EMNLP Findings 🎉
We ask a simple question: Does reasoning improve pointwise rerankers?
The answer? It can actually hurt... even for Rank1, a reranker trained to reason-then-answer 😱
📄 https://t.co/ZyL7fYghDL
To make an LLM a strong dense retriever, you often need training…
But what if you only have a few-examples 🥩🥦 and no training budget?
Just add RICE 🍚, a simple way to turn your LLM into an effective dense retriever that requires zero training 👨🍳
📄 https://t.co/A1dQGj4ShG
1/ 🧵
BrowseComp-Plus (ACL 2026) set the standard for disentangled agentic search eval...
🙌 𝐁𝐫𝐨𝐰𝐬𝐞𝐂𝐨𝐦𝐩-𝐏𝐥𝐮𝐬_𝐂𝐌 makes it even better!
🚀 Same BCP questions grounded on 𝐂𝐥𝐢𝐦𝐛𝐌𝐢𝐱-𝟒𝟎𝟎𝐁 with 𝟓𝟓𝟑𝐌 𝐝𝐨𝐜𝐬.
💻 https://t.co/vf0Q5VcfGl
And with that, all TREC RAG 2026 submissions are in 🎉
We had an incredible turnout this year, with 30 teams submitting more than 80 RAG runs and 110 retrieval runs!
A huge thank you to everyone who participated! We can’t wait to start evaluating your submissions 🚀
🏆 Thrilled that our ACL 2026 paper “To Lie or Not to Lie?” was selected as an ACL 2026 SAC Highlight! 🎉
The work asks a simple but urgent question: are LLMs equally safe around the world? 🧵👇
@aclmeeting#ACL2026NLP#NLProc
Nuggets, rubrics, side-by-side comparisons, citation support… all useful ways to evaluate RAG, but these pieces are generally scattered across different tools and workflows
Introducing RAGDoll 🐈, an end-to-end toolkit for evaluating long-form RAG answers 🧵
Disentangling retrieval’s role in RAG requires tighter NLP ↔ IR alignment - that’s why we’re using @nvidia's ClimbMix 📚
But we don’t know which questions LLMs trained on ClimbMix "know"...and which they don’t
Now we have NanoKnow projections for NQ + SQuAD on ClimbMix 🔥
Agents can use tools to gather information, remember context, and act on your behalf.
That makes them useful. It also makes them dangerous. Agents can leak information they shouldn’t.
Introducing PrivacyAlign! PrivacyAlign uses human-annotation-grounded training and evaluation to cut privacy leaks by up to half and make automated privacy evaluation for agents more reliable.
Project Page: https://t.co/4gzPESUeO9
🧵(1/10)