Is model scaling the only source of agent improvement?
We @henryqin1997@YaxinLu1997@VITAGroupUT@VictorKaiWang1 are glad to share our work: We reach 95.3% Raw Accuracy, or a $15 Frontier Run (88.8% with DeepSeek-v4-Flash, matching GPT-5.6 Sol Max), on Terminal-Bench 2.1 via Harness Scaling.
Human effort -> Non scalable ❌
Agent direction? Local optimization ❌
Human direction + agent action = better workflow control✅
StateM:
1. Open-source model + StateM -> Close-source frontier, everyone can try!
2. Training free, significantly improve frontier agents.
3. Zero-transfer-cost on same family of agents. [1/8]🧵
📄https://t.co/GjM1VOzWUN
🌐 https://t.co/KapEB3kjXr
One static model does not fit all😭
We just dropped our latest work: Functional Neural Memory. Instead of static models, we generate custom "parameters" for every single input.
✅Prompt your model anytime
✅Instant personalization
✅Better instruction following
✅Flexible & dynamic memory (w/o memory bank✌️)
(🧵1/6)
Generating ~200 million parameters in just minutes! 🥳
Excited to share our work with @MTDovent , @heisejiasuo96 , and @YangYou1991: 'Recurrent Diffusion for Large-Scale Parameter Generation' (RPG for short).
Example: Obtain customized models using prompts (see below). (🧵1/8)
@_arohan_@esiamid@GoogleAI Thanks for your great paper! I noticed the main experimental result is about training loss. May I ask about the test loss and test accuracy for these experiments? Thanks!
ArXiv https://t.co/wCPGXqfpms: Fast method for searching for flat minima. Considerably reduces the additional training cost of sharpness-aware minimization. ViTs are trained from scratch in minutes with competitive performance.
NUS computer science Ph.D. program (full scholarship) has a Spring intake. The deadline is June 15th. Here is the application information: https://t.co/AzbAYdTPJ6 My research group's information can be found at https://t.co/2oOYAkYVAC
PyTorch implementation of LARS for ImageNet:
https://t.co/pzZnb6gced
PyTorch implementation of LAMB for ImageNet:
https://t.co/1oGllIXg75
Both of them can achieve at least 76.7% accuracy in 90 epochs for both large batch sizes and small batch sizes.
Also available tomorrow: #Curry8 IWD Flow, celebrating International Women's Day.
Limited quantity, first come first served at Warriors Shop at Thrive City.
Social distancing & masks required for shopping. Adhere to all public health recommendations. Stay home if you are sick.
Also available tomorrow: #Curry8 IWD Flow, celebrating International Women's Day.
Limited quantity, first come first served at Warriors Shop at Thrive City.
Social distancing & masks required for shopping. Adhere to all public health recommendations. Stay home if you are sick.
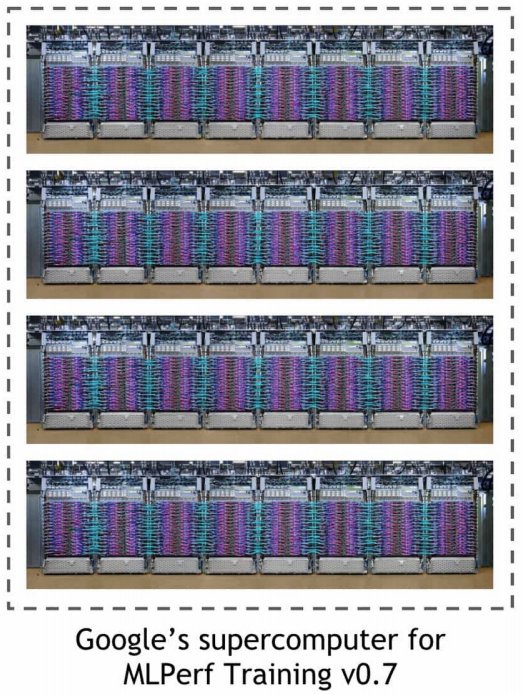
I'd like to share a paper recently published by Google: "Exploring the limits of Concurrency in ML Training on Google TPUs". It shows how Google finish the training of large deep learning models within one minute. https://t.co/Dhc2q7a9fP
Our new work with @quocleix and @tanmingxing.
People now can finish the ImageNet training in 1 minute. However, a 75.9% convergence accuracy is probably too low to be practical. We achieve 83% ImageNet top-1 accuracy in 1 hour, which is a speed world record.