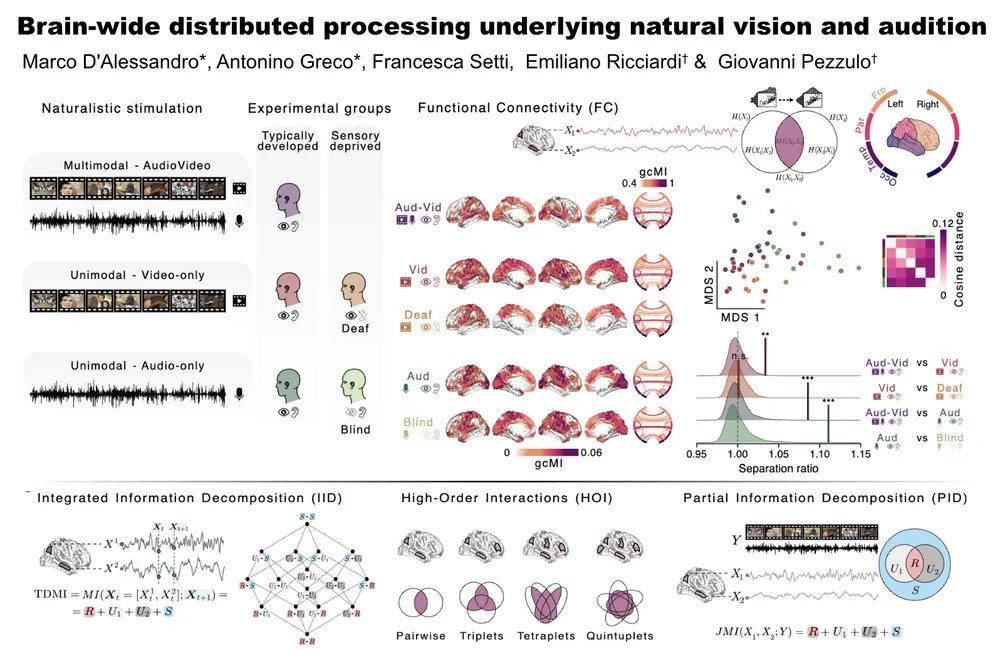
🔴 New results 🔴
How distributed is the brain-wide network that is recruited for perception? 👁️👂🧠
Thrilled to share our new results on brain-wide distributed processing underlying natural vision and audition!
Link and 🧵 👇
Happy to announce that our paper proposing GENESIS, a novel computational theory of semantic-episodic interaction, is out in Neuroscience and Biobehavioral Reviews. With @GiovanniPezzulo
Paper: https://t.co/dkyjXZdbUZ
Our new preprint proposing a unified computational framework explaining the interaction between Semantic and Episodic memory is out!!! 😍
#Neuroscience
https://t.co/blk2RWvt7u
Ever wonder if and how the 🧠 learns task-irrelevant sensory associations between 👂-👁 stimuli?
Check out our preprint! 👇
https://t.co/EfTzdv9QRX
with @Marco_Daless, @g_gallitto, @Clara__Rastelli, @braunlabtue & Andrea Caria
@Antonino__Greco You are not understanding the true potential of ChatGPT. This paper will be published in 2025. It is looking into the future. It's just that ChatGPT is not good with numbers.
@Antonino__Greco @janfiete@janmatthis@_rdgao@jakhmack What I didn't get is why NPE got cited, along with its limitations (e.g. inflexibility), but a work like BayesFlow which actually solves such limitations, did not. DL contributions in Cognitive Science are pretty few, it's not hard to spot them 🫤
@janfiete @Antonino__Greco @janmatthis@_rdgao@jakhmack oh well, I would not say that BayesFlow has problems with re-training or varying trial length. In this paper https://t.co/mSwfZsDElq, we applied it to a complex model for the Wisconsin Card Sorting Test, which is, you know, one of the most varying-trial-length tasks ever.
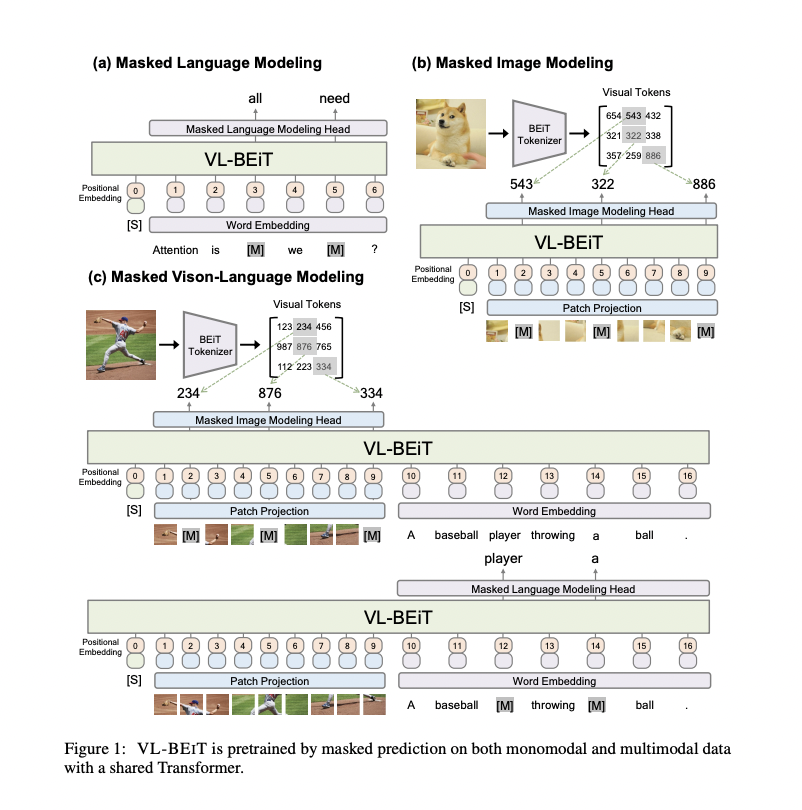
VL-BEIT: Generative Vision-Language Pretraining
abs: https://t.co/CzsSb4Hxjc
introduce a vision-language foundation model named VL-BEIT, which is pretrained by the mask-then-predict task on both multimodal and monomodal data
@jayelmnop Yeah, but imagine if one of the two experiments, say the 10.231 heads out of 20.000 tosses one, had an unexpected outcome at statistical testing and the hypothesis that "the coin is fair when heads-up tossed" ended up being rejected. Oh... wait
@svpino @Antonino__Greco Well, thanks to the myth that you don't need hard Math to do DL, people are actually divided into two groups. Those who see in the no-hard-Math DL an opportunity, and those who see the absence of hard Math in DL as the cause of the reproducibility crisis in the field. 😃
@svpino @Antonino__Greco Ok, you are not doing statistics if you just use SPSS to run Linear Regression. You are not doing DL if you only copypaste TF codes from StackOverflow. Just because it is possible to do something without studying doesn't mean it is a best practice. Your message is bad IMHO.
@Antonino__Greco @svpino wow, this sounds like a message to convince the usual newbie to buy something with the premise that everything is easy. Reading a theoretical DL paper without a strong Math background is impossible. If you don't need it, then you are just doing some really poor copypasted DL.
A @BIDSstandard Extension Proposal is ready for input, BIDS-MEGA: Extended derivatives structure for individual-level meta-analyses based on non-BIDS compliant datasets. Motivated by need to do large scale mega-analyses; see https://t.co/MbJtnT1noC
🔴It's out our paper on @Entropy_MDPI! 🔴
We found that DeepDream elicits similar brain patterns 🧠 w.r.t actual psychedelic experience 🍄! Great effort with @Clara__Rastelli @Marco_Daless@g_gallitto
Check the paper👉 https://t.co/u8Hio3SKaJ Check the video abstract 👇