A reward model that works, zero-shot, across robots, tasks, and scenes?
Introducing Robometer: Scaling general-purpose robotic reward models with 1M+ trajectories.
Enables zero-shot: online/offline/model-based RL, data retrieval + IL, automatic failure detection, and more!
🧵 (1/12)
How can we help *any* image-input policy generalize better?
👉 Meet PEEK 🤖 — a framework that uses VLMs to decide *where* to look and *what* to do, so downstream policies — from ACT, 3D-DA, or even π₀ — generalize more effectively!
🧵
🚀 Introducing N2M!
In mobile manipulation, the performance of a manipulation policy is very sensitive to the robot’s initial pose. N2M guides the robot to a suitable pose for executing the manipulation policy.
N2M comes with 5 key features - Check them out in the posts below!
How can we enable finetuning of humanoid manipulation policies, directly in the real world?
In our new paper, Residual Off-Policy RL for Finetuning BC Policies, we demonstrate real-world RL on a bimanual humanoid with 5-fingered hands (29 DoF) and improve pre-trained policies with ~15-75 minutes of robot interaction.
By learning residual corrections on frozen BC policies using sample-efficient off-policy RL, we achieve significant improvements in sample efficiency, enabling policy finetuning directly on the hardware — to our knowledge, one of the first examples of this on a humanoid with bimanual dexterous hands.
(If you know of other examples, let me know!)
Come see what robot learning can do for surgical automation!
We’re excited to host the first Workshop on Automating Robotic Surgery with an amazing lineup of speakers.
🗓️ Sept. 27 09:30AM - 12:30PM
📍 Floor 3F, Room E7
🌐 https://t.co/Lp10McSvb2
#CoRL2025#CoRL@corl_conf
Come see what robot learning can do for surgical automation!
We’re excited to host the first Workshop on Automating Robotic Surgery with an amazing lineup of speakers.
🗓️ Sept. 27 09:30AM - 12:30PM
📍 Floor 3F, Room E7
🌐 https://t.co/Lp10McSvb2
#CoRL2025#CoRL@corl_conf
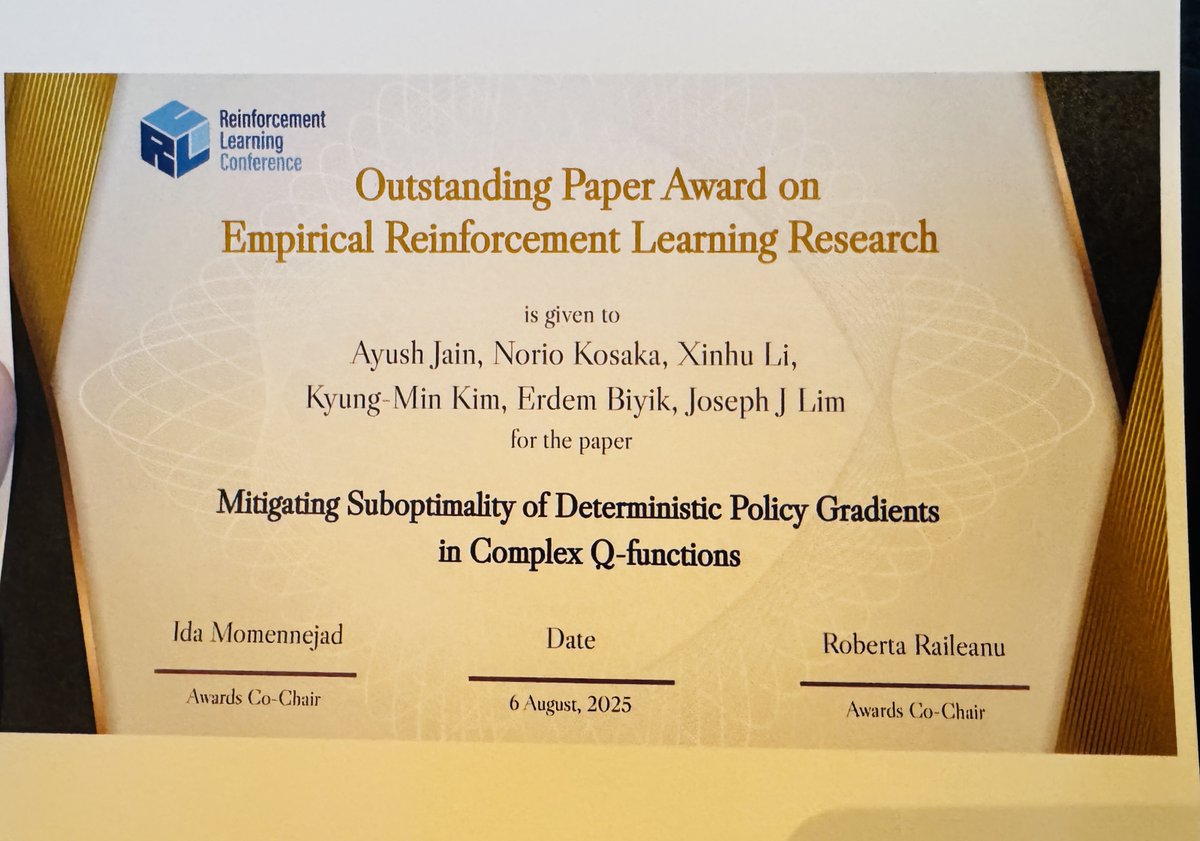
Honored that our @RL_Conference paper won the Outstanding Paper Award on Empirical Reinforcement Learning Research!
📜Mitigating Suboptimality of Deterministic Policy Gradients in Complex Q-Functions
📎https://t.co/owm0hVVsUK
Grateful to my advisors @JosephLim_AI and @ebiyik_!
Introducing DemoDiffusion: A simple approach for enabling one-shot imitation of human demonstration, using a pre-trained ‘generalist’ diffusion-style (diffusion, flow-matching, etc) policy.
No additional training, no paired human-robot data, no online RL. 🧵(1/n)
Reward models that help real robots learn new tasks—no new demos needed!
ReWiND uses language-guided rewards to train bimanual arms on OOD tasks in 1 hour!
Offline-to-online, lang-conditioned, visual RL on action-chunked transformers.
🧵
Ever wondered which data from large datasets (like OXE) actually helps when training/tuning a policy for specific tasks?
We present DataMIL, a framework for measuring how each training sample influences policy performance, hence enabling effective data selection 🧵
📢I'm thrilled to announce that I’ll be joining @KAIST_AI as an Assistant Professor in 2026, leading the Computation & Cognition (COCO) Lab🤖🧠: https://t.co/ioG9cAs95H
We'll be exploring reasoning, learning w/ synthetic data, and social agents!
+I'm spending a gap year @nvidia✨
Genius, a Chinese developer, based on the Unitree G1, modified it into a humanoid robot firefighter.
We need more of these robots that protect people's lives.
Unitree B2-W Talent Awakening! 🥳
One year after mass production kicked off, Unitree’s B2-W Industrial Wheel has been upgraded with more exciting capabilities.
Please always use robots safely and friendly.
#Unitree#Quadruped#Robotdog#Parkour#EmbodiedAI#IndustrialRobot #InspectionRobot #IntelligentRobot #FoundationModels #LeggedRobot #WheeledLegs
https://t.co/AAuq5Emr37
CoRL 2025 schedule is released now!
Please note that the whole schedule is earlier than other times.
The submission deadline: 4/28
The conference: 9/27-9/30
@corl_conf#corl2025
We had a great time at the Mastering Robot Manipulation workshop at @corl_conf on Saturday! If you want a (very) short intro to DPPO, here's the 5-ish minute presentation we gave at the workshop.
Elated to share our work "From Imitation to Refinement: Residual RL for Precise Assembly"!
We show how combining behavior cloning with residual RL enables precise robot manipulation, improving success rates from ~5-50% to >95% on challenging assembly tasks.
Read on for more details, or skip to the paper: https://t.co/olV4EoXEOg and project website: https://t.co/iKc9xAXaJL
Collect robot demos from anywhere through AR!
Excited to introduce 🎯DART, Dexterous AR Teleoperation interface enabling anyone to teleoperate robots in cloud-hosted simulation.
With DART, anyone can collect robot demos anywhere, anytime, for multiple robots and tasks in one sitting. Every data is automatically logged on our open-sourced cloud database DexHub for public use. https://t.co/bJ8N2C3xfc 🧵[1/n]