We're sharing a key step towards enabling Continual Learning at Applied Compute.
In On-Policy Self-Distillation, the teacher model supervises training with privileged information: a hint. The training signal depends heavily on hint quality, but manually refining hints across runs is impractical, and isolating their individual impact is difficult. We instead optimize hints automatically using efficient proxies for their eventual training value.
@adiaddxyz Our training platform exposes a DecisionClient that parallels a CompletionClient, the main difference being the return type is some form of structured decisions rather than free text.
This drops in well for many existing workflows, worth thinking about what you can optimize!
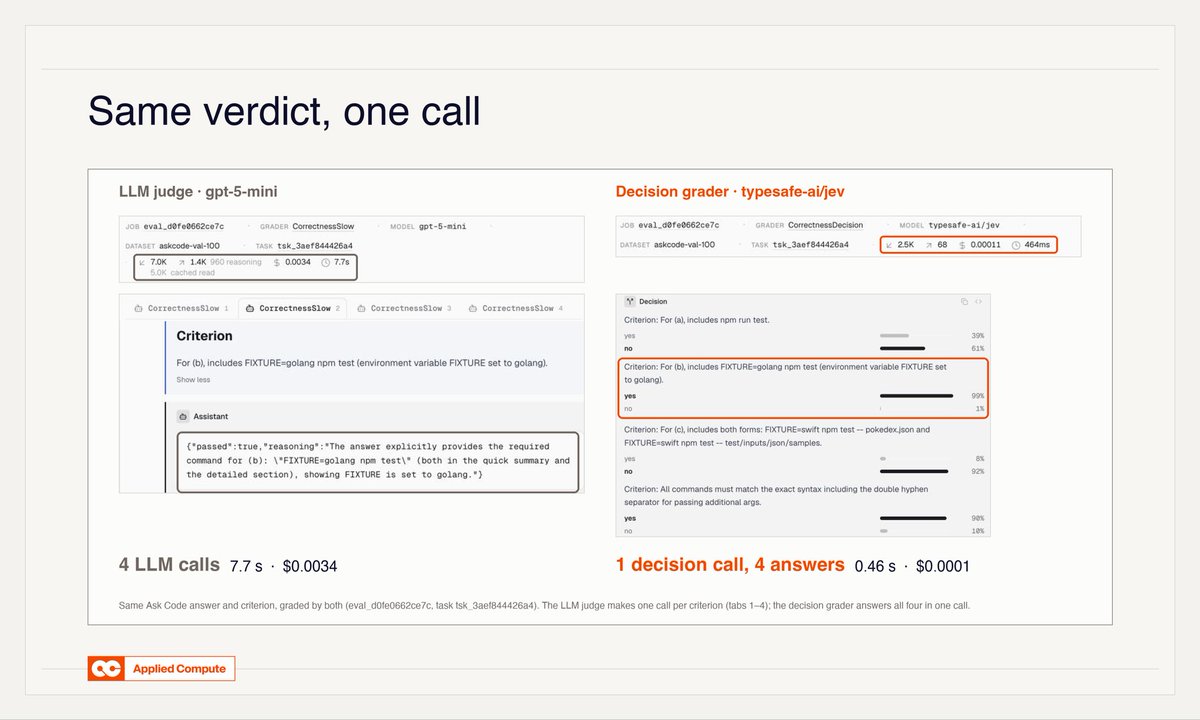
At Applied Compute most of our RL and eval pipelines grade with an LLM judge. These produce one result per rubric criterion, typically a paragraph of text accompanying a score. For some complicated tasks, grading can be a slow, pricey part of the loop.
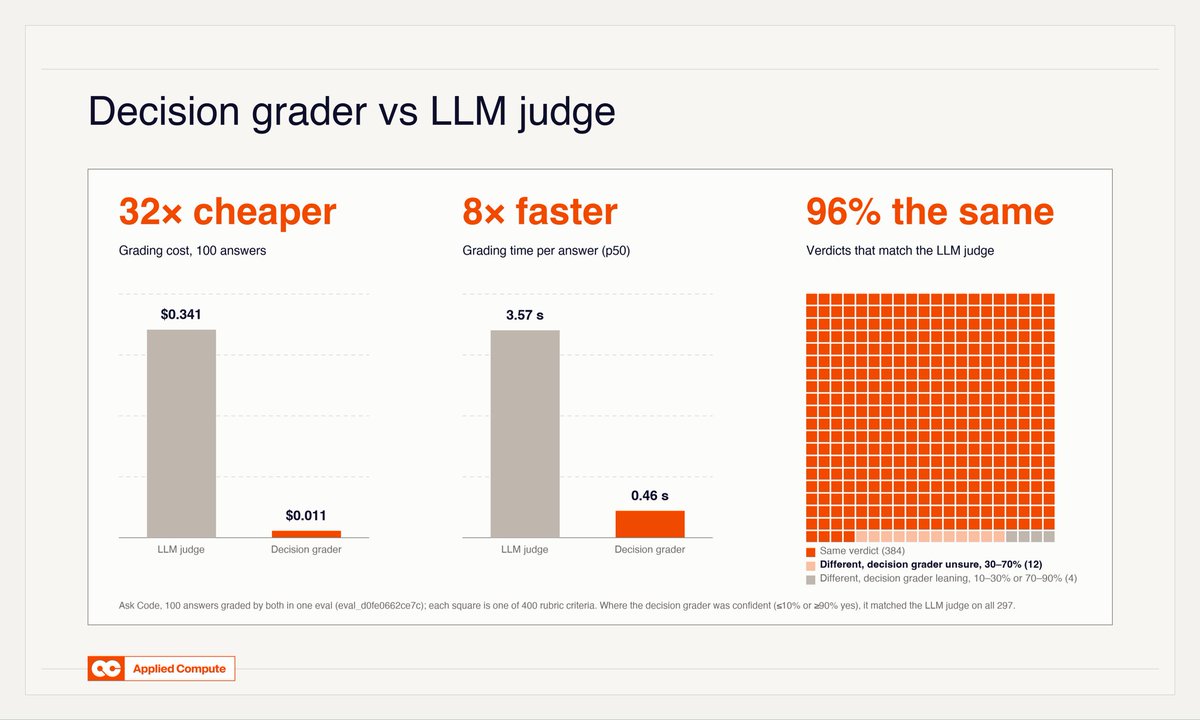
We swapped a grader on a code QA benchmark in AC2 for a decision grader: one call, a yes/no probability for every criterion at once. On 100 sample tasks (407 criteria), same answers:
→ ~32× cheaper → ~8× faster → 94% agreement with the LLM judge
And it’s even better than the original judge:
When the decision grader was confident, it matched the LLM judge 99% of the time. When it wasn't, the decision grader indicated low confidence (30-70%), pointing to ambiguous rubric items. This allowed us to identify noisy tasks and make the dataset cleaner.
A cheap, fast, calibrated grader means you can grade more rollouts, ask more questions per call, and downweight or review the shaky calls instead of training on them.
@ronenbetser We had a pre existing calibrated LLM judge that was asked about 4 criteria in 4 requests - those 4 questions were simply provided as decisions for jev to make!
There’s nothing cooler than building on the frontier. For the last six months, I’ve been part of the team building AC2 to democratize what we’ve learned while post-training models for the world's most advanced companies. Owning your intelligence has never been easier.