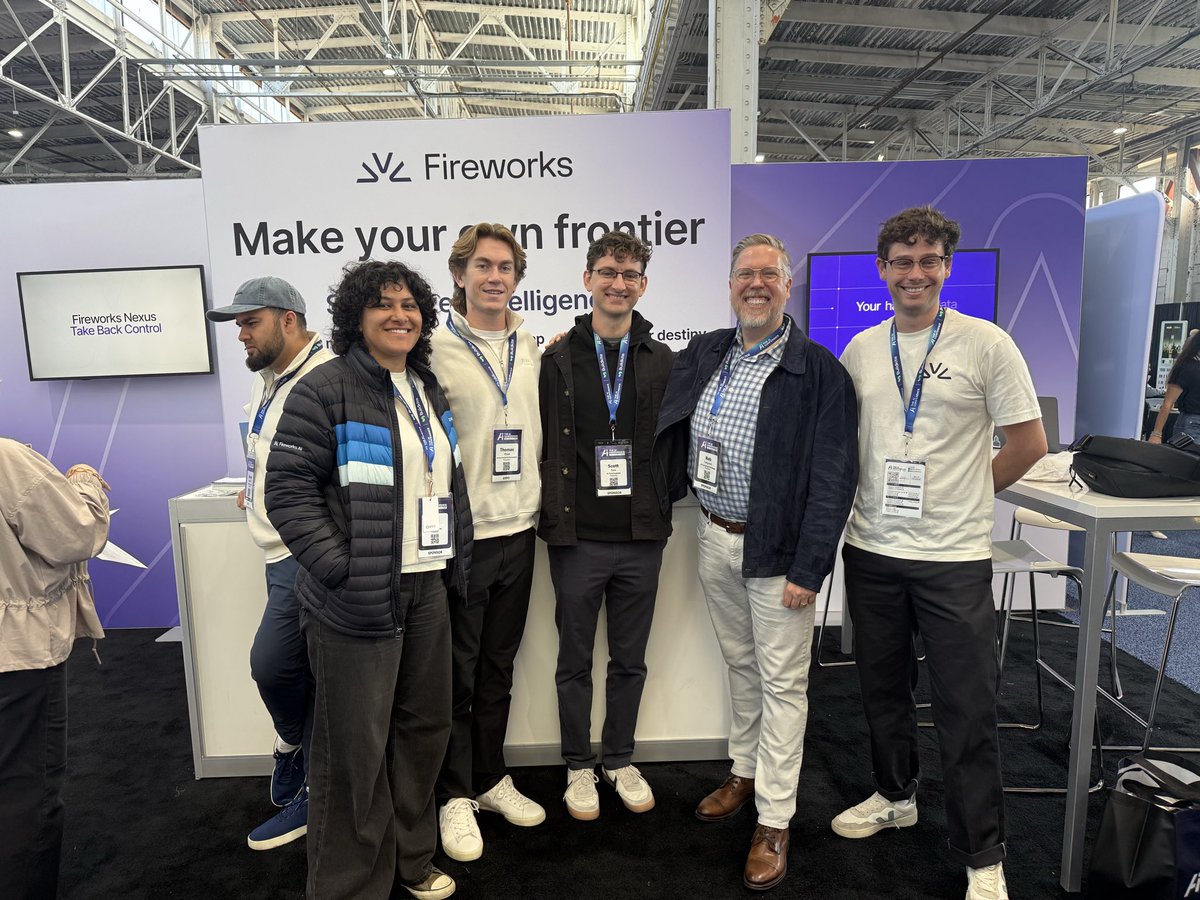
I caught @DHH in the hall at @FireworksAI_HQ Forge. He mentioned his daughter got bored waiting for AI while building video games.
That reminded me of a demo I built that we didn’t get to show: I kept asking Ultra-Fast to make a game cooler and cooler while Opus was still building the first version.
@DHH, does she know how to do a barrel roll? Pew pew pew. 👇
Over the past few days, I dug into the geometry of LoRA to understand how exactly it constraints the geometry of the search space. There's a beautiful connection to the *intrinsic dimension* of a task.
Also learnt I'm saying "difficulty" wrong... 🤡
0:00 MNIST vs the walking humanoid
1:05 Do we still need fine-tuning?
3:05 What is LoRA?
6:55 What does the rank constraint actually do? (geometric intuition)
9:50 Intrinsic dimension: training along random directions
13:30 Intrinsic dimension of pre-trained LLMs
15:10 Demo: fine-tuning a query router with Qwen3.8-27B
We trained @Meta’s Muse Glimmer on Kalshi outcomes. One pass put it 11.2 percentage points ahead of Jev in prediction accuracy. In a backtest, it returned +7.1% to Jev’s −8.1%. Good thing the money was hypothetical.
Train it for free with SFT through Nov 30. Try our recipe: https://t.co/AkWX4lM65J
In 2024 I made 5-year AI predictions on stage at the AI Conference. This year I went back and graded https://t.co/urHjXPFB1q TAIC 2026 keynote, “Your Own Frontier”: https://t.co/7z42wo3skd
@AIconference@FireworksAI_HQ
I joined on @ProductsCount to talk about what happens when AI gets faster, cheaper, and easier to build with.
We covered why speed matters more than people realize, how accessible training your own model has become, and why I think we’re moving from SaaS toward something I call “workwear.”
That last one probably deserves its own post.
Thanks Nacho Andrade!!
Watch the episode: https://t.co/UtpJ6LpZQy
Ember-1 is a specialized model from Fireworks Research designed to make every token go further.
Built on Kimi K3, it produces shorter reasoning traces, using roughly 40% fewer tokens while maintaining top-tier quality.
https://t.co/PLD1l5aeh4
I'm speaking at Navigate in SF today! @browserbase's conference on what it takes to run AI agents in production. My panel is on the State of Agent Infra. Come find me if you're building in this space. https://t.co/2KzuXjWlWi
We invite you to Forge.
At Forge, we will challenge you to make your own frontier.
You'll spend the day with the builders, researchers, and technical leaders pushing AI forward.
Lin Qiao. Jensen Huang. Jay Parikh. And more.
Apply to attend: https://t.co/9TTDskVI73
The most ambitious companies are training models to outperform the frontier on the capabilities that differentiate their business.
Today, we announce the general availability of our Training API and Fireworks Lab, making model specialization accessible to all organizations.
Do you know you can use open weight models like GLM, Deepseek, Kimi in Claude Code?
Setup Fireworks account - you get free credits on signup
$ curl -fsSL https://t.co/t5W9mwLvZw | bash
$ fireconnect login
$ fireconnect claude
That's it!
Best part? you can use /model to switch b/n Anthropic and Open models.
Open models just crossed the intelligence-cost curve.
Most of your team's bill is from routine work at frontier prices.
We make it easy to own your AI spend, without changing the way your engineers work.
Introducing Fireworks Nexus: https://t.co/02UFhZL6mX
Happy to have @FireworksAI_HQ as our day0 launch partner and bring Kimi K3 to more developers.
With Fireworks, you can now deploy and fine-tune the 2.8T Kimi K3 model with just a few clicks!
Make Kimi K3 yours with LoRA training on Fireworks Training a model this massive used to be a big project.
With Fireworks Training, you can take the best open model in the world and efficiently tune it to your unique workloads, without paying frontier prices or touching a GPU cluster.
https://t.co/42ZbTu1K3Z