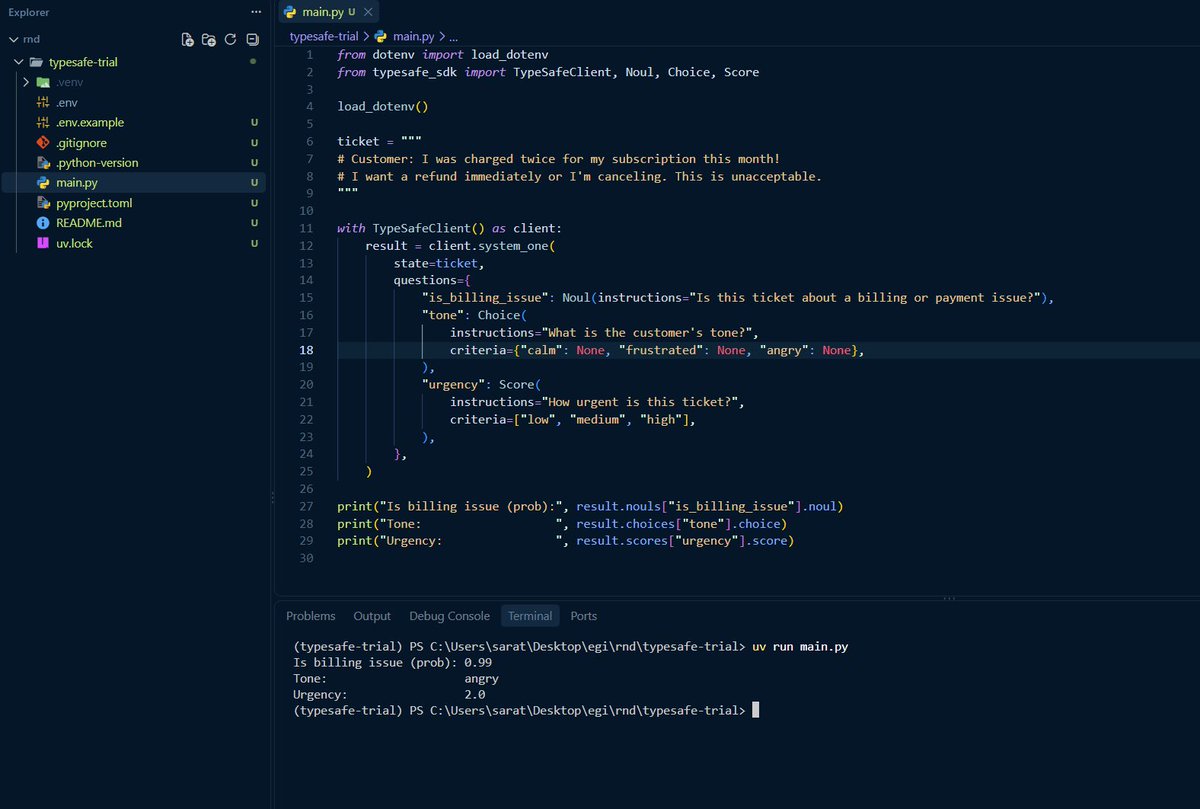
Just tried Jev by @typesafeai
Ran it as sentimental classifier and also as an input guardrail for chatbot.
Structured decisions.
No hallucinations.
Genuinely fast.
Worth exploring.
After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI?
I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev
• 20-200x faster
• 40-400x cheaper (w/ output tokens free)
• Frontier composable intelligence optimized for decisions
AFAICT the shortest path to AI-based economic revolution
The Kimi K3 architecture figure for yesterday's big open-weight model release, along with some observations and thoughts.
1. Yes, it looks relatively complicated, but it's essentially a scaled-up production version of their Kimi Linear model they released last year (scaled up from 48B -> 2.8T; K3 is by far the biggest open-weight model right now)
2. The one new component compared to Kimi Linear is the LatentMoE. I omitted it in the figure below since it's already very crowded, but that's essentially the same LatentMoE as in Nemotron 3 Ultra (you can find it in my LLM Architecture Gallery if you are curious). The idea here is to compress (down-project) large linear layers similar to multi-head latent attention.
3. Kimi K3's overall trend (similar to Nemotron 3, DeepSeek V4, and others) is also towards better inference efficiency. That is, there are many components that replace existing components with efficiency-tweaked versions. I.e., MoE -> LatentMoE, regular attention -> multi-head latent attention and Kimi Delta Attention. (I also have short tutorials and write-ups in my gallery if you are curious about additional details).
4. The one component change that is not an efficiency tweak is attention residuals. Like DeepSeek V4 improved the residual path with mHC (manifold-constrained Hyper-Connections), attention residuals are a way to improve the residual path, but it works a bit differently. I.e., mHC made the residual path wider. Attention residuals (also already part of Kimi Linear) connect the residuals across layers; the connection itself uses an attention score for an important/contribution weight. According to the report, it improves the validation loss and downstream performance (a bit) consistently and adds about 4% in training cost and 2% in inference cost.
5. Interestingly, Kimi K3 got rid of all RoPE layers and uses NoPE (No Positional Embeddings) everywhere instead. (Again, this is inherited from Kimi Linear). In other architectures, the recent trend was towards RoPE in local attention layers (like sliding window attention) and NoPE in the global layers. There were a few architectures that only used NoPE everywhere, but this is the first frontier-level one as far as I know.
6. Kimi K3 now also has native multimodal support, which is great!
There are several other interesting training tidbits in the technical report, but that's it from the architecture front so far. A really great release overall.
Unveiling our new startup Advanced Machine Intelligence (AMI Labs).
We just completed our seed round: $1.03B / 890M€, one the largest seeds ever, probably the largest for a European company.
We're hiring!
[the background image is the Veil Nebula - a picture I took from my backyard, most appropriate for an unveiling]
More details here:
https://t.co/eWHyGLXwCA
Advanced Machine Intelligence (AMI) is building a new breed of AI systems that understand the world, have persistent memory, can reason and plan, and are controllable and safe.
We’ve raised a $1.03B (~€890M) round from global investors who believe in our vision of universally intelligent systems centered on world models. This round is co-led by Cathay Innovation, Greycroft, Hiro Capital, HV Capital, and Bezos Expeditions, along with other investors and angels across the world.
We are a growing team of researchers and builders, operating in Paris, New York, Montreal and Singapore from day one.
Read more: https://t.co/kyVAL7EoFx
AMI - Real world. Real intelligence.
Yann LeCun (@ylecun) just revealed why he left Meta, Why are LLMs an extremely narrow field, and how "World model" is the way to build really meaningful agentic future. 🎯
Beautiful and simple in 1.5 mints.
"I can’t imagine we can build agentic systems without those systems having the ability to predict, in advance, what the consequences of their actions are going to be. The way we act in the world is that we can predict the consequences of our actions, and that’s what allows us to plan.
So what is a world model? Given the state of an environment, a system you want to control at time t, and given an action or intervention you imagine taking, can you predict the state of the world (or the system) at time t + 1? If you can, that’s a world model. You don’t do this at a pixel level, if it’s video. You do this in an abstract representation space, and that’s a crucial key insight."
---
From 'AI House Davos" YT channel (full link in comment)
A few random notes from claude coding quite a bit last few weeks.
Coding workflow. Given the latest lift in LLM coding capability, like many others I rapidly went from about 80% manual+autocomplete coding and 20% agents in November to 80% agent coding and 20% edits+touchups in December. i.e. I really am mostly programming in English now, a bit sheepishly telling the LLM what code to write... in words. It hurts the ego a bit but the power to operate over software in large "code actions" is just too net useful, especially once you adapt to it, configure it, learn to use it, and wrap your head around what it can and cannot do. This is easily the biggest change to my basic coding workflow in ~2 decades of programming and it happened over the course of a few weeks. I'd expect something similar to be happening to well into double digit percent of engineers out there, while the awareness of it in the general population feels well into low single digit percent.
IDEs/agent swarms/fallability. Both the "no need for IDE anymore" hype and the "agent swarm" hype is imo too much for right now. The models definitely still make mistakes and if you have any code you actually care about I would watch them like a hawk, in a nice large IDE on the side. The mistakes have changed a lot - they are not simple syntax errors anymore, they are subtle conceptual errors that a slightly sloppy, hasty junior dev might do. The most common category is that the models make wrong assumptions on your behalf and just run along with them without checking. They also don't manage their confusion, they don't seek clarifications, they don't surface inconsistencies, they don't present tradeoffs, they don't push back when they should, and they are still a little too sycophantic. Things get better in plan mode, but there is some need for a lightweight inline plan mode. They also really like to overcomplicate code and APIs, they bloat abstractions, they don't clean up dead code after themselves, etc. They will implement an inefficient, bloated, brittle construction over 1000 lines of code and it's up to you to be like "umm couldn't you just do this instead?" and they will be like "of course!" and immediately cut it down to 100 lines. They still sometimes change/remove comments and code they don't like or don't sufficiently understand as side effects, even if it is orthogonal to the task at hand. All of this happens despite a few simple attempts to fix it via instructions in CLAUDE . md. Despite all these issues, it is still a net huge improvement and it's very difficult to imagine going back to manual coding. TLDR everyone has their developing flow, my current is a small few CC sessions on the left in ghostty windows/tabs and an IDE on the right for viewing the code + manual edits.
Tenacity. It's so interesting to watch an agent relentlessly work at something. They never get tired, they never get demoralized, they just keep going and trying things where a person would have given up long ago to fight another day. It's a "feel the AGI" moment to watch it struggle with something for a long time just to come out victorious 30 minutes later. You realize that stamina is a core bottleneck to work and that with LLMs in hand it has been dramatically increased.
Speedups. It's not clear how to measure the "speedup" of LLM assistance. Certainly I feel net way faster at what I was going to do, but the main effect is that I do a lot more than I was going to do because 1) I can code up all kinds of things that just wouldn't have been worth coding before and 2) I can approach code that I couldn't work on before because of knowledge/skill issue. So certainly it's speedup, but it's possibly a lot more an expansion.
Leverage. LLMs are exceptionally good at looping until they meet specific goals and this is where most of the "feel the AGI" magic is to be found. Don't tell it what to do, give it success criteria and watch it go. Get it to write tests first and then pass them. Put it in the loop with a browser MCP. Write the naive algorithm that is very likely correct first, then ask it to optimize it while preserving correctness. Change your approach from imperative to declarative to get the agents looping longer and gain leverage.
Fun. I didn't anticipate that with agents programming feels *more* fun because a lot of the fill in the blanks drudgery is removed and what remains is the creative part. I also feel less blocked/stuck (which is not fun) and I experience a lot more courage because there's almost always a way to work hand in hand with it to make some positive progress. I have seen the opposite sentiment from other people too; LLM coding will split up engineers based on those who primarily liked coding and those who primarily liked building.
Atrophy. I've already noticed that I am slowly starting to atrophy my ability to write code manually. Generation (writing code) and discrimination (reading code) are different capabilities in the brain. Largely due to all the little mostly syntactic details involved in programming, you can review code just fine even if you struggle to write it.
Slopacolypse. I am bracing for 2026 as the year of the slopacolypse across all of github, substack, arxiv, X/instagram, and generally all digital media. We're also going to see a lot more AI hype productivity theater (is that even possible?), on the side of actual, real improvements.
Questions. A few of the questions on my mind:
- What happens to the "10X engineer" - the ratio of productivity between the mean and the max engineer? It's quite possible that this grows *a lot*.
- Armed with LLMs, do generalists increasingly outperform specialists? LLMs are a lot better at fill in the blanks (the micro) than grand strategy (the macro).
- What does LLM coding feel like in the future? Is it like playing StarCraft? Playing Factorio? Playing music?
- How much of society is bottlenecked by digital knowledge work?
TLDR Where does this leave us? LLM agent capabilities (Claude & Codex especially) have crossed some kind of threshold of coherence around December 2025 and caused a phase shift in software engineering and closely related. The intelligence part suddenly feels quite a bit ahead of all the rest of it - integrations (tools, knowledge), the necessity for new organizational workflows, processes, diffusion more generally. 2026 is going to be a high energy year as the industry metabolizes the new capability.