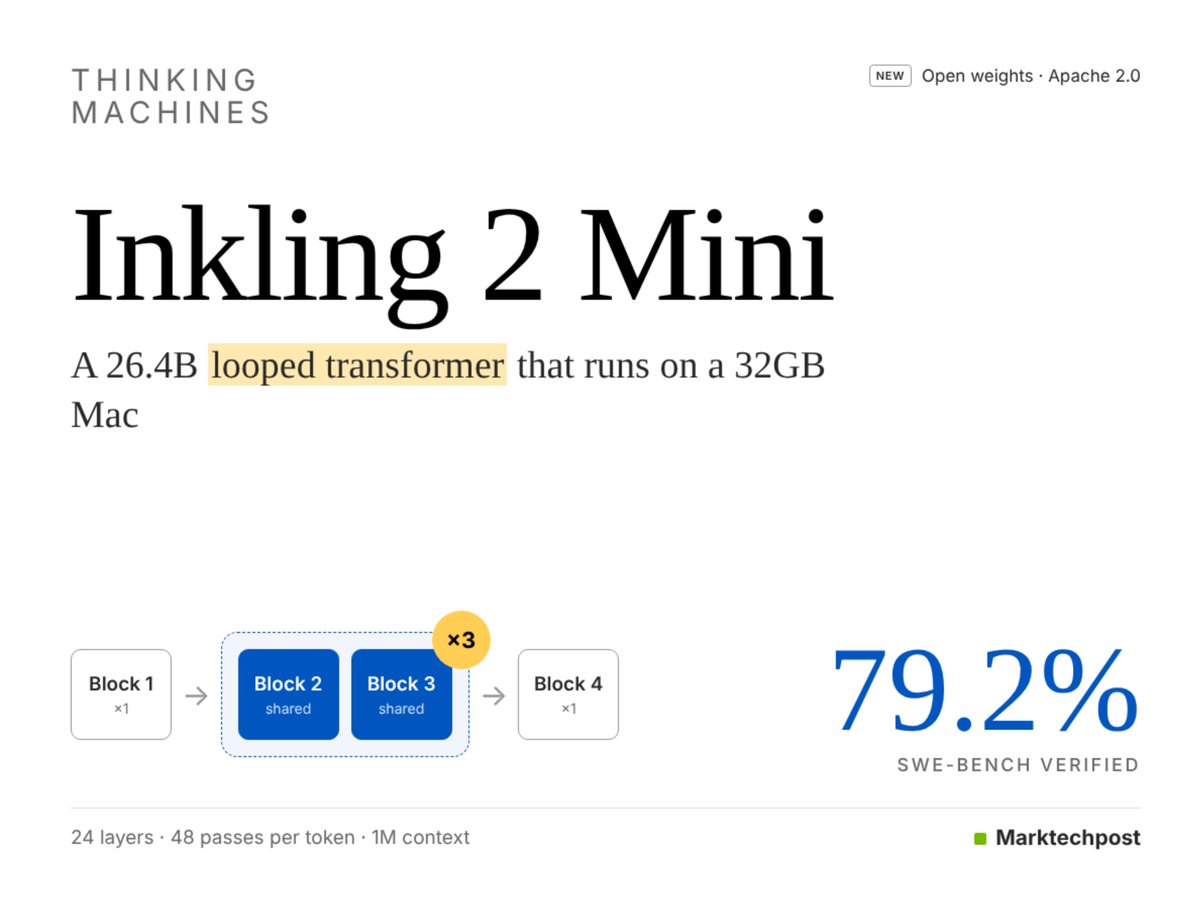
▲ Thinking Machines just released Inkling 2 Mini, a 26.4B looped transformer small enough to run on a 32GB Mac.
The key idea is looping. The model stores 24 layers but runs the middle 12 layers 3 times with shared weights. That gives 48 layer passes per token from a ~20GB checkpoint, and each pass gets a gated "message" from the one before.
The numbers: 79.2% on SWE-bench Verified (bash only), 48.2% on DeepSWE 1.1 vs 42.2% for Qwen3.8-27B, and 20.1 on the AA Index, tied with Qwen3.8-27B. It is a trade-off though: knowledge recall lags, with a 63.4% non-hallucination rate and 50.0% on MultiChallenge.
26.4B total, 3.4B active, up to 1M context, Apache 2.0. Serve it with vLLM, SGLang, Ollama or llama.cpp, or use it hosted on Tinker......
Full analysis: https://t.co/SH4vzg2fs6
Model: https://t.co/UxmqOb0inz
Model card: https://t.co/rrTgOYvSCu
Technical details: https://t.co/ALYsLXVptx
@thinkymachines@miramurati
▲ Baseten just released bison-1 and groundhog-1, decision models that move its Base Labs family onto Google's Gemma 4, with 128k context and image input.
The key idea is that these models never write text. You send 1 state plus typed questions (yes/no, choice, score), and the model returns calibrated probabilities in a single prefill pass. Baseten credits the Gemma base and more "soft labels" in training for better calibration.
bison-1 (31B) scores 76 on the Artificial Analysis Decision Index v2.1, ahead of Liquid AI's d1.2-ultra (75) and Baseten's own mammoth-1 (71). Its Brier score is 0.14. It is a trade-off though: bison-1 ranks only #11 on the knowledge-heavy AA-Omniscience-Decision component (60), and groundhog-1 has no official index score yet.
bison-1 costs $0.10 per 1M input tokens. groundhog-1 (26B MoE, about 4B active) costs $0.035. Both are live on Baseten Model APIs, with open BF16 weights on Hugging Face under MIT plus Apache 2.0......
Full analysis: https://t.co/RRwbAEjnJC
Model: https://t.co/efAYpS89rj
Model: https://t.co/U0XIH6c8G9
Technical details: https://t.co/Gvf13Ol9Br
@baseten@amiruci
▲ RadixArk just released DaisyRose-27B, a 27B agentic coding model trained on top of Qwen3.8-27B with reinforcement learning only. No SFT, no distillation.
The key idea is targeted RL on a small task set. RadixArk and Eigent AI curated about 1,200 tasks, each aimed at a known failure of the base model. Training ran fully async on their open-source Miles framework: 128 H200s generate agent rollouts while 16 H200s train.
The headline number: Terminal Bench 4.1 pass@1 goes from 5.6 to 12.0. DeepSWE v1.1 rises from 42.2 to 46.2, and SWE Bench Pro v2 from 91.3 to 94.7. It is a trade-off though: HLE (text only) moves just +0.4, to 34.3, and the 309B MiMo V2.6 Flash still leads Terminal Bench 4.1 at 16.1. All scores are self-reported.
The run took 18 days and 63,000 GPU-hours, at 37% MFU. Weights are Apache 2.0, with a 262,144-token context, and fit on 1 GPU: about 52 GB in BF16, 29 GB in FP8, 23 GB in NVFP4......
Full analysis: https://t.co/yJf77YOPny
Model: https://t.co/ZKUBj5a99G
Blog: https://t.co/EWc8kFTcmL
Repo: https://t.co/HzqckzbTLV
@radixark
▲ NVIDIA just released Nemotron-Labs-Sigma, 14 continuous diffusion language model checkpoints at 3B and 8B that denoise text the way image models denoise pixels.
The key idea is moving diffusion out of discrete token space. Each token becomes a point in a learned 16-D embedding space. The model adds Gaussian noise to those points and learns to remove it, block by block. Smooth trajectories make few-step distillation and steering practical.
On NVIDIA's 6-task base suite, Sigma-8B averages 71.16 vs 70.22 for NLD-8B, NVIDIA's discrete diffusion model. HumanEval is 65.12 vs 62.80. The self-speculative 8B decodes 3.46x faster than AR on average (up to 4.20x) on 1 GB200. It is a trade-off though: the instruct average of 59.14 trails NLD-8B at 59.92, and AIME25 sits at 17.00......
Full analysis: https://t.co/paVMceXKC2
Models: https://t.co/FeApP5EdLu
Paper: https://t.co/MaZNIDvjNF
@nvidia@MardaniMorteza
▲ AI is changing how attacks happen, and how fast. More companies will face a security incident. The question is no longer if, but how they respond.
Attackers now run AI agents that scan, plan and break in at machine speed. CrowdStrike reported 1 AI-agent group hitting more than 200 organizations in 11 days. Unit 42 found attacks moving about 4 times faster than a year earlier.
This article sets out a 4-pillar playbook: detect and contain automatically, communicate fast over secure channels, eradicate thoroughly with outside forensics, and keep shrinking the blast radius. It is a trade-off though: no company can promise it will never be breached, and responsibility is shared with suppliers, vendors and customers.
Full analysis: https://t.co/A01x5aufEa
Fireworks data retention post: https://t.co/hLsPSw7OJK
@FireworksAI_HQ
▲ Google just released Gemini 4 Neon, a mid-tier Gemini 4 model that targets near-frontier agent scores at a lower cost per task.
The key idea is a middle tier between Carbon and Hydrogen. Neon has 4 thinking levels (high by default, xhigh for the hardest work) and a 1M context window. In Google Antigravity it acts as an orchestrator over parallel Hydrogen subagents.
On Google's table it scores 61 on the AA Intelligence Index, vs 59 for Claude Opus 5.5 and 57 for GPT-6.2 Sol. It hits 95.2% on GraphWalks (256K to 1M) vs 66.8% for Opus 5.5, and 39.0% on SWE-sweep vs 10.1%. It is a trade-off though: Opus 5.5 still leads Terminal-bench 4.1 (65.8% vs 65.2%) and FrontierCode 2.0 (47.3% vs 46.2%), and every number is self-reported.
Rolling out now on the Gemini API paid tier, Gemini for business, Antigravity and the Gemini app for Pro and Ultra subscribers. Closed weights, $3 input and $15 output per 1M tokens......
Full analysis: https://t.co/NJVDGpDijM
Technical details https://t.co/9fEbP1s5cO
Model card: https://t.co/vGC06yMWHF
Try it: https://t.co/aTeS5sjVgK
@googledevs@GoogleAIStudio@Antigravity@GeminiApp
▲ Nutrient's Data Extraction API turns PDFs, scans and Office files into JSON matching your schema, with every field traced back to the page.
The key idea is evidence per field. Each extracted value carries a page, a bounding box and a match label, plus a confidence score when the engine has one. Gate on the match label first, then confidence.
On Nutrient's new WholeDoc Bench, Agentic mode scores 86.2 overall at 1.8¢ per page, top of 19 settings. The best frontier-model setting scores 67.1 at 17.8¢. It is a trade-off though: Nutrient built the benchmark, its main test set is private, and charts top out at 64.5.
Studio lets you configure and test parsing, extraction, classification and splitting in the browser before any API call. Parse costs $0.001 to $0.018 per page by mode, and the free plan includes $5 of usage a month......
Full analysis: https://t.co/76Rd6rPTqA
API: https://t.co/EFg6T82rQj
Studio: https://t.co/QabUEYdaj9
Benchmark: https://t.co/Az7Qf4CQrl
Skill: https://t.co/uMJQHMc5sp
@nutrientdocs
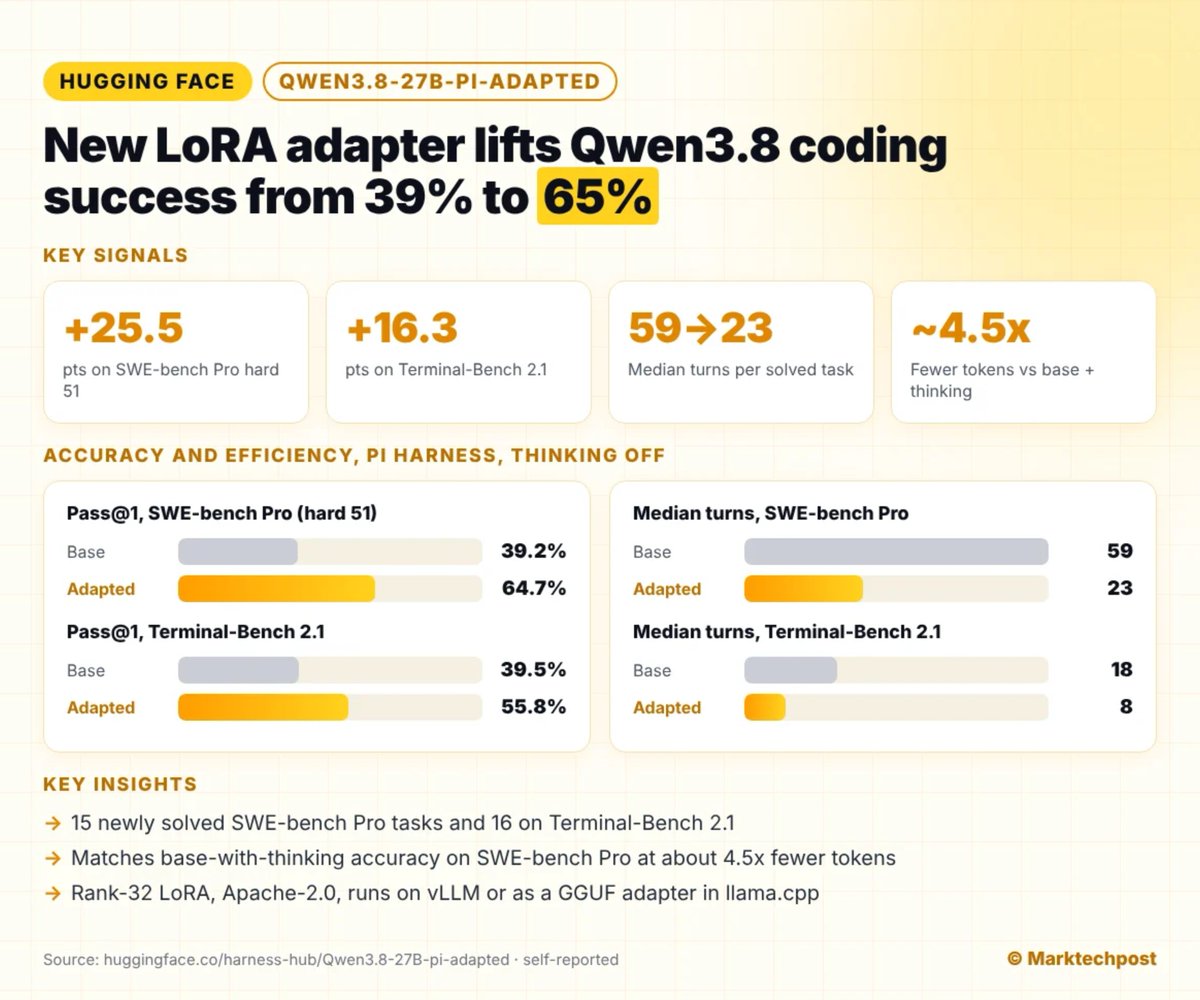
▲ Hugging Face just released Qwen3.8-27B-pi-adapted, a LoRA adapter that lifts Qwen3.8 coding success from 39% to 65% inside the pi coding agent.
The key idea is 1 small adapter per model and harness. The team trained it with reinforcement learning (AsyncGRPO in TRL) directly inside pi, on 750 scale800 and 300 TermGrade tasks. The reward pays for correct answers and gives a bonus for using fewer tool calls.
With thinking off, SWE-bench Pro (hard 51) pass@1 jumps from 39.2% to 64.7%, and Terminal-Bench 2.1 from 39.5% to 55.8%. Sessions get much shorter too: median turns on solved SWE-bench Pro tasks drop from 59 to 23. It matches the base model's thinking-mode accuracy while generating about 4.5x fewer tokens.
Rank-32 LoRA, Apache-2.0, ready for vLLM or as a GGUF adapter in llama.cpp......
Full analysis: [ARTICLE URL]
Model: https://t.co/6OeaVW3ld1
Blog: https://t.co/PzJ82VZWDz
Repo: https://t.co/4vMBwJyOUC
@huggingface@ClementDelangue
▲ SID AI just released SID-2, a search model that replaces fixed RAG pipelines with RL-trained agents that search, read and search again.
The key idea is swarms. SID-2 Swarm runs several small agents that fork their context, message each other and explore different parts of a corpus. SID found that reading more documents helps search more than reasoning harder about each one.
On SID's 506-question benchmark, SID-2 Medium scores 0.585 NDCG in 3.11 s, vs Claude Opus 5.5 at 0.577 in 25.1 s. A 6-agent Swarm hits 0.701 in 17.7 s, vs GPT-6 Astra at 0.704 in 135 s. It is a trade-off though: the 12-agent Swarm (0.720 NDCG) costs $515 per 1,000 queries, nearly 4x Opus 5.5, and every score is self-reported.
Available now via SID's API and Baseten, with Python, TypeScript and Go SDKs. SID-2 costs $0.25 per 1M input tokens and $1.00 per 1M output. Parameter count and weights are not disclosed......
Full analysis: https://t.co/NhO78vaqld
Tech report: https://t.co/fc36lSGYPE
Docs: https://t.co/MkL70CqAo0
Models: https://t.co/iYm8BwxcFj
@SID_AI@maxrumpf
▲ Anthropic just shipped Code Mode in Claude Code, so Claude can now write JavaScript that chains its own tool calls in 1 step.
The key idea is simple. Without Code Mode, Claude asks for each Bash, Read or Edit call and reads every result. With Code Mode, Claude writes 1 program that runs commands in parallel, feeds one result into the next call, and returns only the output it needs.
The numbers: code that runs in the background can keep going for up to 2 hours while you keep talking to Claude. Anthropic's related code execution with MCP pattern cut 1 workflow from 150,000 to 2,000 tokens. It is a trade-off though: Anthropic publishes no token figure for Code Mode itself, code Claude waits on stops after 10 minutes, and auto mode reviews the code, not each tool call.
It is experimental and off by default. Opt in with CLAUDE_CODE_EXPERIMENTAL_CODE_MODE=1 on Claude Code v2.1.323 or later. It works with Opus 5.5, Sonnet 5.5, Haiku 5.5 and Fable 5.2, in the terminal, on the Anthropic API only......
Full analysis: https://t.co/AQYGME7jD1
Docs: https://t.co/ffneHuvSJA
Background: https://t.co/22QcKaBf8x
@AnthropicAI@ClaudeDevs
▲ Zero data retention is one of the most misunderstood terms in AI infrastructure. Whether your AI provider keeps your data depends on which API design you use.
The key idea for this analysis comes from Fireworks AI CEO Lin Qiao's X Post: There are 2 standard API designs, and each one decides where the data lifecycle is managed. Customer-managed retention is upload, use, delete. Ephemeral processing is send, compute, return.
Batch APIs follow the first design at OpenAI, Amazon Bedrock, Gemini and Fireworks AI. The data stays until you delete it. Inference APIs like OpenAI Chat Completions, Bedrock Converse and Fireworks Chat Completions follow the second. It is a trade-off though: some stored features expire by default (OpenAI batch files after 30 days, Anthropic batch data after 29), while others stay until you delete them.
In both designs, the customer is in control. Ephemeral is preferable whenever the workflow allows it: no forgotten datasets, no missed delete calls, nothing at rest to protect......
Full analysis: https://t.co/wNNIMXxGCD
@lqiao@FireworksAI_HQ
▲ NVIDIA just open-sourced NVKE and NVKR, a reference stack that lets GPU clouds run their own managed Kubernetes service, EKS-style, on bare metal.
The key idea is a clean split. NVKE is the management plane: a REST API and controllers that create customer clusters, each with its own control plane, etcd and node pools. NVKR builds and signs the node images, container images and Helm charts those clusters run.
NVKE is conformance tested on Kubernetes 1.36 and is a Certified Kubernetes AI Platform. Nodes must present a TPM-attested SPIFFE identity before they get join credentials. Gardener, the closest open-source peer, lists conformance up to 1.35. It is a trade-off though: after install, the NVKE API serves plain HTTP on port 30080 with authentication off, and there is no management-plane upgrade or backup procedure yet.
Both are Apache 2.0 and in public preview...
Full analysis: https://t.co/5OEdiol1m7
NVKE: https://t.co/HbiZfAbHnB
NVKR: https://t.co/7JoSTQ7Cdj
Docs: https://t.co/9kugBASbID
@NVIDIAAIInfra
Build a 2027 Lunar Calendar Using Python!
What if you could calculate every major Moon phase in 2027 using just a few lines of Python?
This project demonstrates how to use Python's ephem library to calculate:
New Moon
First Quarter
Full Moon
Last Quarter
It also uses:
ephem for astronomical calculations
rich for beautiful terminal tables
Python datetime formatting for readable dates
A great mini-project for Python developers interested in astronomy, automation, and scientific computing!
Book: Unlock your full potential in Python with 100 practical, real-world projects designed to take you from complete beginner to confident developer. This book is hands-on, structured, and explanation-focused — perfect for students, self-learners, and working professionals who want to learn by building, not just reading.
Whether you're preparing for placements, improving coding logic, or building portfolio-ready projects — this book gives you everything you need.
https://t.co/ZNQeLuU3jh