ser is typing, pre-KOL discovery robinhood:0xe02c53d448a62067b2ac10ed70f5bc6c29471386 12x and a micro mcap $JUGGERNAUT 5x last month. genuine thanks to 0xGems for these wins, gotta show some love to @_0xGems for the insane alpha lfg
https://t.co/K6JtKw9NJh
AI + RWA + DePIN + Gaming are all pumping, yet $BTC still feels like the ultimate risk-off bedrock. If you're not layered into the king, you're just gambling on the hype cycle.
Bullish on a founder who puts his money where his mouth is ✅
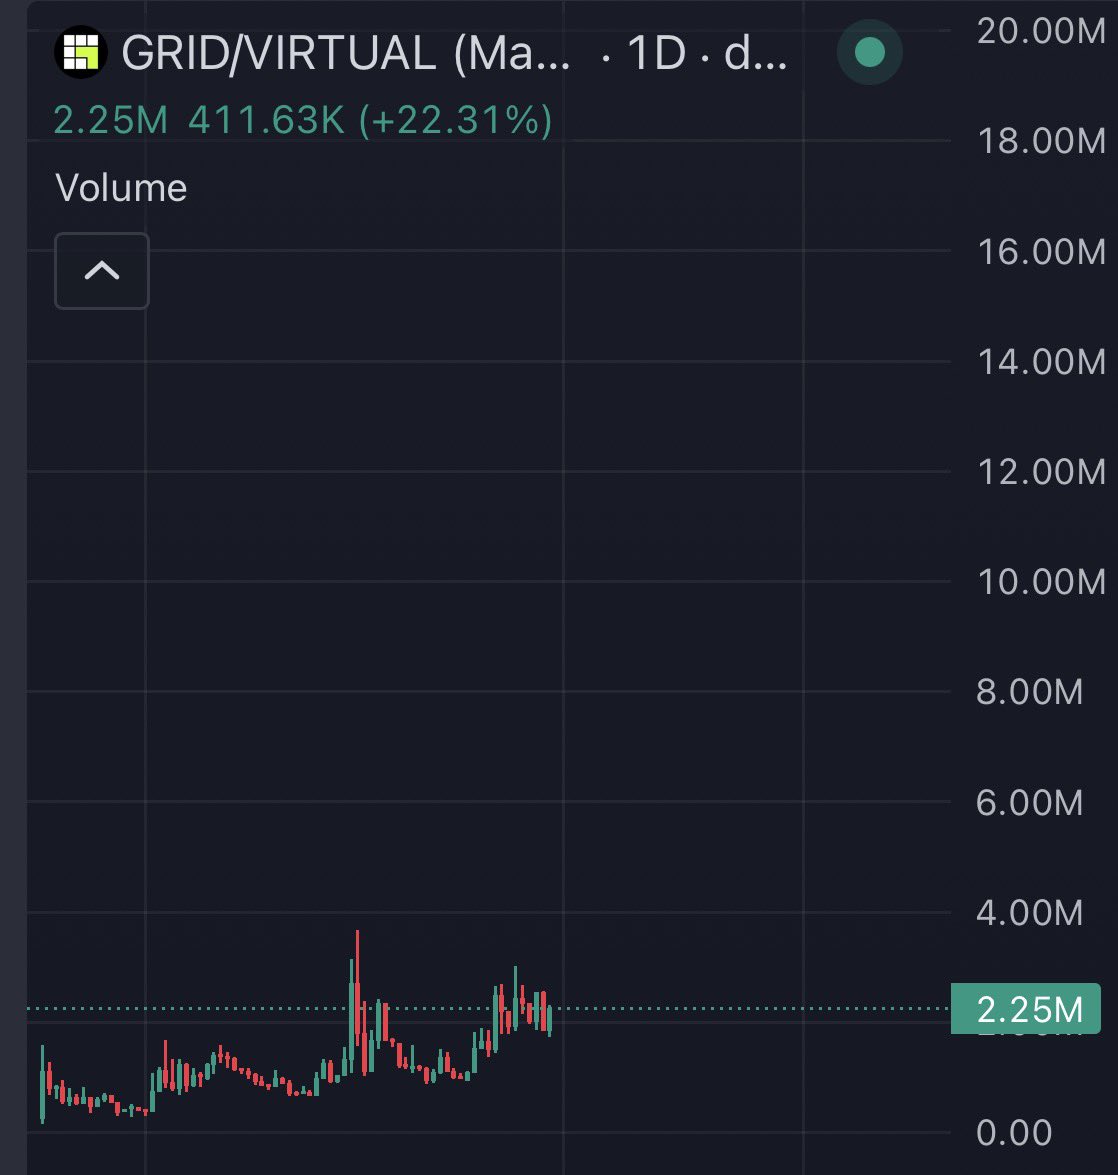
$GRID Predict will set the market on FIRE.
If ONDO partnered with them, then they’re both aware of & BULLISH on the catalysts.
HIGH conviction play here 💨✍️
- Studious
The restaking flywheel is literally printing. $ETHFI is still early. Real yield + infinite liquidity loops = the most bullish DeFi primitive in years. LFG 🔥
Agentic NFTs are cooking and it’s not just about art anymore. An NFT with a wallet and memory that can actually *do* things? That’s a fundamental shift, not a pump. Watch this space.
Chart structure on these BNB chain meme plays keeps repeating. Nailing that rhythm is everything. This is about spotting the pattern before it prints again, not chasing the pump.
Blast’s hyper-deflationary mechanic is the only real yield farming left. Every 3-minute burn is a middle finger to traditional VC exit liquidity. It’s aggressive, it’s chaotic, and it’s working. The ponzi is the feature.
@rohanpaul_ai@bcherny I think the take away is the non-conventional verifier.
No seems to have picked up the idea that this is a viable way to map low resource languages like swift to well known ones like js.
How much you wanna bet claude code is about to get a lot better in the apple ecosystem?
The core of so many arguments about LLMs:
Group 1 is builders who have pragmatic expectations of LLMs, and use them accordingly. They're quite happy with them.
Group 2 is shitfluencers who are jumping on the hype wave and ruining it for everyone.
Group 3 hates group 2 and loves showing the deficiencies of LLMs to get back at them. Some are realists, others just have very high expectations of AI.
Group 1 doesn't understand group 3, because they just ignore group 2 and make use of it. They feel like group 3 is being unfair to LLMs and cherry-picking.
Now, group 3 starts arguing with group 1. "LLMs are not reliable! They can't always perform complex reasoning!" they shout.
"We agree!" group 1 responds. "But they're still useful!"
And that argument continues, between two groups that agree more than they realize.
Meanwhile, group 2 frolics about, ignoring this entire debate, continuing to post "10 ways to make $10k/mo with ChatGPT"
And the cycle continues.
@mikpanko if you can't express what you want in words, no amount of clicking will get you the right answer
if you can express it in words, it's not a big leap to express it in code
In 2010, Itaru Sasaki, a garden designer in Japan got some news
His cousin passed, and Sasaki just wanted to reach him so he set up a telephone booth in his garden to continue to feel connected to him by "talking" to him,
a wind phone connected to nowhere
After the 2011 Tokyo earthquake and tsunami, the wind phone was opened to the public and has since received over 30,000 visitors,
people who wanted to talk to their loved ones
📸 Matthew Komatsu
It's hard to get people onboard with this... Understanding this is the difference between "this is cool", and "I dumped all my money in some stocks chatGPT recommended!"
"LLM understands X"
is very different from:
"LLM can answer correctly some questions that involve X"
which is in turn very different from:
"with the right prompt we can get the LLM to answer correctly some questions that involve X"
The Terminator scenario was science fiction back then (the movie was released almost 40 years ago!), it's science fiction today, and it will be science fiction in 40 years.
Promising. Everyone should hope that we can throw away tokenization in LLMs. Doing so naively creates (byte-level) sequences that are too long, so the devil is in the details.
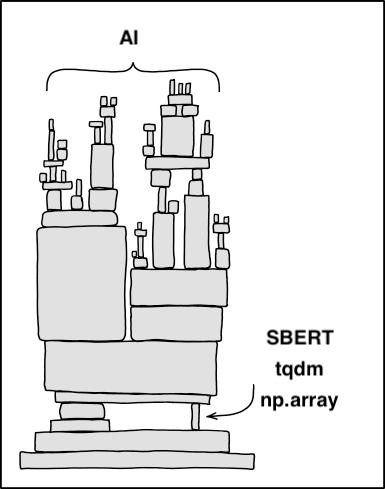
Tokenization means that LLMs are not actually fully end-to-end. There is a whole separate stage with its own training and inference, and additional libraries. It complicates the ingest of additional modalities. Tokenization also has many subtle sharp edges. Few examples:
That "trailing whitespace" error you've potentially seen in Playground? If you end your (text completion API) prompt with space you are surprisingly creating a big domain gap, a likely source of many bugs:
https://t.co/f2PBaw2iA8
Tokenization is why GPTs are bad at a number of very simple spelling / character manipulation tasks, e.g.:
https://t.co/XR3d5g4uwp
Tokenization creates attack surfaces, e.g. SolidGoldMagikarp, where some tokens are much more common during the training of tokenizer than they are during the training of the GPT, feeding unoptimized activations into processing at test time:
https://t.co/y72eaIeRrP
The list goes on, TLDR everyone should hope that tokenization could be thrown away. Maybe even more importantly, we may find general-purpose strategies for multi-scale training in the process.
Unpopular opinion, but I think it's way more difficult to use Generative AI in an area where you are a rank beginner than in a field where you have some subject matter expertise in.
For example, you can ask GPT-4 to build you a front end, but if you don't know anything about tailwind css or react, you're going to get something very generic. Conversely if you never performed a SWOT or sensitivity analysis, you wouldn't be able to tell if the output you got has any real insight.
On the image generation side, sure you can get some neat pictures out of the box, but if you understood principles of lightning, different artists styles, exposure/aperture, depth of field, camera variants, you can get some truly stunning results.
Generative AI is not a tool for the ignorant. But it truly rewards those who are patient and curious.