➡️ Abe Diaz from Amazon’s disaster relief team discusses how we're innovating ways to respond to communities after disaster strikes. https://t.co/85YxWKN3LL
@jacalulu First take:
1. Powerful. It found a vuln neither Astra or Fable found.
2. Holy smokes. It is FAST!
3. They will soon name a Sesame Street character after this called the “token monster”, because this thing inhaled my quota immediately.
🔥🔥🔥
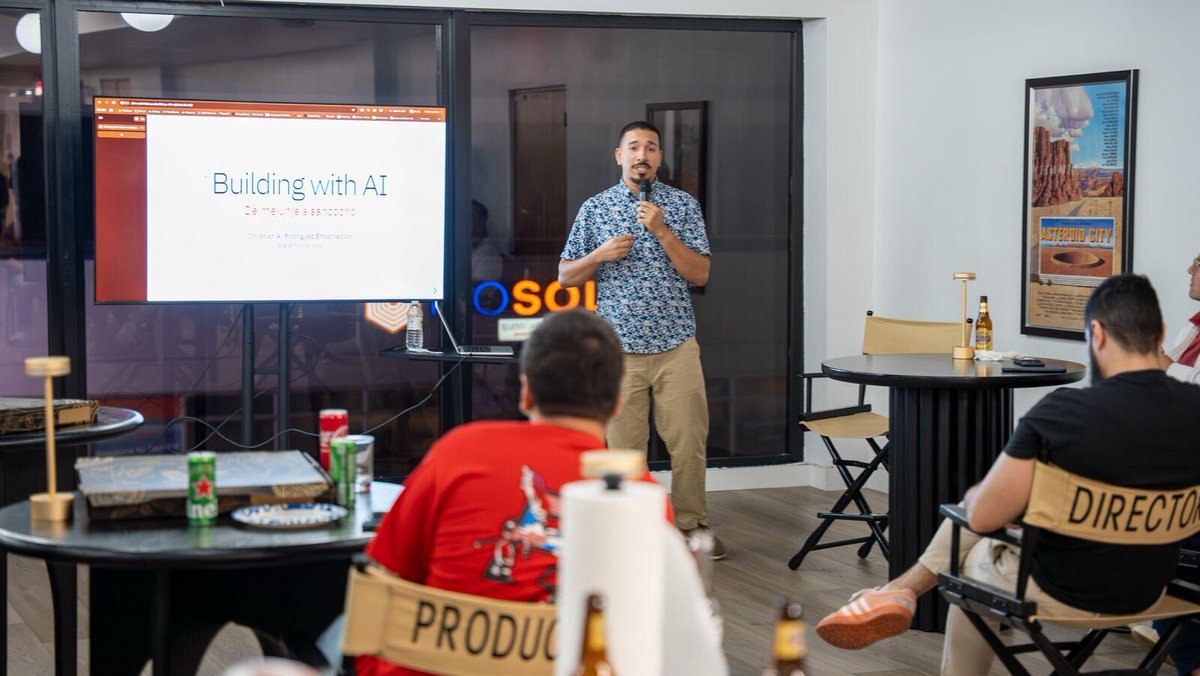
Full house tonight in San Juan for the first Builders' Salon: Building with AI.
Our team was there to share what we've learned along the way with an engaged crowd, and they are ready for the next one.
There's a hunger in Puerto Rico's tech community for events like this. 🇵🇷
My new answer when someone says what kind of presenter would you like to be when you grow up is showing them videos of @CompleteSkeptic being Irreverent, fast paced, authentic and facts driven.
PS : I want this shirt!
Make inference 10x faster. Now the tool calls are the bottleneck.
@nserrino of @gimletlabs walks through why faster models make the rest of your agent stack matter more.
From AI Engineer Code Summit.
Spicy take: RAG is cooked, (well some of it)
A year ago, “who signed this contract?” meant chunking, embeddings, a vector DB, and an evals to hopefully get it working as expected.
Now a 5B open model I can run locally reads the doc and spits the same, with a confidence score...? Sigh, I love the future.
We're rolling out pplx-decider-v1.3 and pplx-decider-flash-v1.3, the latest version of our open-weight decision models.
v1.3 adds locate, a new feature that extracts spans based on type or instructions.
Now available in our Decisions API, @huggingface, and @OpenRouter.
https://t.co/bsTSl2tHSo
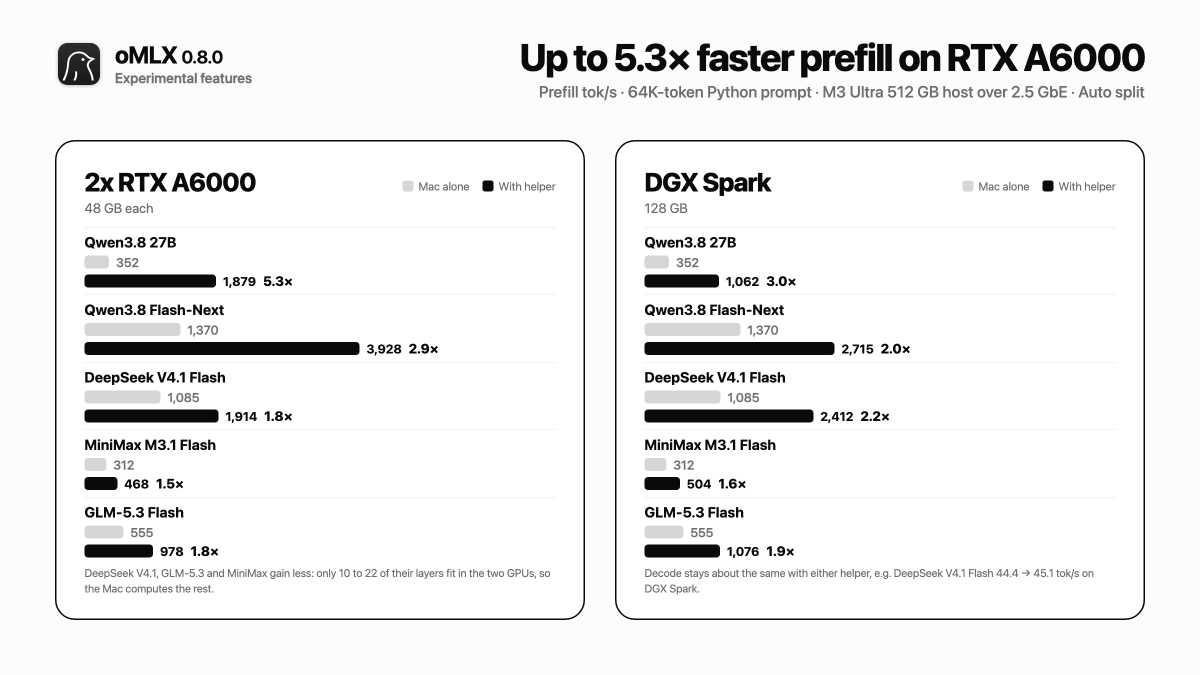
oMLX can now use your NVIDIA GPU or DGX Spark as a Prefill Accelerator.
https://t.co/PRRWHANqQt
All you need is a Mac that can hold the model. A faster NVIDIA GPU or a DGX Spark takes over the prefill, and your Mac keeps decoding at the same speed.
- The GPU doesn't need to fit the model. It speeds up as many layers as it can hold.
- No RDMA, no Thunderbolt. Just plug in a LAN cable (1GbE works, 2.5GbE recommended).
- One docker run on the NVIDIA machine. No oMLX install or SSH needed there.
64K prompt, M3 Ultra 512GB + GPU over 2.5GbE
With a DGX Spark
- Qwen3.8 27B: 352 -> 1,062 tok/s (+202%)
- Qwen3.8 Flash-Next: 1,370 -> 2,715 tok/s (+98%)
- DeepSeek V4.1 Flash: 1,085 -> 2,412 tok/s (+122%)
- GLM-5.3 Flash: 555 -> 1,076 tok/s (+94%)
With 2x RTX A6000
- Qwen3.8 27B: 352 -> 1,879 tok/s (+434%)
- Qwen3.8 Flash-Next: 1,370 -> 3,928 tok/s (+187%)
- DeepSeek V4.1 Flash: 1,085 -> 1,914 tok/s (+76%)
- GLM-5.3 Flash: 555 -> 978 tok/s (+76%)
The CUDA helper builds on the great CUDA kernels of TensorFold by @ashxhart and mlx-serve by @ddalcu, and would not have been possible without them. Thank you both for sharing them in the open.
Also in 0.8.0rc1
- DeepSeek V4.1 with the DSpark drafter: 8 requests decode 73.2 -> 107.9 tok/s (+47%)
- Concurrent Request Priority: new prompts start sooner while other responses stream
- Affine KV decodes up to 58% faster at long context