After a long time of kaggling, I am extremely happy to announce I've achieved the Kaggle Competition Grandmaster title.
Thank you to everyone who contributed to this journey @The0Viel@CroDoc@dk21@bhutanisanyam1
Special thanks to @ZbyHP for the amazing support.
NVIDIA is hiring! You'd work with Kaggle GMs like Bo Liu and Yauhen Babakin. Kaggle GMs welcomed, but this is not a mandatory qualification.
Job post details: https://t.co/qf8lhbpS1Z
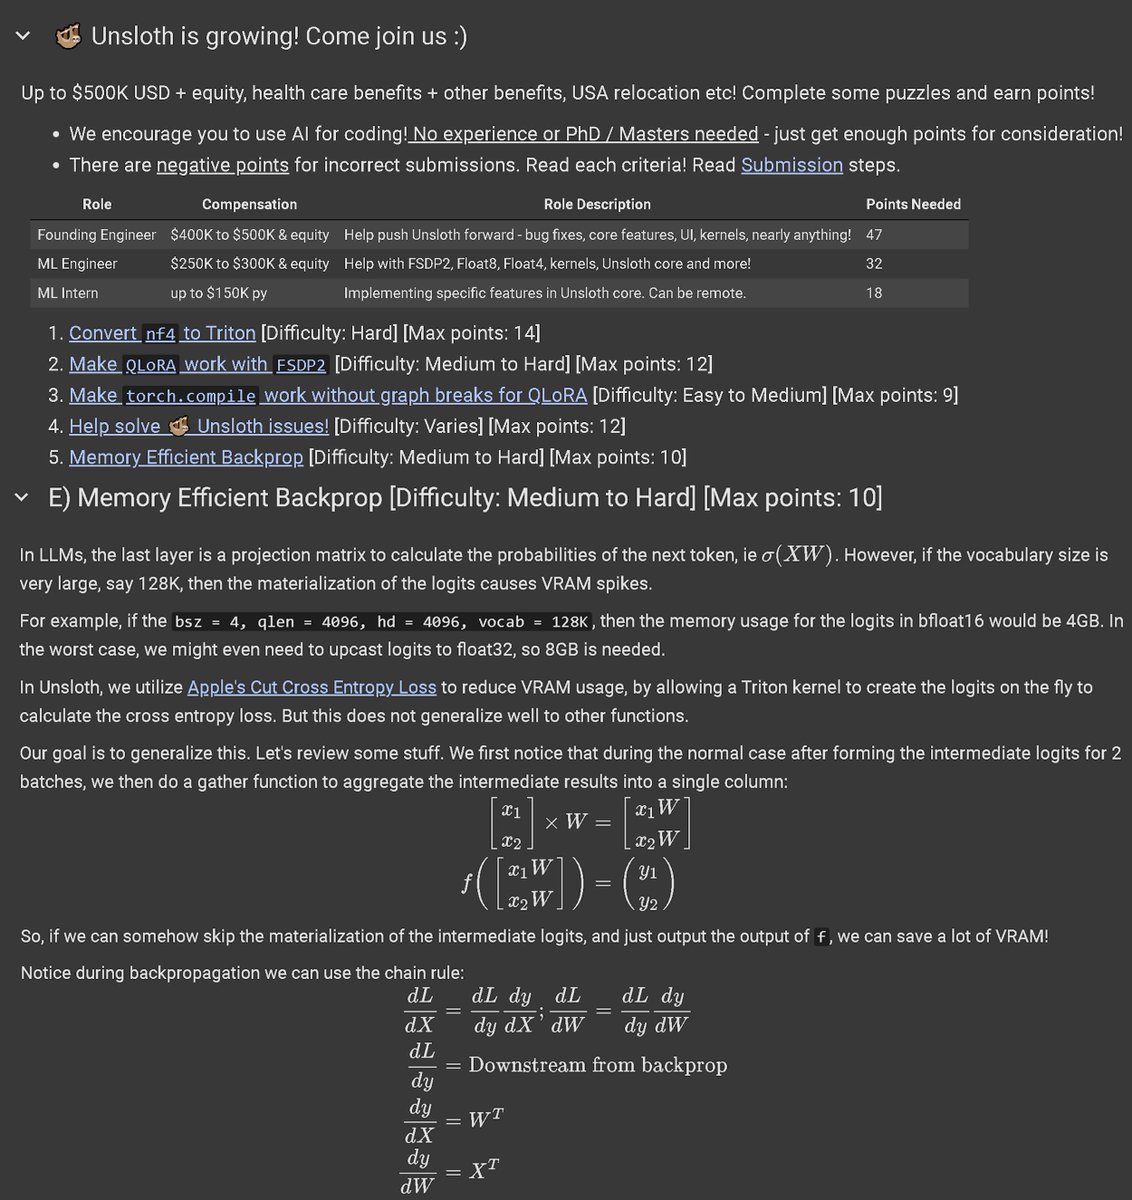
We made 5 challenges and if you score 47 points we'll offer you $500K/year + equity to join us at 🦥@UnslothAI!
No experience or PhD needed.
$400K - $500K/yr: Founding Engineer (47 points)
$250K - $300K/yr: ML Engineer (32 points)
Challenges:
1. Convert nf4 / BnB 4bit to Triton
2. Make FSDP2 work with QLoRA
3. Remove graph breaks in torch.compile
4. Help solve Unsloth issues!
5. Memory Efficient Backprop
If you have any questions about the challenges, please feel free to ask! We're looking for people to help push Unsloth forward - so come join us to democratize AI further!
Our past work includes:
1. 1.58bit DeepSeek R1 GGUFs: https://t.co/gALGkUg5Cg
2. GRPO with Llama 3.1 8B in a Colab: https://t.co/LFdkNxwAYg
3. Gemma bug fixes: https://t.co/7kX94PyKQR
4. Gradient accumulation bug fixes: https://t.co/Tq4c5Qwqyw
Details & submission guide: https://t.co/iXxRUTijWV
NVIDIA is hiring two interns to work on multi modal models and on embedding models for RAG type of applications. You'd work with some great colleagues of mine. Apply there if interested https://t.co/Lbyz5dYzA5
today we are announcing reinforcement finetuning, which makes it really easy to create expert models in specific domains with very little training data.
livestream going now: https://t.co/ABHFV8NiKc
alpha program starting now, launching publicly in q1
@antgoldbloom There's nothing that could teach you the importance of properly evaluating models better than the shake-up experience of kaggle competitions.
And it’s live! The problems are harder and the prize pot is bigger. Our AIMO Manager @friederrrr can answer your questions on the Kaggle board.
Click below for the details of the second Progress Prize and good luck to all entrants!
https://t.co/8b5uERXjd4
🚀 Excited to share our paper "Why Transformers Need Adam: A Hessian Perspective", which is accepted at #NeurIPS2024!
We delve into why SGD lags behind Adam, uncovering the "block heterogeneity" in Transformers' Hessian spectra that Adam navigates more adeptly. 🧠💡
Our findings show that Adam's coordinate-wise rates are crucial for handling this heterogeneity, a game-changer for optimizing Transformers!
Paper Link: https://t.co/jFWs8eIW72
New tasks are often not that independent from previous ones.
I see intelligence as the ability to quickly link a new task to those you've already mastered and continue fine-tuning it until it becomes a skill.
So the more data/experience you have the easier it should be to make connection between things.