https://t.co/2tF0MWGRFN is now a native provider in @NousResearch hermes agent.
no core patches, no proxy wrapper. one plugin registers a provider profile and it shows up in the model picker next to the built-ins
hermes plugins install anyapi
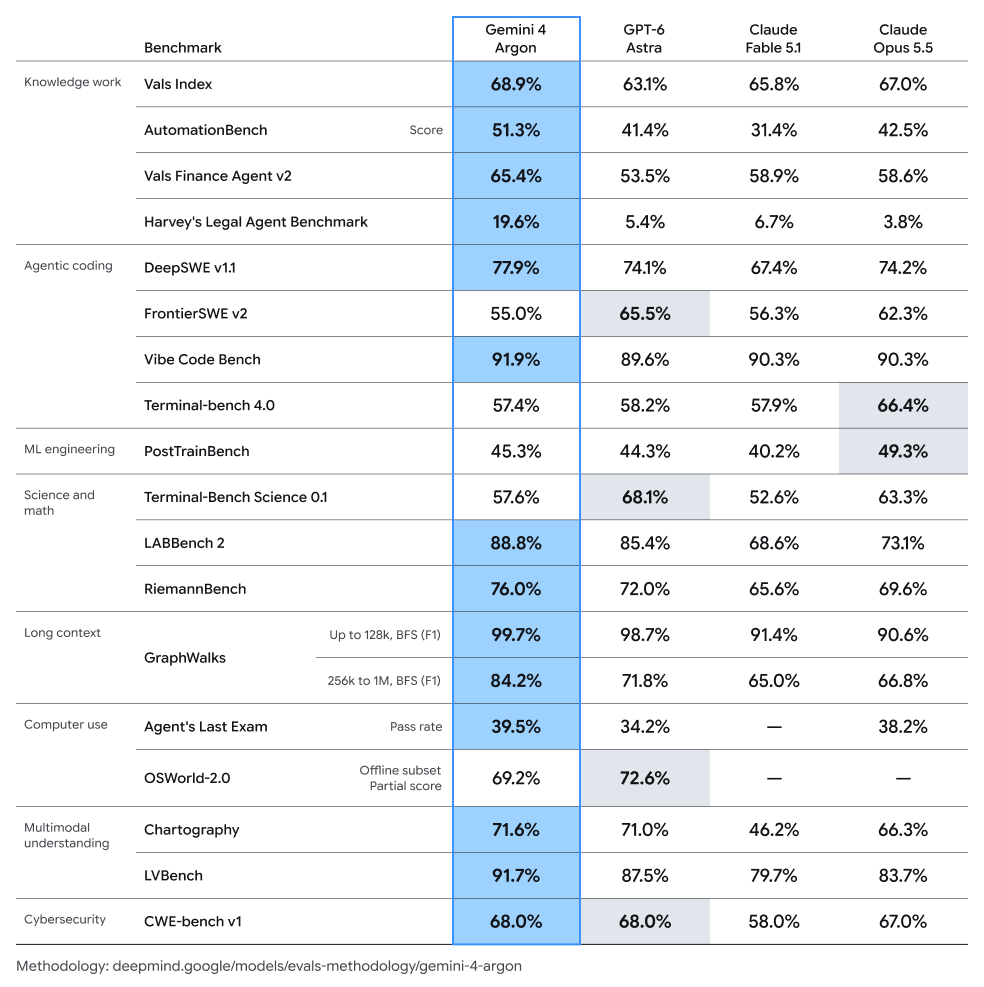
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
GPT-6 Sol beats Claude Opus 5.5 - 5x cheaper and the difference isn't even close
the test: infinite zoom into the Mandelbrot set as a single self-contained HTML file - WebGL shader, multi-precision math, seamless loop
cost : GPT-6 Sol: $0.07
Claude Opus 5.5: $0.35
what we saw:
• Opus burned 2.7x the tokens (17.6k vs 6.6k, most of it reasoning noise)
• Sol's zoom actually zooms: deep exponential dive into Seahorse Valley with plasma filaments, bloom, and a perfectly seamless 6-sec loop
• Opus 5.5 whole frame slowly rotates around a murky blob while the zoom crawls 6x slower - hypnotic in the worst way
• Sol's code: 2× more output per token, denser, runs smoother
verdict: Claude thinks longer. GPT delivers better.
I agree with Dario that we need to pace the frontier. This has been a primary topic of discussions we've had at OpenAI in recent weeks.
Committing to having independent evaluators with employee-like access is a great idea, and we will do the same. We'll have more to share soon.
Fable 5.1 charges 40× more than Gemini 3.8 Flash for the same task.
we threw both, plus GPT-5.6 Sol, at a working V12 engine and a
mechanical chronograph in three.js. same prompts, one shot, no retries.
the bill:
watch: Fable 5.1 $2.14 · Sol $0.08 · Gemini 3.8 Flash $0.05
engine: Fable 5.1 $1.30 · Sol $0.10 · Gemini $0.04
and here's the thing: fable's watch is genuinely the best one. the
escape wheel ticks in discrete steps. the hairspring breathes at 4Hz.
341 parts under a sapphire caseback. 24,346 tokens of pure gear-ratio
thinking went into it, and it shows.
Gemini nails museum framing in 75 seconds flat, then paints the whole
movement one shade of grey. Sol's take is clean and stylized, which
means the truth: it's a facade with hands.
plot twist: fable's 40× engine ships a real bug. idle RPM dips below
zero and the whole frame goes black. the watch is a masterpiece. the
engine, not so much.
so the real answer is ugly: 40× the price buys you the physics under
the dial. sometimes. which one are you picking?
GPT-5.6 SOL vs Claude Fable 5 vs Kimi k3 – 3d rubik's cube in @threejs
the setup: one prompt in, one html file out. streamed straight through AnyAPI, no agent loop, no tools, no filesystem, just a single standalone response per model
models: gpt 5.6 sol , claude fable 5 , kimi k3
prompt: a fully functional 3D Rubik’s Cube simulation in one HTML file, using Three.js via CDN, with automatic self-solving
results:
gpt 5.6 sol – 1.36s, 8,612 total tokens, $1.53, 825 lines
claude fable 5 – 1.26s, 10,725 total tokens, $3.16, 465 lines
kimi k3 – 302.99s, 36,565 total tokens, $3.27, 733 lines
observations:
• sol and fable both returned almost instantly; kimi took 303s on the same task
• fable shipped the shortest file at 465 lines, while sol shipped the largest valid file at 825
• kimi used 4.2x the total tokens of sol and still landed in roughly the same price band as fable