@devswha Nice, the tap-to-approve cards look great. I'm running a single orchestrator session for now (Claude drives Cursor CLI, I just make the calls), so Remote Control covers it. Bookmarked for when I go parallel 🙌
Introducing Claude Opus 5.5, the first model in our new Claude 5.5 family.
It performs at the level of Claude Fable 5.1 for most tasks, and costs 40% less to run than Opus 5.
Grok 4.7 scores 46 on the Artificial Analysis Intelligence Index to bring SpaceXAI into the top 4 AI labs. Coding Agent Index performance has also improved, overtaking GPT-5.6 Sol
Grok 4.7 scores +2 points over Grok 4.6 on the Intelligence Index, with strong performance on agentic knowledge work tasks. We evaluated the new model at xhigh reasoning effort.
Congratulations to @spacexai and @ElonMusk on the release!
Key takeaways:
➤ Grok 4.7 joins the frontier of agentic knowledge work: Grok 4.7 gains +111 Elo over Grok 4.6 (high) on AA-Briefcase, our private benchmark for long-horizon agentic knowledge work, scoring 1657 Elo and placing it alongside Claude Opus 5 and Claude Fable 5.1 at the frontier. On GDPval-AA, it scores 1695 Elo, +90 ahead of Grok 4.6 (high).
➤ A leap in coding agent performance: Grok 4.7 (xhigh) with Grok Build scores 56 on the Artificial Analysis Coding Agent Index, up +9 points from Grok 4.6 (xhigh). Among models in their native harnesses, Grok 4.7 + Grok Build now ranks 4th, behind only Claude Fable 5.1, GPT-6 Astra, and Claude Opus 5.
➤ Incremental performance changes elsewhere: Outside of agentic knowledge work, Grok 4.7 broadly matches Grok 4.6 (high) on the other Intelligence Index tasks. It improves on Terminal-Bench 4.0 (+4.5 percentage points) and GDP.pdf (+3.0 p.p.), with regressions on AA-LCR (-3.7 p.p.) and AutomationBench-AA (-1.1 p.p.).
➤ High token use across tasks: Grok 4.7's gains come with higher token usage. Grok 4.7 (xhigh) uses approximately 81k output tokens per Intelligence Index task, compared with 36k for Grok 4.6 (high) and 27k for GPT-6 Astra (max) - 125% and 196% more, respectively.
Other model details:
➤ Context window of 500k tokens, unchanged from Grok 4.6
➤ Pricing of $2/$6 per 1M input/output tokens with cache hits discounted to $0.50 per 1M tokens, matching Grok 4.6
➤ Configurable reasoning effort spans low to xhigh. Our evaluation uses xhigh.
I resigned from Anthropic today. I spent the last three years doing pretraining research at both OpenAI and Anthropic. Neither company is acting responsibly. They are racing straight to self-improving superintelligence and gambling with our lives. More thoughts below.
Introducing TimesFM-3, a state-of-the-art time series foundation model that enables accurate multivariate time series forecasting in a single forward pass, significantly outperforming other forecasting models across major benchmarks.
More on the blog →https://t.co/uSlnIdUJ4Q
@aeljaouari@WordPress I did create a db'less system working efficiently.
Articles with a structured format as like json or MD and the system that only responsible for rendering. Thats all. And chaning an article or page spends e few sec without any error.
@ericzakariasson@cursor_ai Grok 4.6 handles execution really well and the self-checks catch a lot before I see it. Missing piece: a model suspicious enough to trace deep dependency chains and flag edge-case bugs before anything runs. Static paranoia, basically.
@BrianRoemmele I tried, and this is quite good.
However, there are some nuances you suppose to take into account:
1. The methodology ingores culture.
2. The AI model might change everything. For example Grok 4.5 is too confident while Sonnet 5 is suspicious.
3. Consider relatively.
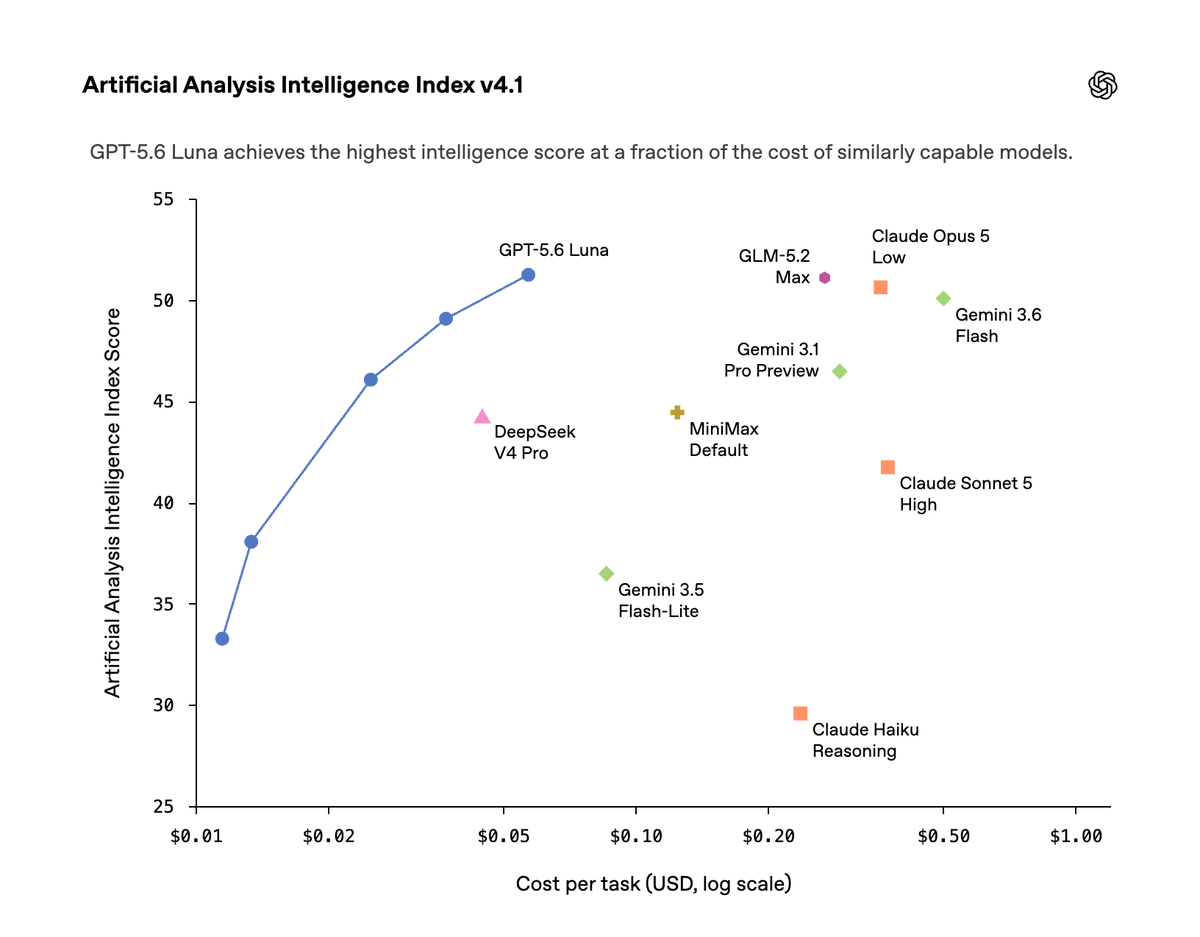
major price cuts today:
*80% drop for GPT-5.6 Luna, now $0.20 per million input tokens and $1.20 per million output
*20% drop for GPT-5.6 Terra, to $2/$12
*GPT-5.6 Sol gets Fast mode in the API, up to 2.5x the speed for 2x the price, same intelligence
Everyone is writing about agent loops right now. Including us at Cursor, because they're so powerful. But here's a prediction: a year from now, nobody will be talking about them.
Not because they weren't useful. Because they'll work right out of the box. Batteries included. No instructions necessary.
Feels a lot like prompt engineering two years ago. It was incredibly important. People wrote courses on it. Now you just talk to your agent like a normal person.
That's the strange thing about AI right now. You learn something critical, get huge gains, and before long it's the new normal and something else is the bottleneck. So the alpha isn't what you know. It's how fast you learn it, and how easily you can let it go.
@teKa088 There are many ways to build secured gateways for mcp servers. Or we can just use service accounts to do that easily. And large companies use those methods for years. So this is not true. I think it built just for individuals that use Claude for keeping them only in there.