Today, we're releasing our open-weight, auto-routing model @daridotdev, built for coding agents.
We're state-of-the-art on the Pareto Frontier, w/ 70% cost reduction + comparable coding performance to Fable.
Bring your own evals, choose your models, or use our defaults.
Introducing Rollup.
Your app never has to ask a new user who they are again. Their camera roll already knows, and your app should too.
Rollup is the first SDK that turns years of photos into user context, opt-in and fully on-device.
Add to your app👇
https://t.co/g2tBV8ZaSH
For $20/mo, get unlimited auto-routing - we save you 50% on cost / limits with little to no quality drop.
Unlike other routers, we pick models + thinking level, to help reduce cache busts.
To see how we trained our router, read our blog:
https://t.co/qshkC126cr
They spent millions on router dot com.
We spent $20 on https://t.co/dgHRbe0jEh.
We saved money on the domain to save you money on tokens.
> Pool Claude + Codex subs
> Pick the right model + thinking level w/ our SOTA router
> Use your traces to fix token waste
> Open-source
For small teams, subs are the best way to save on tokens.
Route based on how much usage is left, cache warmth + automatically claim resets.
Run subscription pooling fully locally, or use free hosted to get detailed analytics across your team.
https://t.co/l1bEyNLvK6
Are OpenAI models not the same on sub / API?
Ran GPT-6 Luna (high) on DeepSWE 1.1 in Codex:
> With subscription: 26% solved
> With API (via Vercel AI Gateway): 41% solved
Thought it might be variance, but the sign-in run also used ~4x fewer reasoning tokens per task
@illgtubeerbaron ran one mid-run request from each of 30 different tasks (8x each) + 80 full runs in openai's own codex cli. sub thought less on 24 of 30 single-req and 2-5x less on every full codex task
we’ve spent some time building evals for codebases (https://t.co/sOQLzEND0W), and imo there’s a need for both.
1) ablating your codebase with artifacts (agents.md, skills, etc) to answer the q of whether an artifact improves cost/dollar, which i could consider observability.
2) actual evals where you benchmark your PRs (what % of PRs in your codebase can an agent complete).
- public evals are rarely predictive in your codebase (ie Kimi K3 is almost never worth it to run, as it’s less performant + more expensive on a per task basis than the frontier. new deepseek flash model is, though).
- you can also benchmark things like agent teams (is the benefit of delegation worth the overhead of agent comms? this may depend on your codebase, as agent comms are a lot of output tokens, while in a contiguous session cache writes are almost all your cost.
- if a representative internal benchmark from your PRs/tickets is saturated, it may mean that the “unit of work” that engineers are producting can be more ambitious.
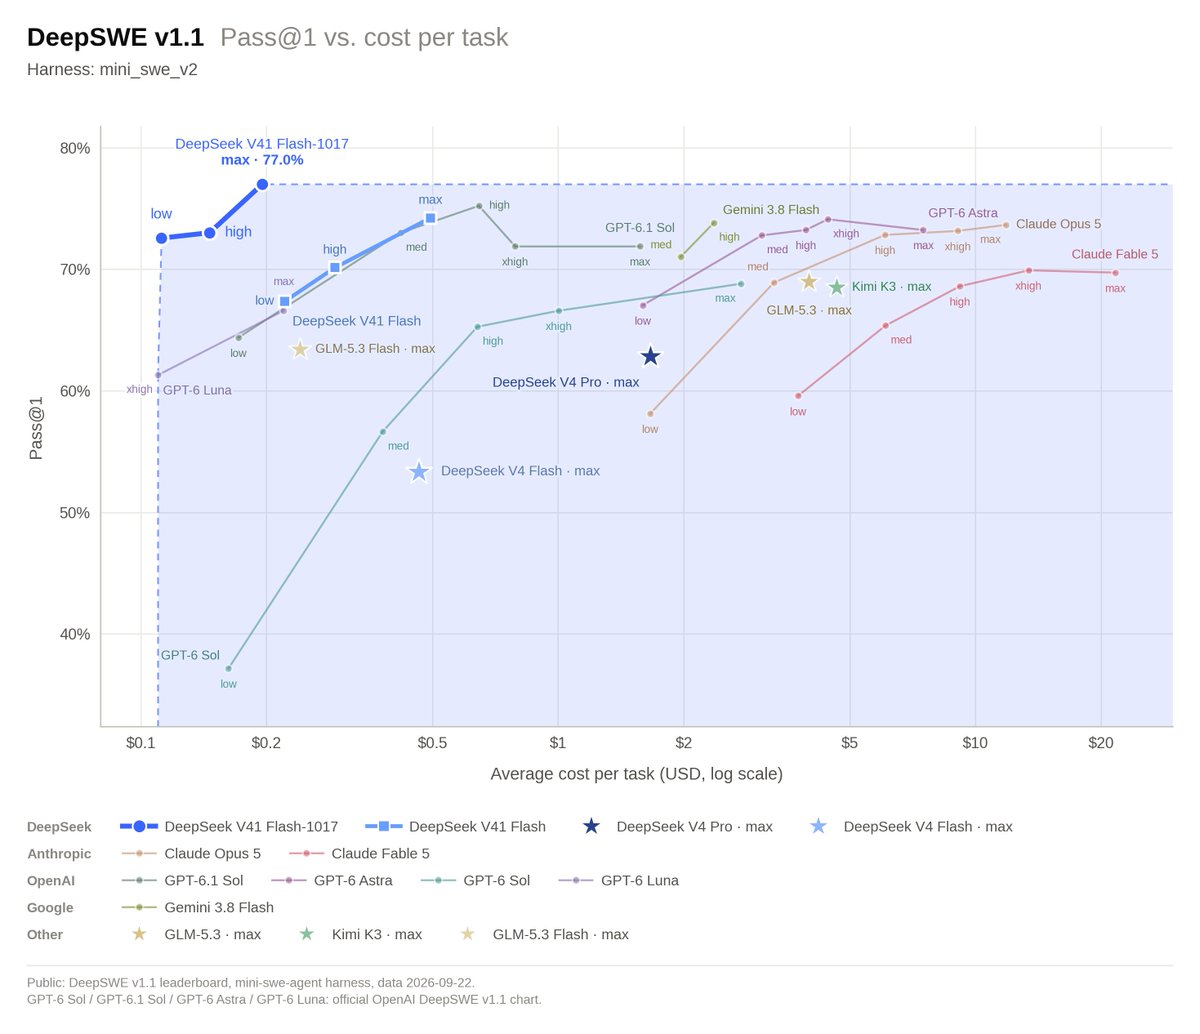
DeepSeek-V4.1-Flash-1017 is Pareto-mogging in our initial tests.
It's the first open-source model we've tested that's consistently on the Pareto frontier in real-world PRs, running in @pidotdev
Some results from Sentry, PostHog, and Next.js PRs:
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4
@bbstats@pidotdev we've only run these on opus 5.5 - it's basically always the most capable model (on pareto frontier in the Posthog bench in the video).
however, it's always more expensive than Sol 6.1, so sometimes isn't on the pareto curve.
you can click through on https://t.co/VhcZR2zsyq
Haiku 5.5 is an incredibly capable model at its size.
We ran Haiku on real Pi, Next.js, PostHog, and Sentry tasks, and it was on the Pareto frontier in every test.
Slightly higher $/task than Luna for increased performance.
Towards intelligence too cheap to meter!
Open-weight models may be costing you more on real work.
We built self-bench to turn real GitHub PRs into evals.
Testing repos like Next.js, PostHog, and Sentry, open models were usually pricier + less capable.
Find the best model for your repo: https://t.co/VhcZR2zsyq