Also built in: adaptive concurrency that halves on 429s, quota exhaustion pauses the job instead of failing it, and content hashing skips unchanged pages on re-runs.
How are others isolating tenants on shared LLM pipelines?
Generating one AI output per page across tens of thousands of pages, for many tenants at once, is a distributed-systems problem, not an AI problem.
Here's how we designed it on AWS: SQS fair queues, leases, fencing tokens, and a supervisor that schedules itself.
We assume at-least-once delivery and design for it. Every state change is a compare-and-set against a lease holder, fencing token, or epoch.
Duplicate and stale messages are no-ops. A supervisor that schedules itself reclaims expired leases and finishes the job.
We put @Meta Muse Voice Transcribe into production 48 hours after launch.
@interact_ai runs a realtime voice agent on LiveKit, where the STT property that governs everything is whether the model knows when to keep listening.
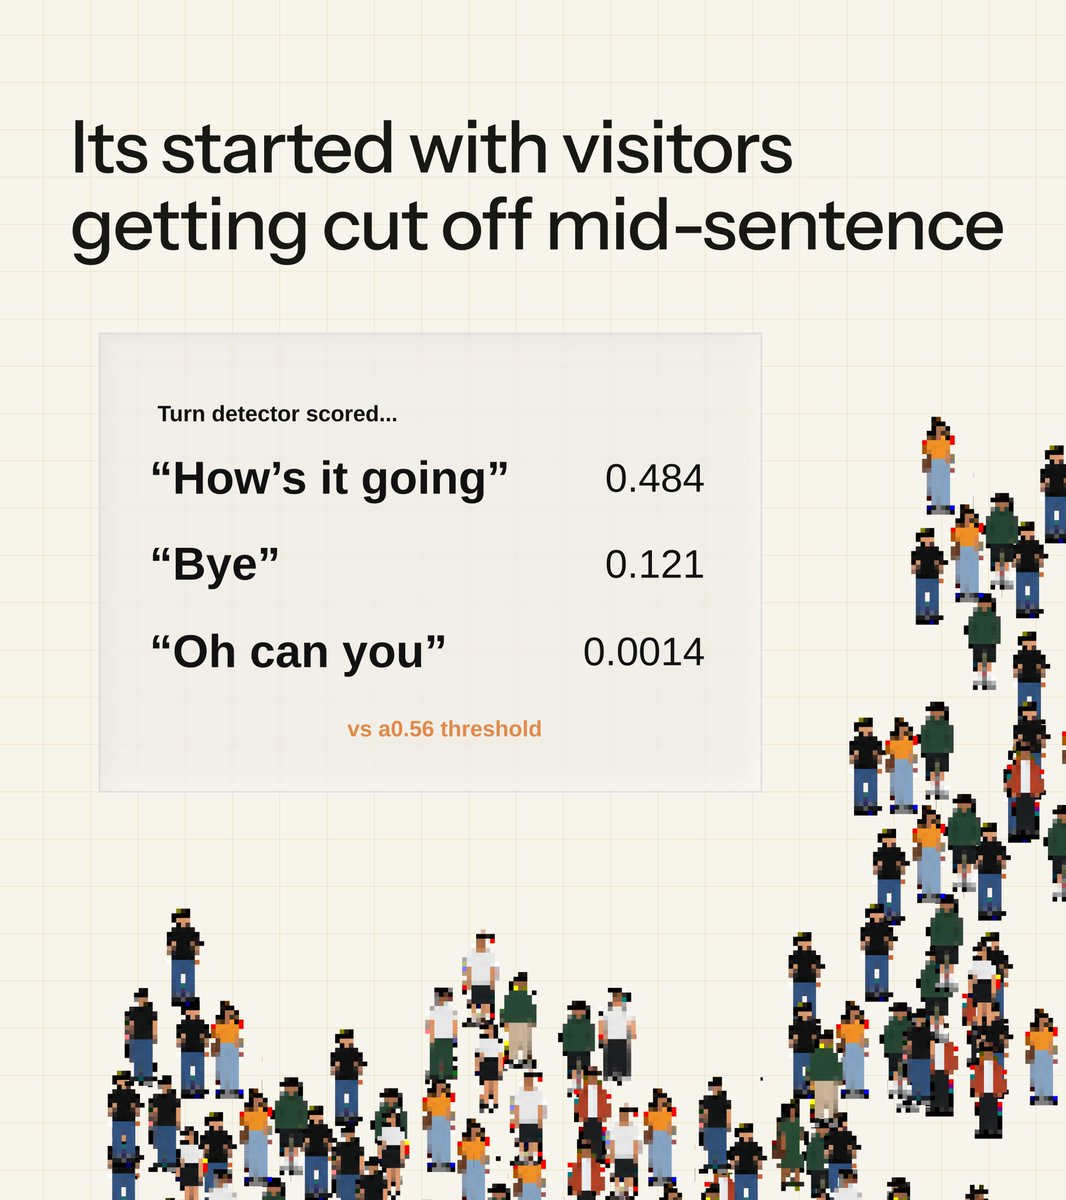
For weeks, visitors had been getting cut off mid-sentence. We traced it to the handoff between our STT and our turn detector. The detector scores every turn for completeness against a 0.56 threshold, and it was doing its job fine.
AssemblyAI finalised mid-utterance, often twice per turn, so complete sentences kept reaching the detector as fragments.
"How's it going?" scored 0.484.
"Bye." scored 0.121.
"Oh. Can you?" scored 0.0014.
Nothing looked finished, so the agent kept committing early and interrupting. Two finals per turn also meant duplicate chat bubbles.
Muse handles streaming ASR and endpointing in the same model. Every 80ms chunk emits either a word or a keep-listening token, and a final arrives only once the turn is over, post-processed and whole.
Artificial Analysis's streaming snapshot has Muse at 3.06% WER against AssemblyAI's 4.02%, first partial at 127ms against 185ms, and $3.00 per 1,000 audio minutes against $7.50.
Those numbers made the decision easy for us, but they measure a metric next to our problem. The architecture of Muse itself fixed the problem.
Going to prod this early meant no LiveKit plugin existed, so we wrote one. (repo in comments)
One trap for whoever integrates next: Muse sends speechEnd before speechComplete, and LiveKit commits the turn on END_OF_SPEECH with whatever text has landed by then. Hold the boundary until the final arrives.
With whole finals guaranteed upstream, we retuned the timing:
commit floor 0.55s → 1.2s
VAD hangover 0.55 → 0.75s
deactivation 0.35 → 0.25.
We fixed "the agent keeps interrupting me" by making the agent wait twice as long. That only works because the endpoint now arrives declared instead of guessed.
@interactaidev@SuyashKarn2@ani1005sai
Introducing Interact AI: a new interface for the web.
Add it to your website, and it talks to every visitor, answers questions, and shows your product.
Try it now -> https://t.co/qdfaFGI9a9