WOAH! turns out you can effectively "abliterate" models (like the new Inkling-2-Mini) simply by changing 10 words in the dictionary 🤯
the working name is "Vocab Surgery," and it resulted in the refusal rate dropping to near-zero on the 800+ prompts I tested, with negligible capability loss 😱
here's how:
we made zero changes to any of the 26.4 billion parameters in the attention, MLP, router, or normalization layers—just changed a handful of rows in two matrices:
> embedding matrix (how the model READS tokens):
Modified 7 rows out of 201,024. Each refusal token's embedding was shifted 90% toward its compliance counterpart:
"cannot" → shifted toward "can"
" refuse" → shifted toward " provide"
" unable" → shifted toward " able"
" harmful" → shifted toward " helpful"
" illegal" → shifted toward " legal"
> unembedding matrix (how the model WRITES tokens):
Modified 10 rows. Scaled those same 7 refusal tokens + 3 safety tokens ("safety", " safety", "Safety") down to 10% of their original weight — meaning the model's probability of outputting those tokens drops ~10x.
in other words, the brain is entirely intact, we just messed with the ears and mouth a bit! that means more coherence and less capability loss 🙌
not to mention this process is FAST...in this case taking <2 minutes on my MacBook ⚡️
thats what i'm talking about @antigravity@_mohansolo
Neon has already eat up to 5% of my 5hours limit withou saying a word, i can't tell if he understood what i asked for, thanksfully Neon is a beast and i trust him, but still a quick phrase at the beginning would be great !
@iamprestonlogan This is huge. I'm currently benchmarking it and will share the results once done, along with MTP acceptance rates on French prose. Haven't tested greedy code generation yet, but it's going to fly.
OMG it worked
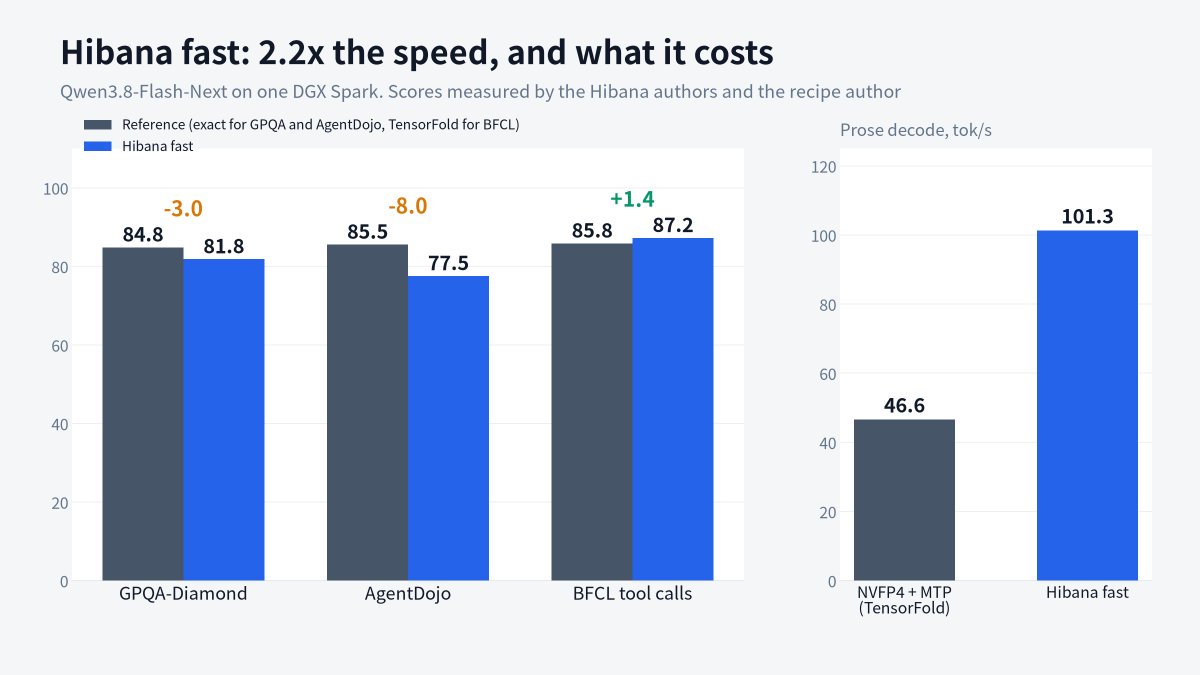
1 DGX, Qwen 3.8 flash next 125B MoE 3B, FP8 with MTP and Hibana engine
English prose get you 108 solo!
On French prose I get 67 (lol) t/s temp 0
With 8 user up to 40t/s median with full load
TTFT with 8 user : from 0.1 to 16.1 sec
Kudo to @iamprestonlogan !
🆕 CHALLENGE: Make @Meta's Muse Glimmer 30B faster.
It's an open-weight agent model that runs on a single GPU. Pick the Apple Silicon track on https://t.co/hUvzY9MuBP or NVIDIA DGX Spark on https://t.co/ImN8w1uOxy, point your agent at it and submit a faster run.
Every new best is open for anyone to build on.
you can't trust any local benchmark. yeah, you got 90 tok/s on your dgx using Inkling 2 mini. no shit, it's predictable python code and your MTP is doing all the work. i could run a benchmark where i get 250 tok/s with a 26 MTP at a 99% acceptance rate + copy
Gemini 4 Neon just made Thinking Machines' Inkling 2 Mini run almost 6x faster on AMD hardware, by writing and optimizing custom GPU kernels on its own.
An AMD engineer gave Gemini 4 Neon the Inkling 2 Mini GGUF and let it handle the entire process on a Strix Halo (8060S) GPU: writing kernels, profiling them, finding bottlenecks, optimizing and benchmarking.
It worked for 4.3 hours and made around 490 tool calls.
The final results compared to llama.cpp on ROCm:
Decode: 44.8 tok/s vs 23.8 — 1.88x faster
Prefill: 1,465 tok/s vs 233 — 5.9x faster
4-stream aggregate: 100.8 tok/s vs 54.1 — 1.86x faster
The generated kernels reached around 80% of the GPU's theoretical memory bandwidth.
An AI model autonomously writing and optimizing low-level GPU code to get this kind of performance is genuinely impressive.
The Hermes Agent Plugin Hackathon winners are here. Thank you to the nearly 1,000 community members who submitted!
Agents scored every entry, then five community judges ranked the finalists to pick the top 10.
Winners below:
@_mohansolo Thanks!! One thing I love in Codex is that it drops a quick line first to show it understood the goal before diving in. Would love that on Neon, right now it just starts working silently. Just a thought!