I'm glad to share that ORIGEN has been accepted to #NeurIPS2025! ORIGEN is the first zero-shot method for 3D orientation grounding in T2I generation. Collaborated with @myh4832, @KyeongminYeo, @jyun_leee, @MinhyukSung.
Web: https://t.co/QTWRYOC29B
See you in San Diego! ✈️
1/
Can Video World Models Track Unobserved World States?
Video world models increasingly look like simulators. But rendering plausible video is not the same as knowing what the world is doing.
We test this with a video shell game. A ball hides under one of five identical cups, which are swapped N times out of sight. Every frame is easy to render. The hidden arrangement is not.
A standard causal DiT trained on five swaps still renders ten swaps at 40.4 dB PSNR, but lifts the wrong cup. LaCT (TTT-KVB w. SwiGLU) tracks the correct final state with similar visual quality.
Steering diffusion models toward a reward is slow. 🐢
CDM makes it up to 50× faster, with less than 5% compute overhead.
⚡Check out the demo and code (protein & language) below. 👇
📄 https://t.co/6650sywxgP
💻 https://t.co/9iBXyWcHnq
Retrieval Heads Meet Vision: Uncovering How VLMs Locate and Extract Visual Information
TL;DR: VLMs rely on a surprisingly small set of Visual Retrieval Heads to locate task-relevant image regions. Masking these heads severely hurts grounding and VQA, while their roles transfer across tasks and models sharing the same LLM backbone.
https://t.co/xpdzyATZD0
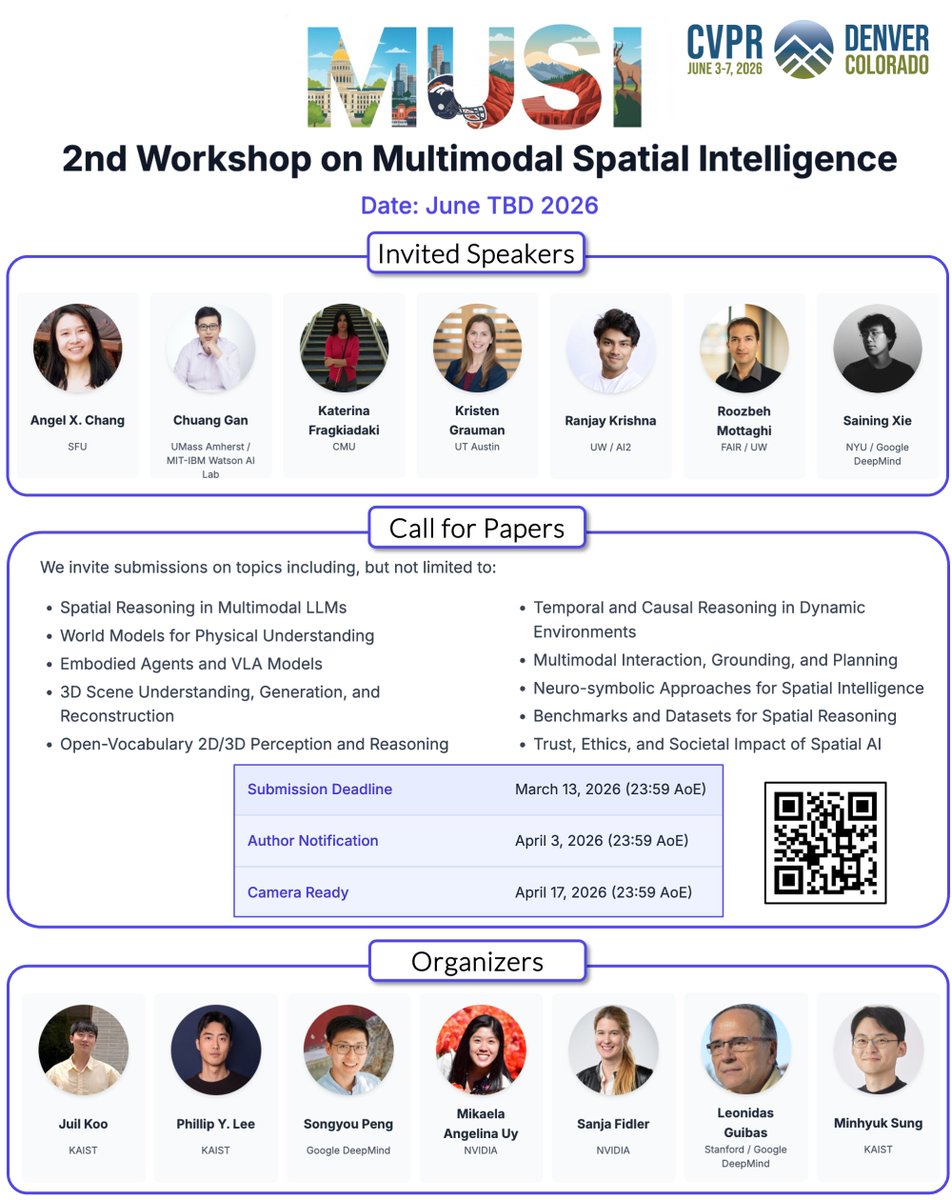
#CVPR2026@cvpr If you're interested in the intersection of multimodal and spatial intelligence, join our ✨MUSI workshop✨ on June 3 (Wed)!
We’re bringing together an amazing lineup of speakers to discuss the latest and most exciting topics in multimodal spatial intelligence🧠
#ICLR2026 🇧🇷
Excited to present two papers from our group: BézierFlow & PairFlow, cutting diffusion training/fine-tuning from days to minutes.
𝗕é𝘇𝗶𝗲𝗿𝗙𝗹𝗼𝘄: https://t.co/7Iifiw7b19
𝗣𝗮𝗶𝗿𝗙𝗹𝗼𝘄: https://t.co/JQmpSN10m5
📢 MUSI Workshop @CVPR 2026 — Call for Papers! 🚀
2nd Workshop on Multimodal Spatial Intelligence (MUSI): spatial reasoning 🧠, 3D/world modeling 🌏, embodied AI🤖 & more ✨.
📝 Submit your work & join us! 🙌
🔗 Website: https://t.co/gJqFfvWGEX
#CVPR2026#MUSI
Introducing "Toward Ambulatory Vision: Learning Visually-Grounded Active View Selection"
🤖 VLMs answer well—but only if the evidence is already visible. How can we bring this capability to real agent scenarios, where the current view is insufficient to answer directly?
📢 Our KAIST Visual AI Group is recruiting undergraduate interns for this winter!
Research topics include generative models for diverse data types (images, videos, text, biological data) and multimodal foundation models for spatial intelligence.
🌐 https://t.co/h7FdzC8Hmt
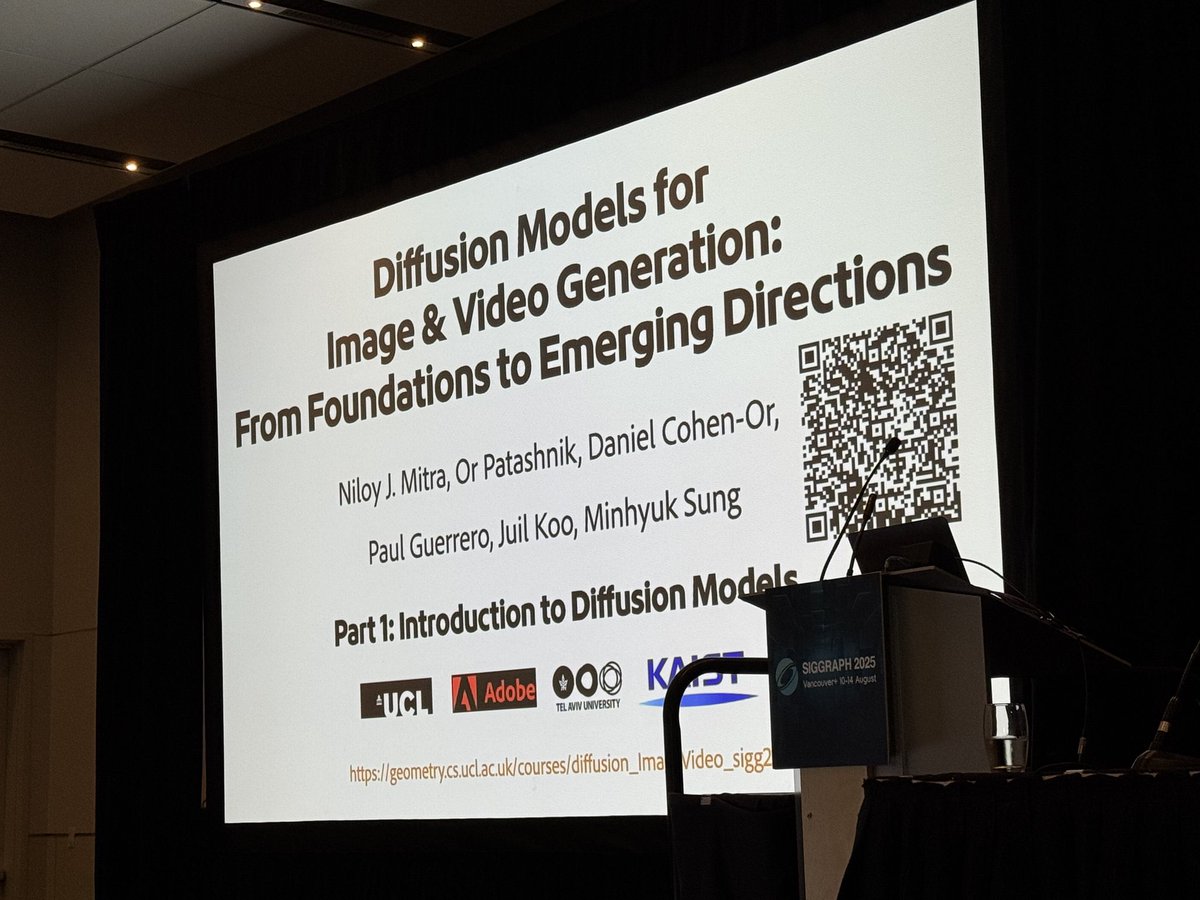
Great summary of the latest image & video diffusion models! Our #SIGGRAPH2025 course spans real-world uses to techniques like acceleration & flow matching.
Slides: https://t.co/twKumFH2QY
w/ Niloy Mitra, @OPatashnik, @DanielCohenOr1 , Paul Guerrero, @MinhyukSung
Diffusion model course at SIGGRAPH 2025 is happening NOW in the West Building, Rooms 109–110.
w/ Niloy Mitra, @OPatashnik, @DanielCohenOr1, Paul Guerrero, and Juil Koo.
We present our paper
"Ψ-Sampler: Initial Particle Sampling for SMC-Based Inference-Time Reward Alignment in Score Models"
Check out more details
arXiv: https://t.co/pDSllDC79O
Website: https://t.co/PCRYxlUBiI
Term’s over, finally time to binge-watch lectures! Not just for the content, but to pick up new way to present material too. Always learning.
@MinhyukSung has an amazing set of videos of his various courses posted on YouTube (very brave 💪). Check them out!
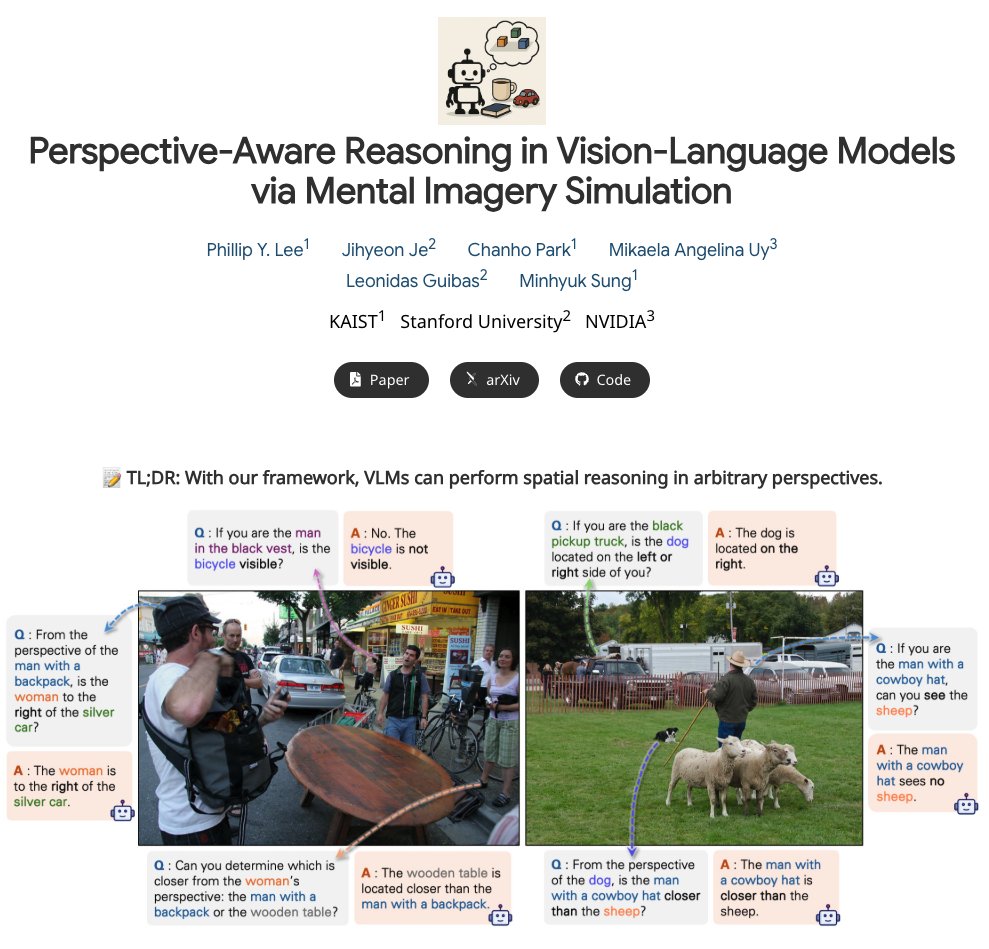
❗️Vision-Language Models (VLMs) struggle with even basic perspective changes!
✏️ In our new preprint, we aim to extend the spatial reasoning capabilities of VLMs to ⭐️arbitrary⭐️ perspectives.
📄Paper: https://t.co/qq5s8jHtVN
🔗Project: https://t.co/sh5W8VLwZO
🧵[1/N]
🎉 Join us tomorrow at the #ICLR2025 poster session to learn about our work, "StochSync," extending pretrained diffusion models to generate images in arbitrary spaces!
📌: Hall 3 + Hall 2B #103
📅: Apr. 25. 10AM-12:30PM
[1/8]
🇸🇬 Attending #ICLR2025 ?
Check out how we extend pretrained diffusion models to generate images in arbitrary spaces.
📌: Hall 3 + Hall 2B #103
📅: 10AM-12:30PM