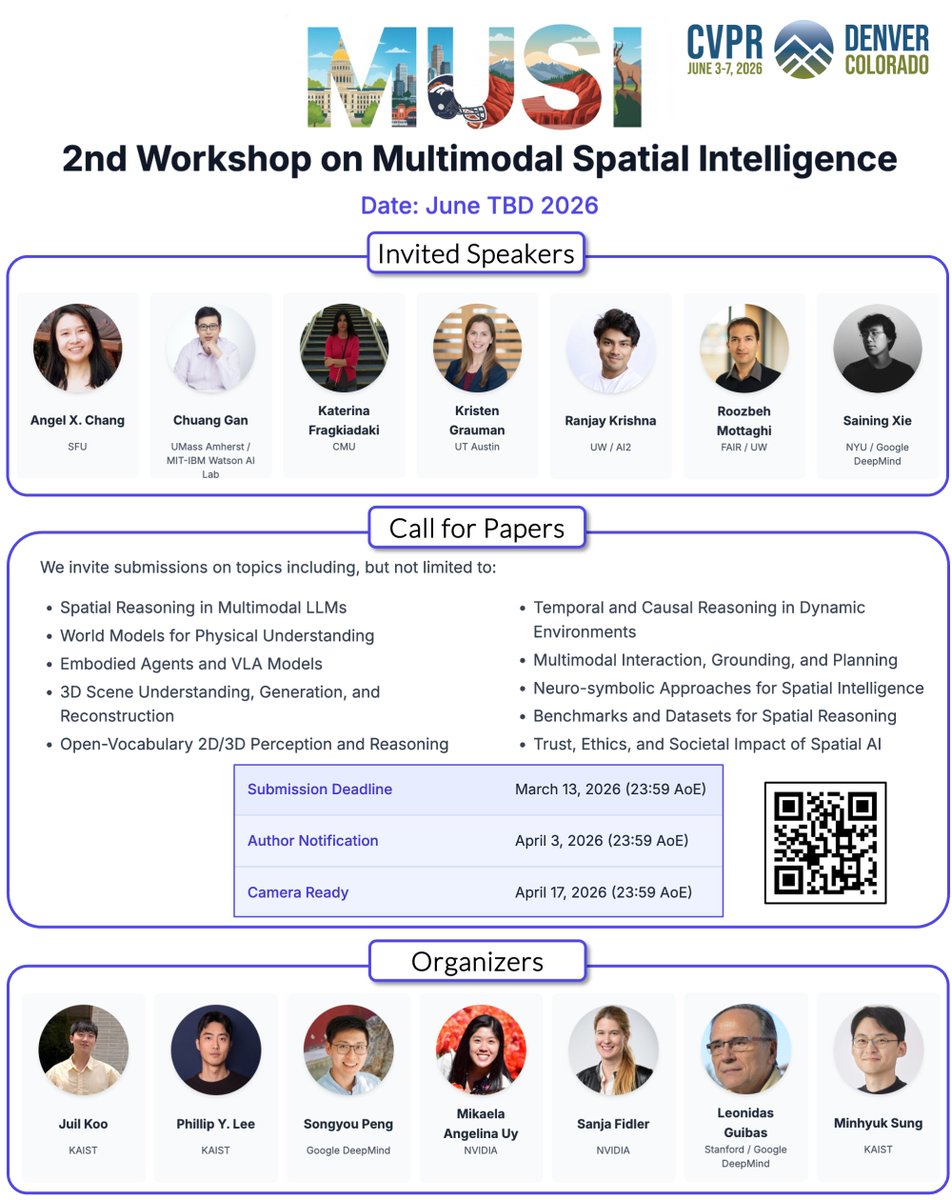
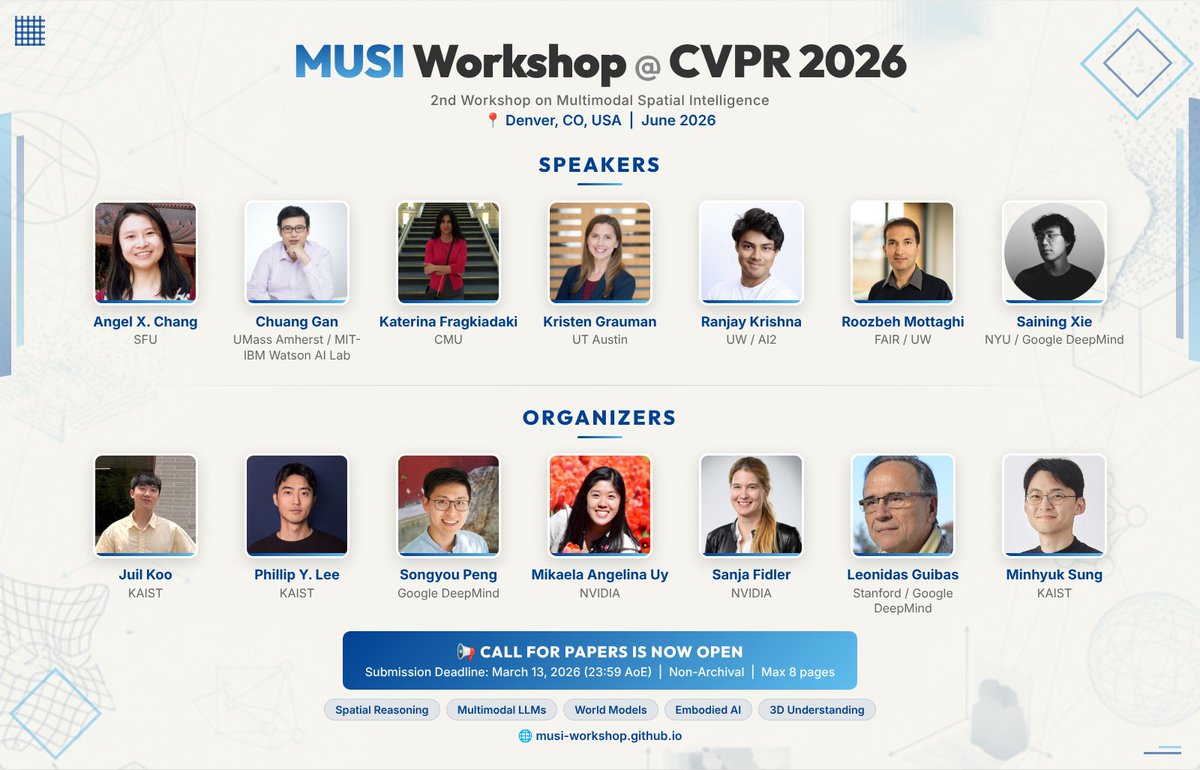
📢 MUSI Workshop @CVPR 2026 — Call for Papers! 🚀
2nd Workshop on Multimodal Spatial Intelligence (MUSI): spatial reasoning 🧠, 3D/world modeling 🌏, embodied AI🤖 & more ✨.
📝 Submit your work & join us! 🙌
🔗 Website: https://t.co/gJqFfvWGEX
#CVPR2026#MUSI
Last week, I was grateful to give a talk at Stanford on our recent work, Drifting Field Policy (DFP).
Diffusion policies are powerful, but not necessarily the best fit for RL. DFP is our one-step alternative.
Slides: https://t.co/zf1sZ7hoHm
Project: https://t.co/Xdk1FrytTZ
⏰ 3 days left! 𝗠𝗨𝗦𝗜 𝗪𝗼𝗿𝗸𝘀𝗵𝗼𝗽 @CVPR 2026
🗓️ Submission Deadline: March 13, 2026 (AoE)
Welcome both new work and previously accepted papers. 🙌
📝 Submit now! → https://t.co/eAWGSah96e
#CVPR2026#MUSI
📢 MUSI Workshop @CVPR 2026 — Call for Papers! 🚀
2nd Workshop on Multimodal Spatial Intelligence (MUSI): spatial reasoning 🧠, 3D/world modeling 🌏, embodied AI🤖 & more ✨.
📝 Submit your work & join us! 🙌
🔗 Website: https://t.co/gJqFfvWGEX
#CVPR2026#MUSI
Introducing "Toward Ambulatory Vision: Learning Visually-Grounded Active View Selection"
🤖 VLMs answer well—but only if the evidence is already visible. How can we bring this capability to real agent scenarios, where the current view is insufficient to answer directly?
[5/6]
📊 Results: strong VQA gains on unseen synthetic + real 3D scenes, even outperforming proprietary models (GPT-5, Gemini-2.5 Pro). AVS also plugs into existing EQA pipelines as a “final viewpoint refinement” step.
[4/6]
⚒️ Method: predict continuous viewpoint-adjustment actions (rotation + translation) from the current egocentric image + question, targeting the next most informative viewpoint in a single turn. (SFT → GRPO)
[3/6]
🚀 We introduce Active View Selection (AVS): bringing “active perception” to VLMs. Instead of reasoning from a single static image, the model first moves to acquire a more informative view, and then answers.
🌴Happy to attend #ICCV2025 in Hawaii!
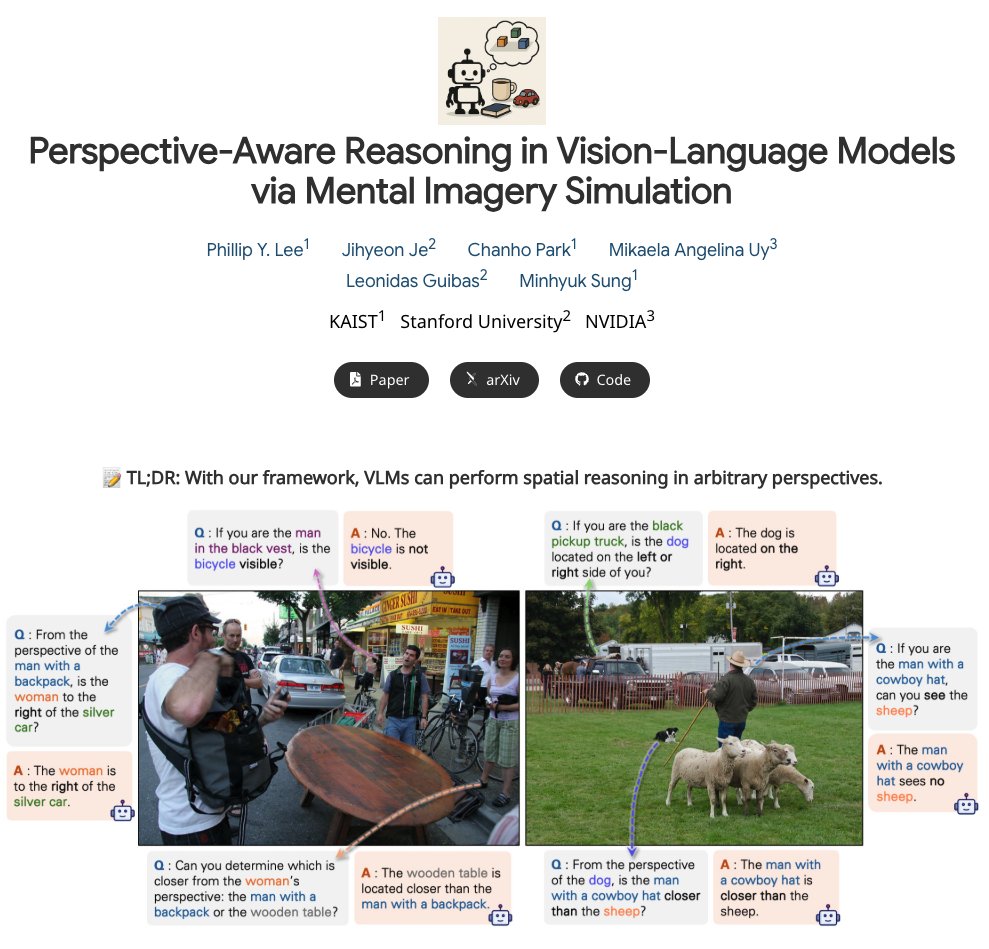
I’ll be presenting our paper on enabling VLMs to perform spatial reasoning from arbitrary perspectives.
📔 Paper: https://t.co/iX9Pt0AWEh
🖥️ Project Page: https://t.co/sh5W8VLwZO
✔️ Poster: Oct 21 (Tue) Session 2 & Exhibit Hall, #858
Great summary of the latest image & video diffusion models! Our #SIGGRAPH2025 course spans real-world uses to techniques like acceleration & flow matching.
Slides: https://t.co/twKumFH2QY
w/ Niloy Mitra, @OPatashnik, @DanielCohenOr1 , Paul Guerrero, @MinhyukSung
❗️Vision-Language Models (VLMs) struggle with even basic perspective changes!
✏️ In our new preprint, we aim to extend the spatial reasoning capabilities of VLMs to ⭐️arbitrary⭐️ perspectives.
📄Paper: https://t.co/qq5s8jHtVN
🔗Project: https://t.co/sh5W8VLwZO
🧵[1/N]
🎉 Join us tomorrow at the #ICLR2025 poster session to learn about our work, "StochSync," extending pretrained diffusion models to generate images in arbitrary spaces!
📌: Hall 3 + Hall 2B #103
📅: Apr. 25. 10AM-12:30PM
[1/8]
🔥 Grounding 3D Orientation in Text-to-Image 🔥
🎯 We present ORIGEN — the first zero-shot method for accurate 3D orientation grounding in text-to-image generation!
📄 Paper: https://t.co/x20WdG96Hs
🌐 Project: https://t.co/fE7ozSbf46
🔎 Unconditional priors matter!
When fine-tuning diffusion models for conditional tasks, the **unconditional** distribution often breaks down.
🔑 We propose a simple fix: simply mix the predicted noise from the **fine-tuned** model and its **base** model!