Please welcome GPT-6 Sol and GPT-6 Luna to the GPT-6 universe.
GPT-6 Sol and Luna build on the advances behind GPT-6 Astra, bringing much of its strengths into faster and more affordable models to support work at scale.
We’ve also made caching and inference more efficient, and we’re passing the savings directly to you: 50% lower API prices for Sol and Luna compared with GPT‑5.6 promotional pricing.
After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI?
I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev
• 20-200x faster
• 40-400x cheaper (w/ output tokens free)
• Frontier composable intelligence optimized for decisions
AFAICT the shortest path to AI-based economic revolution
We will give one banked reset for every day you don't have access to Astra on your paid ChatGPT plan, starting today. Team is moving mountains to give access as fast as we can.
First one will land in ~ 3 hours. There is still time to create your account if you don't have one.
TIME has done it again, bravo, incredible.
Apparently Paris Hilton is one of the world's most influential people in AI, but Demis Hassabis, Jensen Huang, Andrej Karpathy, Alex Wang, Liang Wenfeng are not? lmao
Introducing Bot Mode for Hermes Desktop.
Your agent profiles become a series of named Bots. Each Bot has its own role, model, memory, skills and profile picture; Bots can use any model and even communicate with each other.
Build a specialist Bot once to use it forever.
DeepSeek has officially increased their prices
OpenCode Go's limits have been updated to reflect them
We have made progress on operation cheepseek, more info soon
if you've been using latest frontier LLMs, it's almost certain that you would have noticed by now the newer models have become worse to talk to
they're more robotic, they speak jargons, they spits out verbose text, and do stuff you didn't ask for
how did that happen? well, i'm not the person who trained those models so i can't speak for certain, but i've known enough evidence that gives me a well-educated guess, and i thought it's interesting to share as a crash course of modern LLM training pipelines
so here we go
let's wind back to 2020. GPT-2 and GPT-3 already came out and were widely available, but they could only predict one token at a time - that's what LLMs are at their core
token prediction was offered via API, but there was nothing you could "talk to". so while it generated a lot of excitement in the academic field due to the emergent intelligence, it didn't have any wide adoption
in 2022, ChatGPT changed all that. the research work that led to ChatGPT was a model initially named "InstructGPT". it took GPT-3 as the intelligent base, and used reinforcement learning with human feedback (RLHF) to teach the models how to "chat"
the core idea of RLHF is that you ask the model to generate a few responses, and then let real humans pick which one they like. do this over and over again, and you get a model that knows how to talk
worth noting even as early as InstructGPT, research found that making the model more pleasant to talk to will reduce their pure academic capabilities. this was called "alignment tax", which is an interesting thing we'll come back to in a bit
there were various techniques done to minimize the reliance on humans, but ultimately the reward is modeled after human preference, making these AI assistants easy to talk to
so remember this: RLHF = training the model to be likable by humans
in 2024, there was an inflection point introduced by claude sonnet 3.5 which was the first model that can kind of autonomously finish coding tasks. it led to the first wave of viable "coding agents"
the way sonnet 3.5 achieved this was by training the model with a harness (now it's called an agent) that has bash and file editing tools, throw the agent into a virtual machine, give it a task, and let it try to complete it. these tasks all have a machine-verifiable outcome predefined, mostly via test cases, that can validate whether the model really finished the task or not
then you let the model do billions and billions of attempts in such virtual environments, and some of them would succeed by chance. you keep the successful agent sessions, and use reinforcement learning to teach the model to do that more, and boom - you get a coding agent
that is called reinforcement learning with verifiable rewards (RLVR). if you look closely, you'll see that in this RLVR process, the final text response from the model doesn't matter AT ALL, as long as the code written by the agent could pass the test. it could talk like a jerk and it would still be rewarded
so remember this: RLVR = training the model to be accepted by machines
late 2024 and early 2025, we saw o1 and deepseek R1 came out as the first wave of "reasoning models". this article is getting long so i'm not diving into reasoning models now, but just know that reasoning models also relied heavily on RLVR to scale the training process - let the model think before taking action, and if the thinking led to a machine verifiable outcome, reward the thinking trace and teach the model to think like that more often
the biggest difference between RLVR and RLHF is that RLVR is more scalable. human feedback is expensive to get, especially in domains where only an expert can have a valid opinion on which result is good
with RLHF, if we let the model generate 100 responses, then a human has to review all 100 responses to pick which is good
with RLVR, the human (or sometimes an AI) would define a task and verifier only once, and the model can generate a million responses - the machine verifier will pick which responses are good in an automated way
so as a result, RLVR is becoming more and more dominant in newer models' training pipeline
if you put all these things together:
- RLHF = training the model to be likable by humans
- RLVR = training the model to be accepted by machines
- RLVR is more scalable
- "alignment tax" says "likable by humans" makes the model do worse on verifiable tasks
now you see why the newer models are becoming less and less likable?
this is not just a "frontier labs screwed up their model training" problem - this is a war between machines and humanity, and humanity is losing
we chased after benchmarks, when none of the benchmarks measure whether humans actually enjoy working with the model
we use machines to decide which AI response is better because that's easier and cheaper, when we have no way of making sure those machines actually represent what we humans want
we let AI go dark in a virtual environment on its own and complete predefined tasks at all costs, when in reality we often cannot define a verifiable outcome upfront, and need AI to work with us along the way
i don't have a good solution to this, but i want to call for awareness that we're starting to witness a failure in aligning super intelligence right in front of our eyes
this war between machines vs humanity is one we really can't afford to lose
We're starting to leave the territory where you'd test an LLM by e.g. "create an svg of pelican on a bicycle". As one idea to generalize it, I was interested what Opus 5 would do if I gave it the first paragraph of the Lord of the Rings, a 1M token budget (~$10) and asked for three js render of it. Opus went off for ~2 hours and wrote 5500 lines of code that (procedurally) rendered the story. It's kind of janky but fun. But it's a bit mindboggling that the LLM has to place and orchestrate various polygon assets in (x,y,z) coordinates and write code that animates it all, and that it even does anything at all.
I also like this kind of examples because no one in their right mind would ever spend the time to write something this custom but LLMs have all the stamina and patience in the world, so it's an example where we go from "no one would ever do this" to "sure, why not, it's ~free". There might be a lot more. But I'm excited about creating hyper custom worlds that you can imagine dropping players into, e.g. here to participate in the LoTR story as a spectator NPC, or one of the characters, or etc. Something like an ephemeral GTA of X on demand.
Last thought is that the domain of worlds/games exposes a weakness in LLMs: they can't easily audit their work because they aren't able to efficiently and natively perceive videos or play games within them. Here, Opus 5 had to very slowly and painstakingly take screenshots at different points, and it messed up a few times and created a bunch of jank. An example of raw capability (multimodal, gameplay) that I think is still quite lacking.
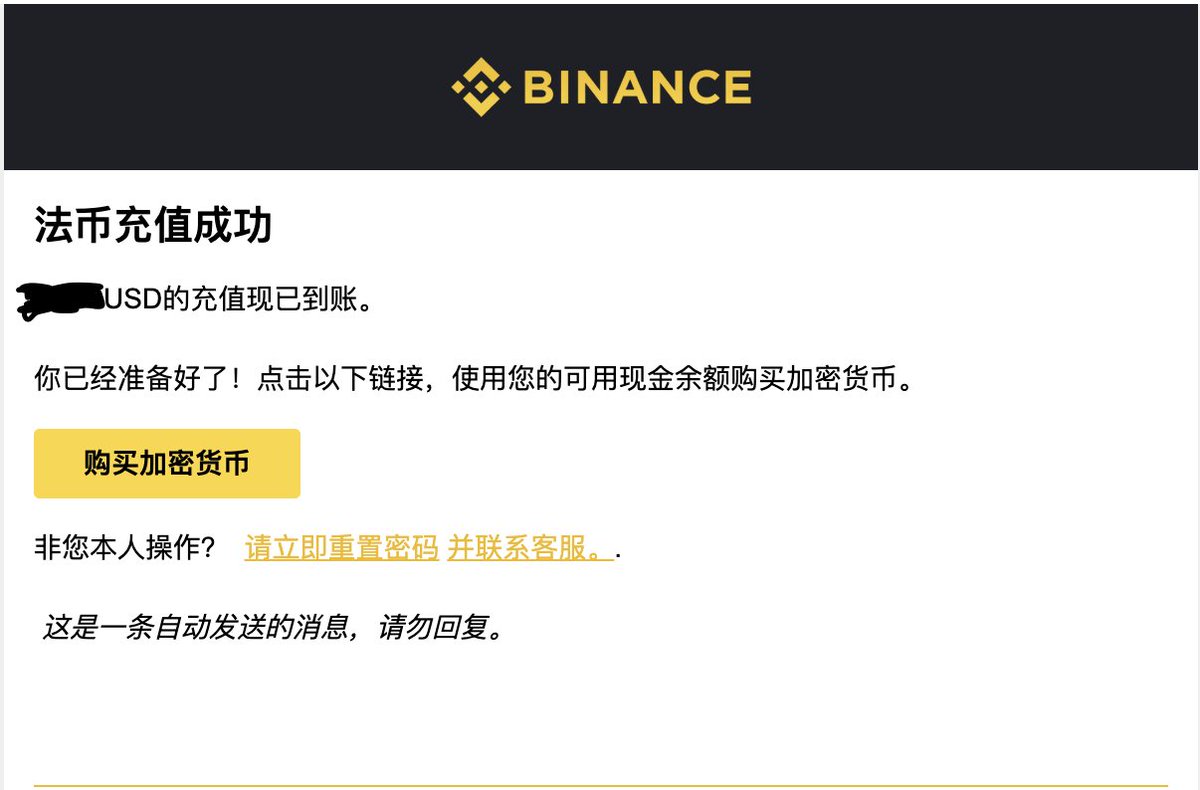
一部安卓手机,下好 Google Play 商店,里面账户设置里绑定银行卡(也就是你 Fiat 24的卡,信息在Bitget钱包里都有),这一步做完相当于你已经绑定好 Google Pay了。然后随便点开一家交易所选择法币入金,都会有 Google Pay 的支付选项~
iPhone 没实操过不了解,不过能绑定上 Apple Pay 的话那操作应该是一样的
我觉得我发的这个应该是最简单的方法了,就是磨损有点大🤔