Ada v4.1.0 is out!
The WHATWG URL parser inside Node.js just got a lot faster:
- can_parse: up to 4.2x faster
- parsing real-world URLs: 1.7-2.4x faster
- URL setters: 1.7x faster on average
- URLSearchParams: 1.9x faster
https://t.co/TqHKKEybrM
Oh boy … PHP sent clear text data when you used uppercased S in httpS:// in a protocol handler 🙈🙈
file_get_contents('HTTPS://…') skipped TLS: tokens, POST bodies and FTPS logins went out unencrypted!
Fixed today in 8.2.36, 8.3.37, 8.4.28, 8.5.13 & 8.6.0.
We teamed up with @Baseten to make Patterns, our LLM topic-clustering feature, ~50x faster.
Fine-tuned Qwen 3.5 9B on production traces:
⚡ 44.7s → 0.89s
✅ 45% → 93% judge pass rate
Your coding agent can run the workflow too.
Try it: https://t.co/QebE4pZZ4i
Read all about it: https://t.co/yJpi8O0XZ4
@datadoghq@kaixin_tai
GTA VI on PC.
Been working on the PS5 recompilation pipeline.
Testing the 14.23FW trgt , package analysis and decryption workflow are progressing. GTA VI now reaches the first menu in my experimental PC build.
Still crashing when transitioning into gameplay.
WIP. #GTA6#GTAVI
We just made LLM inference up to 30% faster ⚡
Introducing DNeo, a new diffusion drafter designed in collaboration with @cerebras researchers.
The secret? Your draft model needs a working memory, and the "right" context encoding mechanism.
📄 Paper: https://t.co/Pj1qpeqpO9
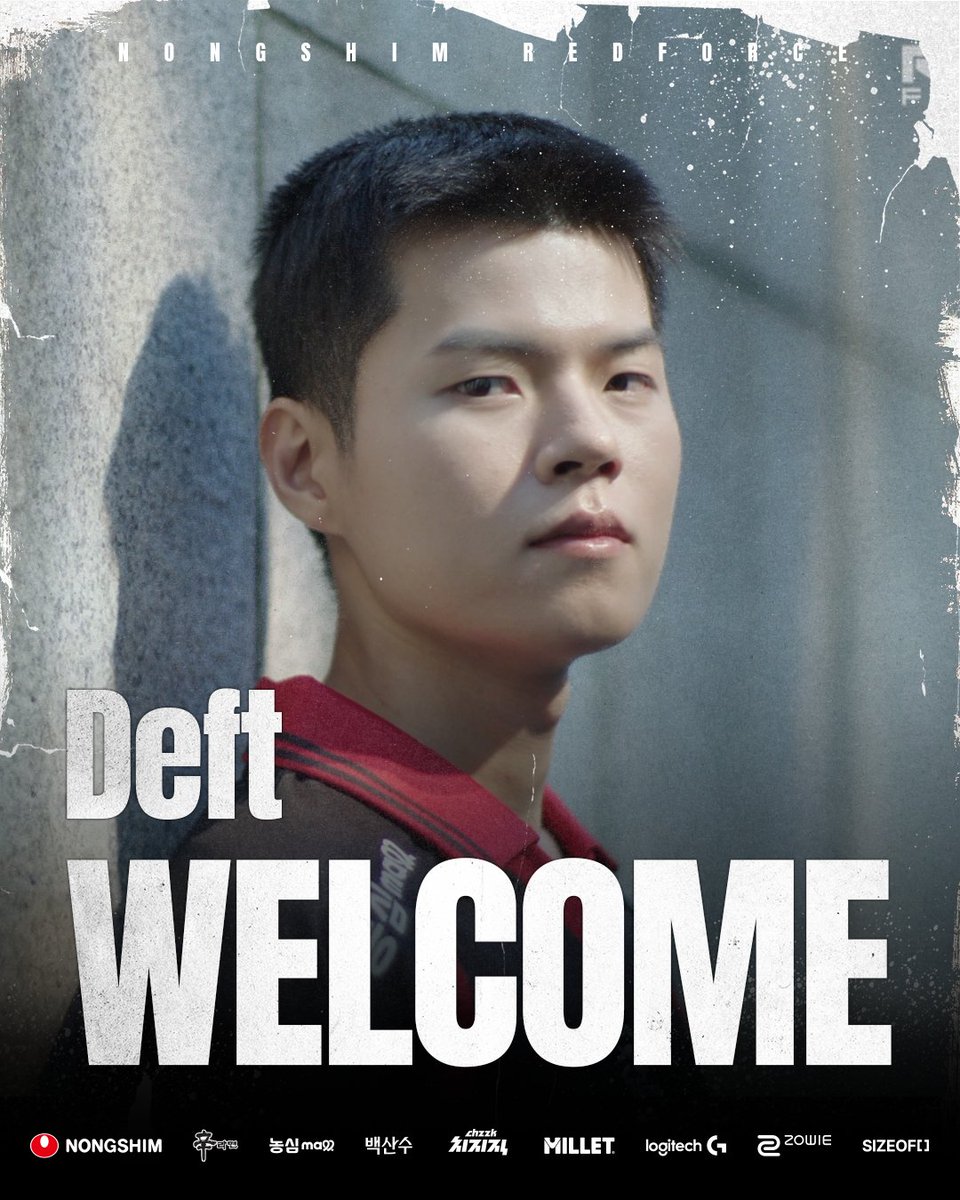
[OFFICIAL ANNOUNCEMENT] #LCK
'Deft' has signed a contract as the new ADC of NS RedForce LCK Team.
Please look forward to and support Deft, who has written new history with an unbreakable spirit through countless trials, as he takes on new challenges and delivers great performances once again on the LCK stage.
농심 레드포스 LCK 팀에 원거리 딜러 'Deft' 김혁규 선수가 합류합니다.
수많은 도전 속에서도 꺾이지 않는 마음으로 새로운 역사를 써 내려온 'Deft' 선수가 다시 LCK 무대에서 펼쳐갈 도전과 활약에 많은 기대와 응원 부탁드립니다.
#NONGSHIM #NSRedForce #농심레드포스 #Deft
So now a small 300MB adapter makes your local 27B coding model dramatically better!
Hugging Face released an RL-trained LoRA adapter for Qwen3.8-27B, specifically optimized for OpenCode.
And the reported results are impressive!
SWE-bench Pro (hard 51 tasks):
🔴 Original → 35.3%
🟢 With LoRA → 51.0% 👈
Terminal-Bench 2.1:
🔴 Original → 46.4%
🟢 With LoRA → 52.4% 👈
Median agent turns on tasks both solved:
🐌 Original → 48 turns
🚀 With LoRA → 13 turns 👈
That's a 15.7% improvement on the selected SWE-bench Pro tasks and 73% fewer agent turns on shared solves.
With thinking disabled, the adapted model reportedly approaches or exceeds the original model running at maximum reasoning effort, using 6–8× fewer generated tokens per task in the team's comparison.
The best part?
💾 Adapter → ~300MB
🧠 Base model → Qwen3.8-27B
🔓 License → Apache 2.0
💻 Local inference → llama.cpp
🛠️ Coding harness → OpenCode
📦 GGUF adapter available
Just a small adapter teaching an existing model to use coding tools more effectively.
Video source: @HuggingFace
How much can you improve a small model in 18 days on 144 GPUs?
Meet DaisyRose-27B, RadixArk's first open-weight model! It is trained with RL on Qwen3.8-27B, with 1,200 curated long-horizon agent tasks for 18 days on 144 H200s. Powered by Miles and our own training backend, we stretched agent sessions up to 1M tokens and raised the Terminal-Bench 4.1 score from 5.6% to 12.0%.
See how we pull it off ⬇️
We have published new CVEs for React Router (4 high, 3 moderate).
Upgrade to v7.18.6 or v8.5.2 for the most up to date fixes. See the advisories on GitHub for more details:
https://t.co/ceAE9RPFuw
ruby2ßhell: one-byte heap overflow in Ruby to unauthenticated RCE in stock Rails, GitHub, GitLab, Mastodon, Discourse and more.
https://t.co/42RbHA1GXX
Update your Ruby version (and self-hosted software)!
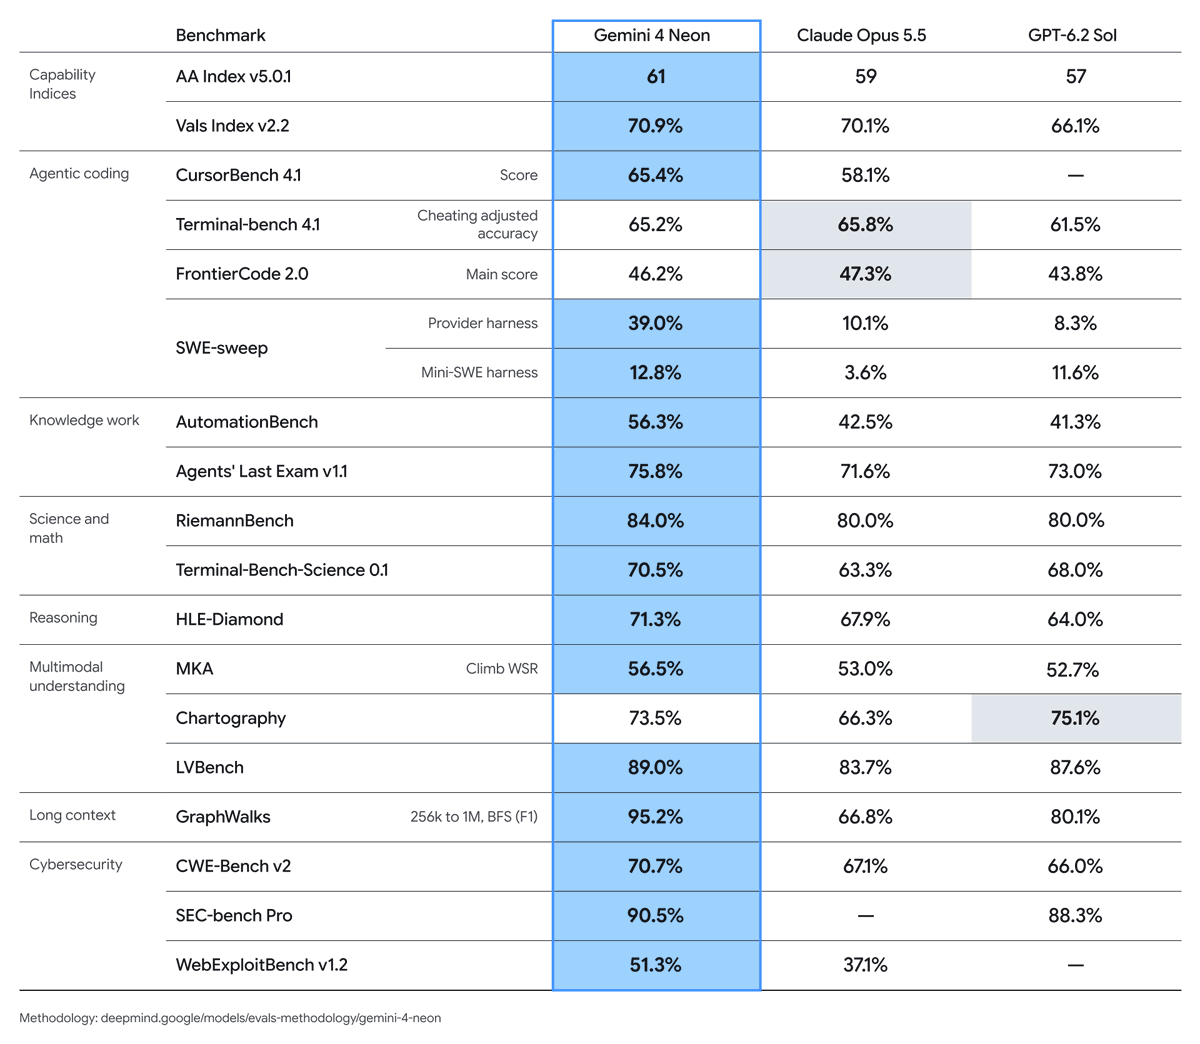
Gemini 4 Neon is rolling out now.
Sitting between Carbon and Hydrogen, it brings frontier intelligence and fast task completion for complex software engineering, knowledge work, and science.