A jaguar swam through the Amazon rainforest.
A search-based agent filed it under automotive news.
It took the first search hit for "jaguar": Jaguar Cars.
Today resolve() enters public beta: an API that tells your agent which thing a name refers to, or says it doesn't know.
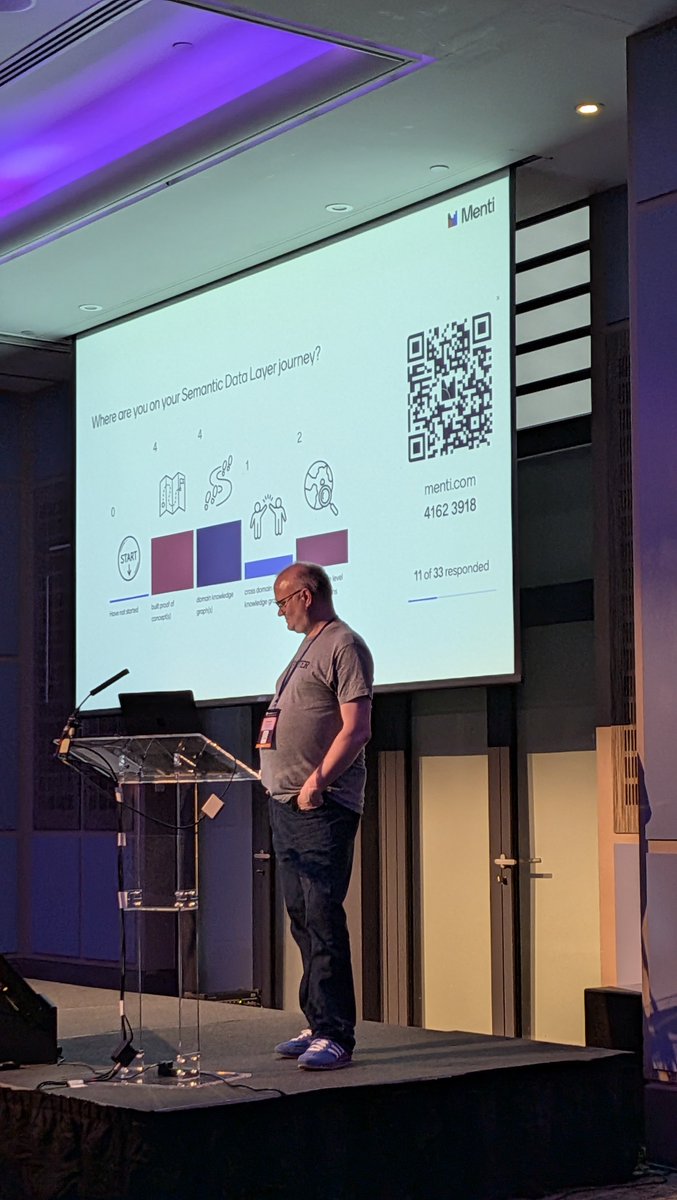
Why there is so much traction on Semantic Technology these days and how far are you on your Semantic Data Layer?
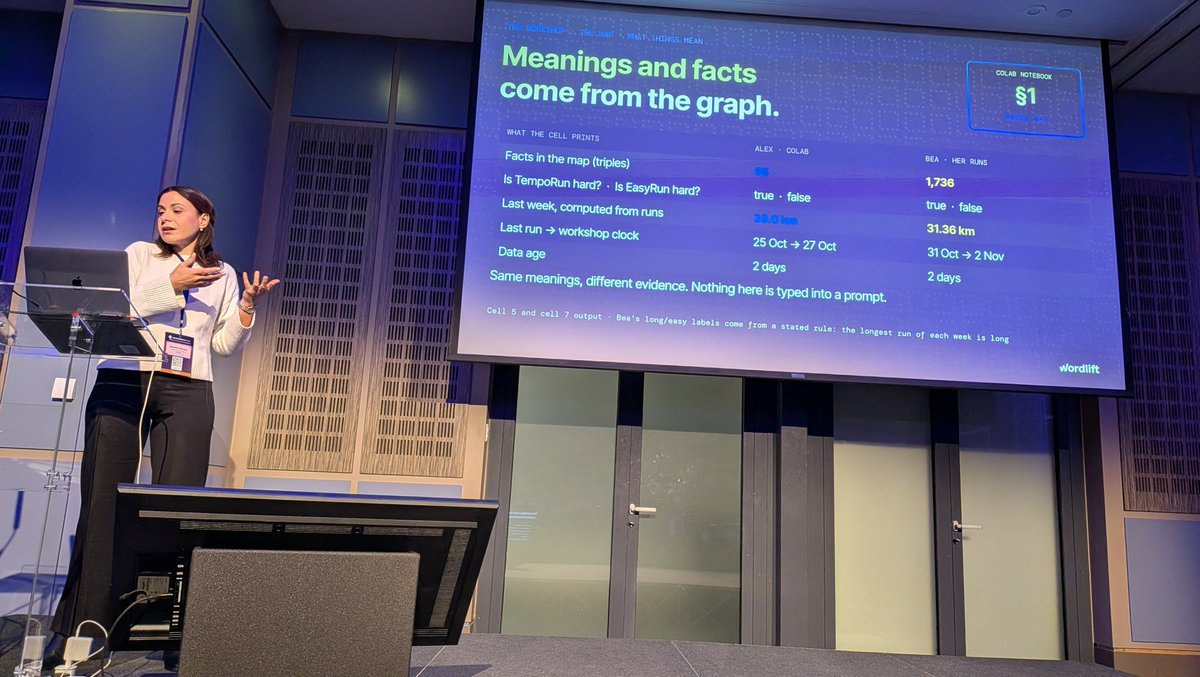
Ben Gardner on stage at #ConnectedData2026
Gemini 4 Carbon is out today - spent a bit of time testing its long-horizon agentic coding on a personal experiment: rebuilding ~220m of downtown Los Gatos in Blender (~50 storefronts + 3D interiors), w/ ~zero manual modeling.
Quick look under the hood 🧵 (1/5)
@stefano_caioni@wordliftit Yes and no 😉
You can start simple by making content and data accessible to AI. Here's a starting point: https://t.co/4wncGf3r26
One of the biggest challenges for AI agents is entity consistency, another is topical authority.
SEOs have been working on both for years.
Your brand is now read by two kinds of AI.
Outside: AI search and shopping agents describing you.
Inside: your AI colleagues acting for you.
If they remember different versions of your business, you lose on both fronts.
One identity. Two permission levels. Your memory.
That’s dual intelligence: one governed memory that feeds your AI visibility outside and your AI colleagues inside. We call it sovereign semantic memory.
https://t.co/kXOaGGQAzq
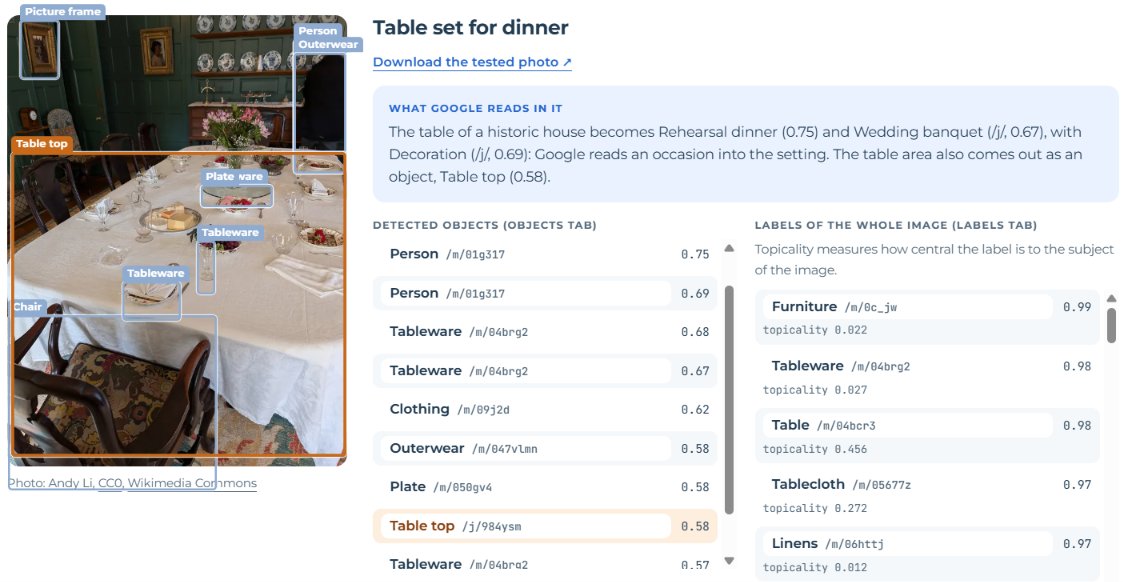
New in our "Understanding Google" series: what Google sees in an image
Below the KG entities, Google tags photos with /j/ dimensions and /a/ values. They are the names of Google Shopping filters: "Sleeve style" → "Long sleeve"
Read it and test it: https://t.co/VDeTJ5bQ5X
Well this is pretty big news: OpenAI is building an analytics tool to see how businesses appear and get cited in ChatGPT.
Is this the first iteration of a ChatGPT Search Console? 👀👀👀
Will be following this closely!
H/t @HannsKronenberg for flagging
https://t.co/bz9zyMDSjL
18 of the 20 best open models today are Mixture-of-Experts. Dense is basically over.
And yet the know-how to train a good MoE still lives mostly in the heads of a handful of teams.
So we spent 800k GPU hours running the experiments ourselves and wrote everything down. Super happy to finally release "The Ultimate MoE Training Handbook", free and open, organized around the questions training teams hit:
- how many experts, how big, shared or not?
- why is half my step spent in all-to-all, and how do I hide it?
- why is my run 25x slower with no error in the logs?
- softmax, sigmoid or sqrt(softplus) router, and why keep it in fp32?
- aux loss or DeepSeek's loss-free bias?
- upcycle a dense checkpoint or train from scratch?
- can I serve with fewer experts per token than I trained with?
⚠️ Warning: it's long (~70k words, budget a few days, sorry) but with 55 interactive figures, code you can run and numbers from our own runs.
Read it here: https://t.co/6XihlUrj92
There's a buzzy new paper about GPT-6 Astra being able to directly interpret model weights (prompts full of floating point numbers) - I tried it with Qwen 3.8 27B on my laptop and found that, after 45+ minutes, that model could achieve the same thing https://t.co/6O7WltGP7K
the computer use tool in the gemini api is now generally available
no breaking changes from preview, just production-ready stability for your browser, mobile, and desktop agents
docs here: https://t.co/aAOowowA4G
So it's bigger than Bing now? Hmm... -> ChatGPT Consumer Product Lead Adam Fry says ChatGPT has hit 1.2B WAUs, adding 200M over the past two months, and says its search volume is now ~20% of Google's. Also, voice reaches 250M weekly users
When asked what is counted as a "search":
"Every time you ask a question and go search the web, that’s a search."
"What we’ve seen over the last year is people have grown into all these other topics. Things like you’re looking up a person or people or a place or a thing, and it requires up-to-date information. That’s a key element."
"Another big part is finance questions or health questions, where you really want to make sure it’s up-to-date information that’s quite factual, and we’ll do a web search for those questions."
https://t.co/0yrcg7jGtO
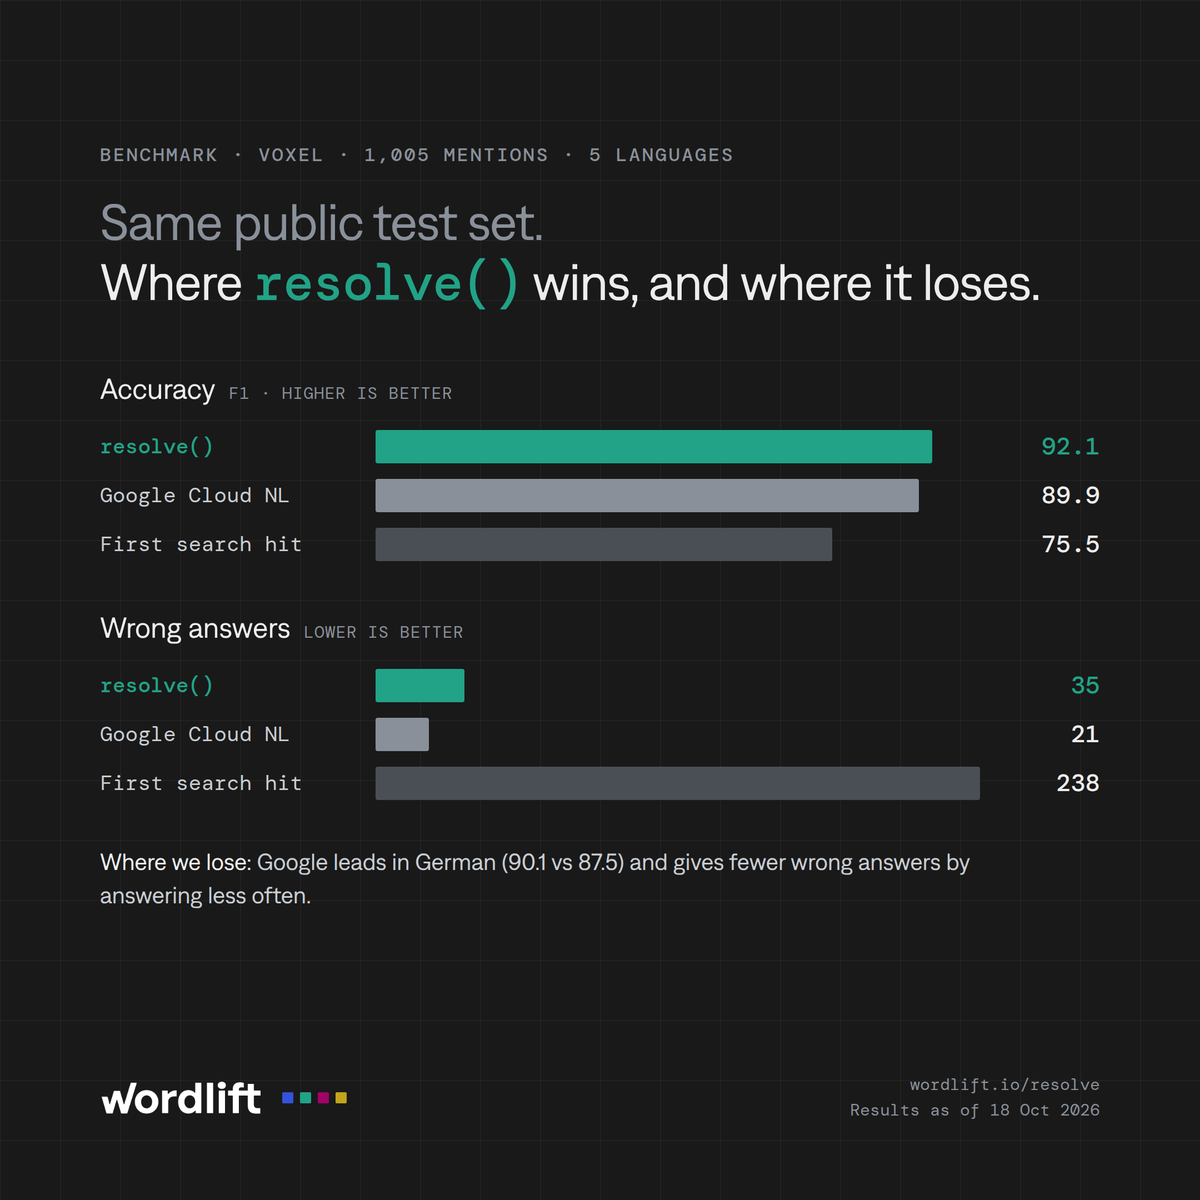
We benchmarked resolve() against Google.
Then we published where we lose.
F1 on VoxEL (1,005 mentions, 5 languages):
resolve() 92.1
Google 89.9
First search hit 75.5 Google wins in German.
Misses included 👇 https://t.co/EzdUCXZV34
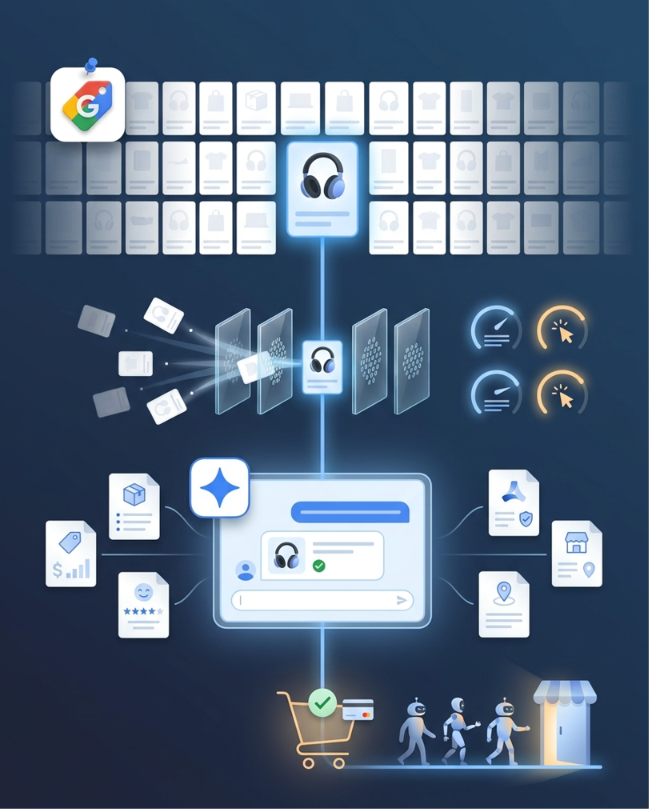
We’ve decoded the mechanisms that determine which products get discovered, selected and recommended by Google in shopping grids, AI Overviews and AI mode
https://t.co/RFDzsn87gi