(Maybe) the first deployable humanoid tracking policy trained via differentiable simulation! Happy to share our recent work on using bundled gradient to help stablizing the gradient information for stiff contact scenarios. Congrats! @dyumanaditya#robotics#rl#diffsim#humanoid
6/7 Why care about differentiable simulation?
First-order learning can be more sample-efficient and faster than PPO.
Making these methods work with realistic contact opens the door to higher-dimensional problems like whole-body loco-manipulation and dexterous manipulation. 🦾
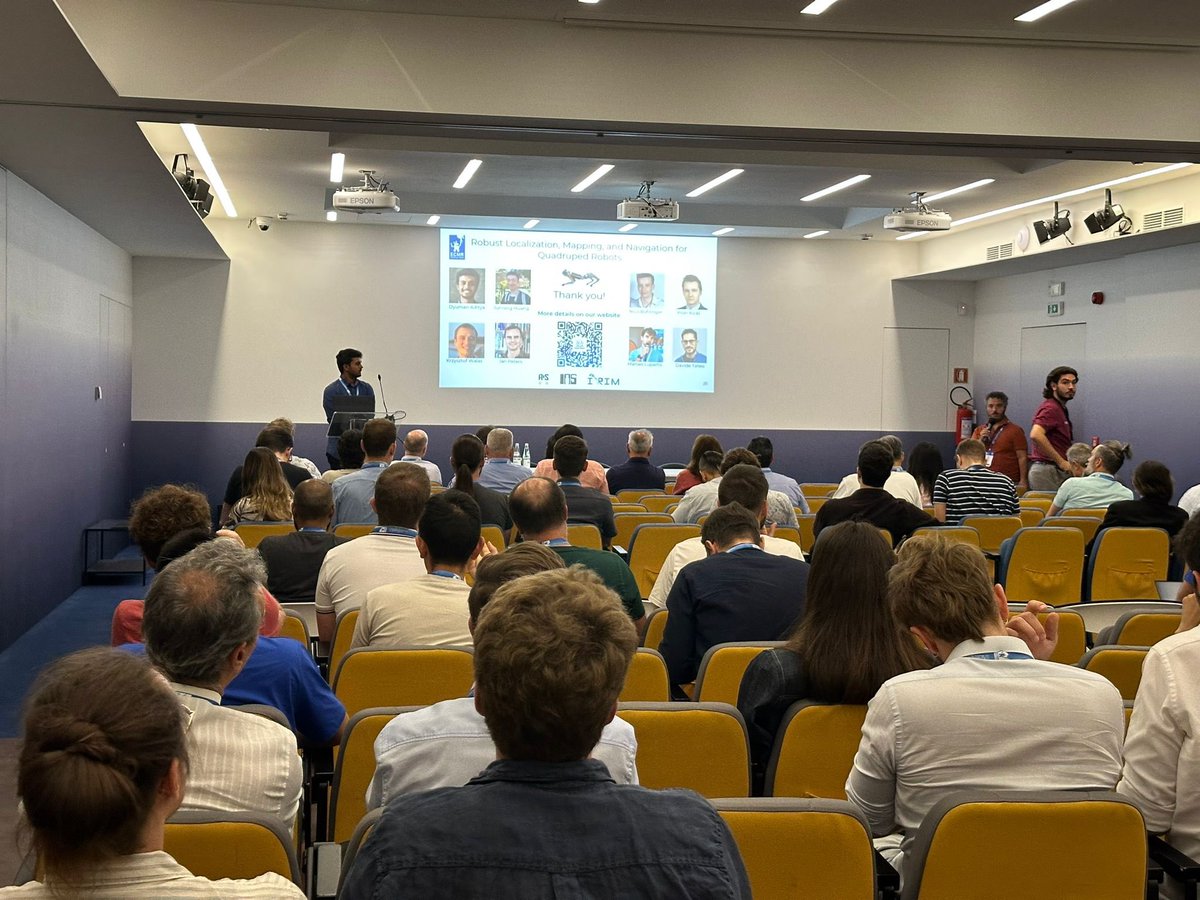
Today, @dyumanaditya presented our paper "Robust Localization, Mapping, and Navigation for Quadruped Robots" at ECMR 2025. It's always a pleasure to see that students and interns of @ias_tudarmstadt succeed and disseminate their ideas and results at conferences!
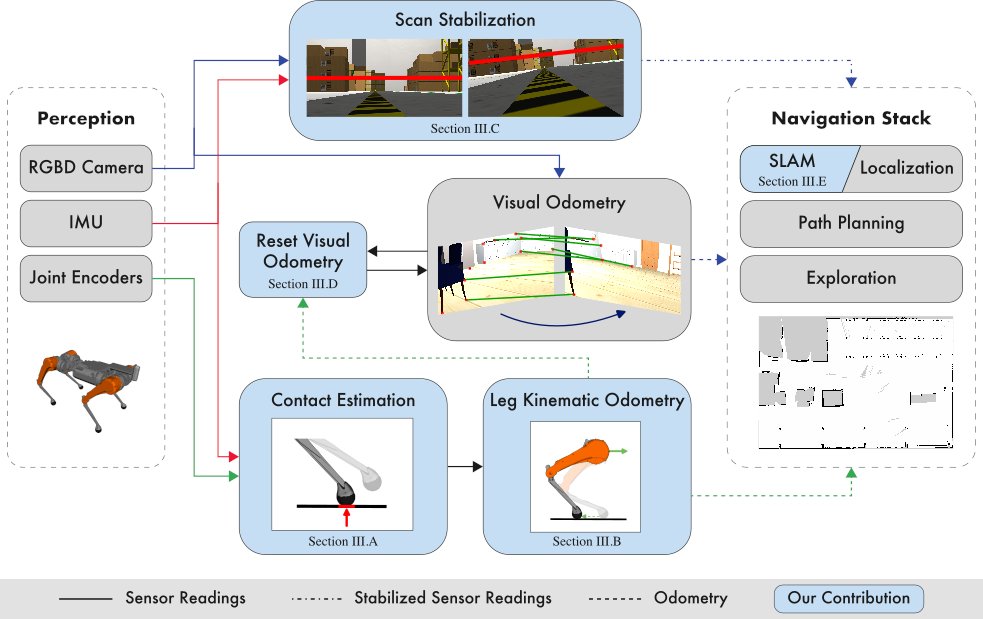
Do you want to deploy a navigation stack on a cheap quadruped robot?
Take a look at our latest ECMR paper, "Robust Localization, Mapping, and Navigation for Quadruped Robots".
In our work, we tackle the issues arising from the combination of low-cost robots and RL policies