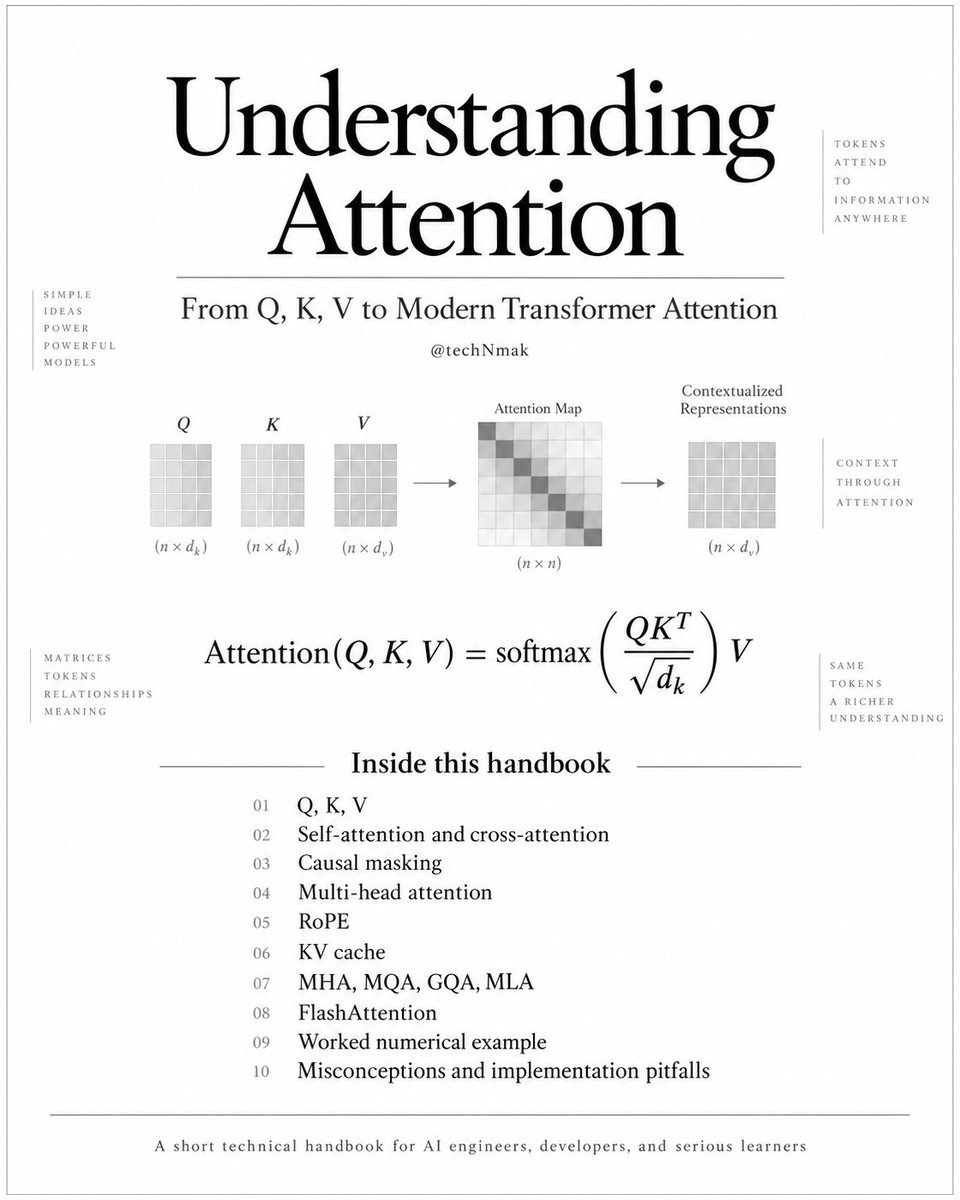
I put together a handbook on how attention works, from the Q/K/V equation up through how it actually runs in modern LLMs.
Self vs. cross-attention, causal masking, multi-head attention, RoPE, KV caching, MHA/MQA/GQA/MLA, FlashAttention, worked through by hand, with citations back to the original papers.
Made it to be the explanation I wish I'd had.
🚨 New: We built @a16z's personal GPU AI Workstation Founders Edition
- 4x NVIDIA RTX 6000 PRO Blackwell Max-Q (384GB total VRAM)
- 8TB of NVMe PCIe 5.0 storage
- AMD Threadripper PRO 7975WX (32 cores, 64 threads)
- 256GB ECC DDR5 RAM
- 1650Watts at peak (runs on a standard 15Amp/120V circuit).
For training, AI research, and deploying models locally. A datacenter-class AI rig you can keep under your desk.
We are planning to make a limited number of these a16z AI Workstations.
Build guide + how you can make your own 👇
WTF... This scraper works like a self-driving car.
You give it a destination… it plans the route, clicks through pages, cleans it up & delivers a perfect spreadsheet.
Goodbye manual scraping, Excel & data teams.
Tutorial + some crazy examples: 🧵
RLVR/RLHF libraries:
• verl - ByteDance
• TRL - HuggingFace
• slime - Zhipu AI
• prime-rl - Prime Intellect
• ROLL - Alibaba
• Nemo-RL - NVIDIA
• AReaL - Ant Research
• SkyRL - UC Berkeley
• open-instruct - Allen AI
• torchtune - PyTorch
Any I am missing? Which do you like?
time to finally read this one, my Lead Engineer forced me today to read this and to do AoC using C++
I told him I had never done competitive coding so he said go read this and do Advent of Code. Idk what he is cooking but all his advice till now has worked for me
🚨 New Paper Alert 🚨
A Systematic Survey and Critical Review on Evaluating
Large Language Models: Challenges, Limitations, and Recommendations
(1/) VCs are putting thousands of $$$ depending of certain benchmarks while they can be easily hacked or misinterpreted.
(2/) A pretrainers nightmare is not "how to tweak" the model, rather it's "what to tweak" in the model. Without evals it's almost impossible to take educative decision.
(3/) There is a notion in the community that LLM evals are broken, but there's hardly any summary. (👇)
اختبر هوراس هاي GPT-4 مع بعض مسائل البرمجة من موقع يدعى Codeforces. وما الذي جعل موقع Codeforces جيداً حقاً لهذه التجربة الصغيرة بالذات هو أن تاريخ إصدار كل مسألة برمجة مذكور صراحةً. لذا ما فعله هو أنه جمع 10 ألغاز تم إصدارها في الوقت الذي كان يتم فيه تدريب GPT-4 (لذا من المحتمل أن تكون في بيانات التدريب الخاصة به) وقام بسؤال GPT-4 حيث حلها GPT-4 كلها بشكل صحيح.
يا للهول! إنه قادم لوظائفنا.
ولكن ما فعله بعد ذلك هو أنه جمع 10 ألغاز أخرى تم إصدارها بعد تدريب GPT-4. كانت هذه الألغاز بنفس مستوى الصعوبة، ولكن هذه المرة، أخطأ GPT-4 في كل واحدة منها.
إذن ماذا حدث؟ حسناً، أثار هذا الكثير من الشكوك حول أن GPT-4 كان قادراً على حل هذه الألغاز فقط لأنها موجودة في بيانات التدريب وأنه حفظها فقط.
السرد:
https://t.co/Nmjo4NbGSg
المحاضرة:
https://t.co/S0gkcC38Ns
@Abdullah_14_H المشكلة في peer review في علم تعلم الآلة ان تضخم عدد الاوراق المقدمة جعل كثير من المؤتمرات تلزم اصحاب الاوراق المقدمة ان يقوم بعملية مراجعة لورقة اخرى في المؤتمر وهذا يقدم عدد من المراجعين ذوي الكفاءة المتدنية
@deliprao@abidlabs Model.eval() deactivates certain features as dropout, which only works during training. On the other hand, inference_model() prevents gradient from being calculated
Happy to share that BLOOM+1 has been accepted to #ACL2023/#acl2023nlp (thanks to all @BigscienceW contributors)! If you want to know how to adapt BLOOM/BLOOMZ to an unseen language, come check out our work!
TL;DR: smaller models benefit from continued pretraining, and larger models from adapters.
11 ways ChatGPT saves me hours of work every day, and why you'll never outcompete those who use AI effectively.
A list for those who write code:
1 of 16
Over the xmas break I was shuffling between https://t.co/wReA0FvRDu and JUWELS Booster super computer trying to find some less busy slurm queues to train the first sets of 'ConvNeXt-Base' models. This past week the first Large came off the line on Stability.
Bito is a new #ChatGPT-like assistant for your IDE (@pycharm / VS @Code) or @googlechrome which makes it easy to:
✔️ Write/explain code
✔️ Understand syntax
✔️ Write test cases
✔️ Check security
✔️ Fix bugs
Bito is in alpha & is free to use! 🔥🔥🔥
🔗 https://t.co/1leaK36ode
⭐️PhD Interviews⭐️
Now that most PhD app deadlines have passed. Next step would be interviews: Here I had compiled a list of FAQs that was typical from my exp. last year.
Link: https://t.co/QczoBqOrqg
#PhD#PhDApplications#phdlife#Fall2023
1/n