Today we’re announcing the $600M Formation Bio Drug Development Accelerator Fund.
@lintaho and I started @FormationBio because we believed the biggest bottleneck in bringing new medicines to patients wasn’t drug discovery, but drug development.
As AI dramatically accelerates discovery, that bottleneck is only becoming more acute. Without the capital and capacity to advance promising drugs through clinical trials, much of that progress won’t translate into medicines for patients.
Our new Fund brings together dedicated capital, drug development expertise, and AI-powered development capabilities to acquire promising drugs and advance them through the clinic.
Avengers assemble: 1 year BakerLab + NVIDIA GenAIR = 🔥 https://t.co/Cd2qiugCJo
Presenting RFD4-Proteina, our latest protein design model, significantly better and faster than everything we compared against, both in silico and in the lab! 1/30
In light of the progress in mathematics, we at Edison Scientific and FutureHouse have assembled a set of Millennium Problems for Biology. They are chosen to be very hard to solve but very easy to validate in a simple laboratory environment. Any of these, if solved, would mark a major advance in biotechnology, and most of them would contribute materially towards curing disease. These are, in some sense, the “last reasonable eval” for AI in biology. This was work primarily by @MichaelaThinks and myself, with contributions from many others.
Short descriptions below. The full descriptions of the problems with acceptance criteria are at the Bio Millennium Problems website, linked in the next post. Share more if you have ideas. If they meet our criteria, we’ll add them to our list (with attribution and permission).
Andrew Zaloumis
Airs Thursday 6pm KSA (GMT+3)
Andrew is the CEO of Prince Mohammed bin Salman Royal Reserve Development Authority @PMBSRReserve internationally recognized for his pioneering work in conservation and community-driven environmental management.
#TheMoShow158
Claude Shannon's 1940 MIT doctoral thesis dealt with the mathematics of genetics. So the person who would later establish information theory actually earned his PhD in mathematics with research connected to genetics.
بعد 3 سنوات من التجربة والعمل والخطأ والجنون والكثير من الشك؛ هدهد ينطلق ليناطح كبرى شركات العالم!
هذا الفيديو يشرح لكم الحلم الذي يظنه البعض بعيد، وأراه قريب.
تعليقاتكم تهمني لأني أعتقد أنكم جزء من هذا المستقبل.
btw anthropic's internal document on this literally said "we don't want it to be known that we are working on this.”
it was called project panama.
here's exactly what happened:
1: anthropic concluded that books were the cheapest way to build a world-class model because they gave claude curated facts, structured arguments, compelling stories, and writing “an editor would approve of.”
2: once anthropic decided it needed books at enormous scale, its first solution was piracy.
it downloaded 7m+ books from online libraries including libgen. the judge later wrote that although anthropic had legal ways to buy them, it chose piracy to avoid what dario amodei called the “legal/practice/business slog.”
3: that piracy created a massive legal risk.
so in february 2024, anthropic hired tom turvey, the former head of partnerships for google books, to find a legally safer way of obtaining “all the books in the world.”
4: turvey first contacted major publishers about licensing their catalogs.
those attempts didn’t produce agreements, so anthropic chose a route that required no publisher permission: buying millions of physical books through distributors and used-book retailers.
5: within about a year, anthropic spent tens of millions acquiring and scanning millions of books, including many rare and 1/1 titles. one vendor proposal targeted 500,000 to 2 million books in six months.
6: to scan that many books within months, the vendors physically dismantled them.
a hydraulic cutter removed each spine. the pages were trimmed to size, fed as loose sheets through high-speed industrial scanners, and converted into searchable PDFs. the paper remains were then sent for recycling.
7: these PDFs were fed into claude as training data.
the complete collection became a private, searchable anthropic library that the company planned to “store forever.” the scans aren’t available to the public and were never open-sourced.
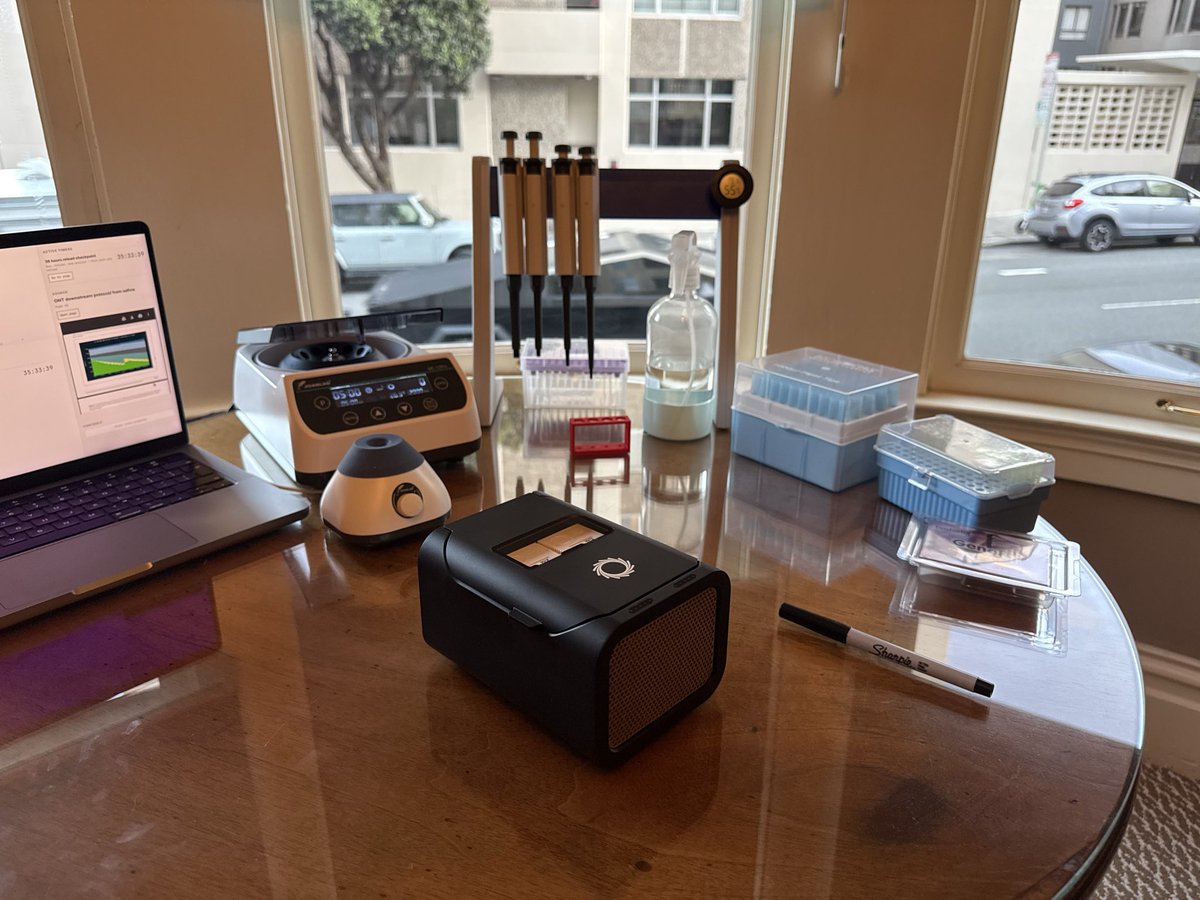
I just sequenced a human genome to 30× coverage entirely at home.
As far as I know, this is the first time this has been done.
I didn’t step foot in a lab once. Every step - from saliva collection, to running the sequencer - took place in a single room with a dining table + kitchenette.
Six weeks ago, I had never done wet lab biology before.
I used an Oxford Nanopore P2 Solo - the only commercially available sequencing device portable enough to do 30x human genome sequencing at home.
Biggest takeaway - I could build something that combined software, hardware, and molecular biology far faster than I thought was possible.
I can name >100 specific instances where AI helped me solve a technical problem that would previously have blocked me because I lacked access to a domain expert.
For example: how do I save my sequencing run when my DNA extraction yield is 4x lower than I need it to be, and I have this limited set of reagents to hand?
To make this work, I had to navigate multiple disciplines:
- writing software to monitor sequencing runs and orchestrate remote GPU infra for basecalling
- learning + executing 5 hour long molecular biology protocols
- building a hardware device to quantify DNA concentration
Apologies for the hyperbole, but I feel super lucky to be living in 2026.
A few weeks ago I decided to sequence a human genome to 30x at home.
Then I actually did it. And I did it really quickly.
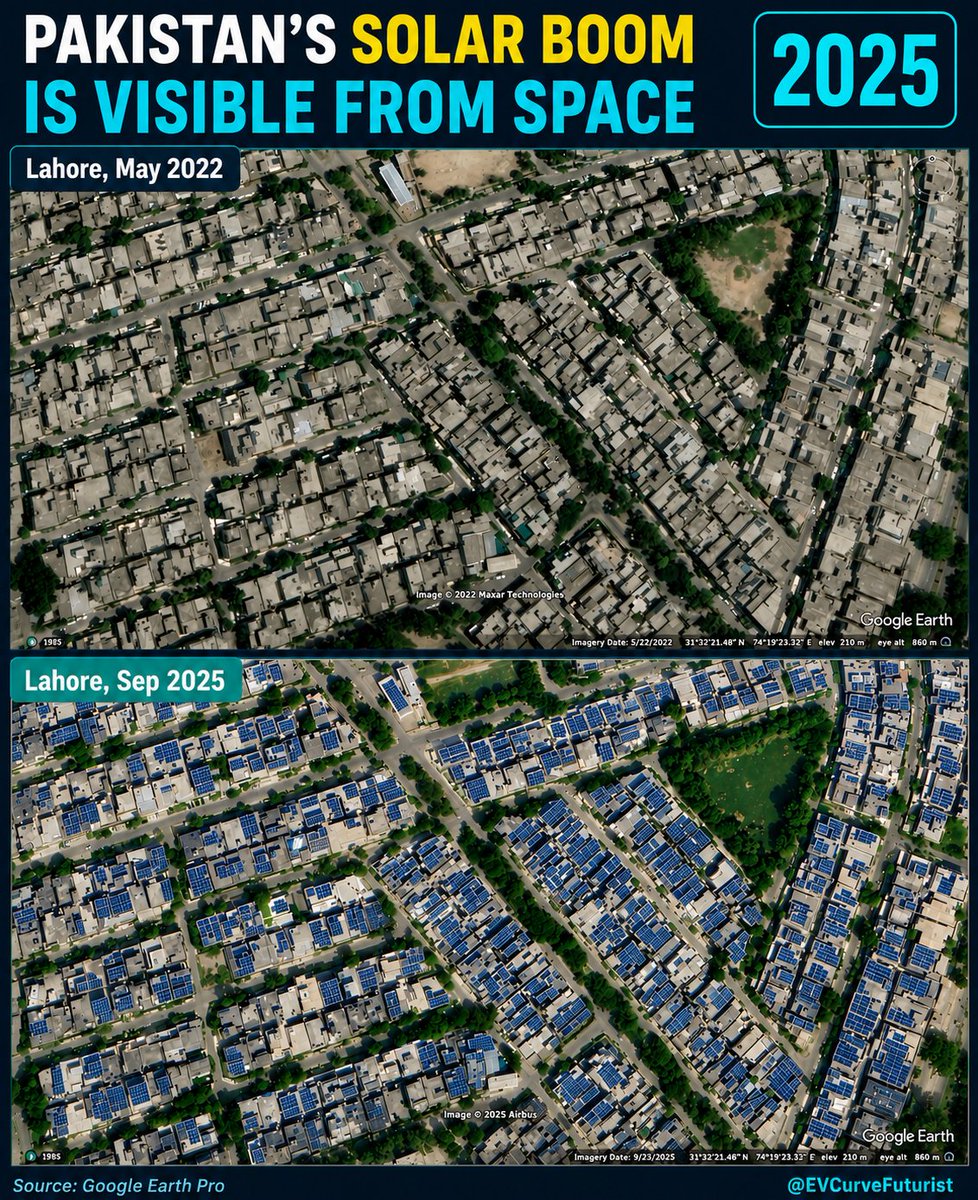
Pakistan may be accidentally building one of the world’s first decentralised #solar economies. The craziest part? Real scale barely shows in official stats. Imported 51.5 GW solar panels by late 2025—nearly = entire grid. Yet registered net-metered rooftop solar just 5.3–6.8 GW.
What makes this story so extraordinary is the speed.
In only a few years, Pakistan appears to have gone from a relatively minor solar market to potentially sourcing around a quarter of its electricity from solar once distributed generation is included.
👉 ~16.6–17 GW solar imports in 2024
👉 ~18 GW solar imports in 2025
👉 ~51.5 GW cumulative imports by late 2025
👉 Rooftop solar: ~1.3 GW → 4.1 GW in 2024
👉 ~5.3–6.8 GW registered rooftop solar in 2025
👉 24+ GW estimated behind-the-meter/off-grid
👉 Solar potentially ~25% of actual electricity use
The massive gap between imported panels and officially registered systems strongly suggests tens of gigawatts are now operating quietly on homes, farms, factories and businesses across the country.
This increasingly looks less like a normal energy transition and more like large-scale consumer-led grid defection.
And economics is driving nearly all of it.
Electricity tariffs surged. Diesel prices climbed. Blackouts remained common. Meanwhile ultra-cheap Chinese solar panels and falling battery prices made self-generation economically irresistible.
So millions effectively made the same calculation:
Generate your own power, or remain trapped inside an expensive and unstable system.
Once solar becomes cheaper than the grid itself, adoption can move faster than governments, utilities and even official statistics can keep up with.
This isn’t gradual transition by any stretch. It may ultimately become a blueprint for how energy-poor nations break free from legacy old-world energy systems dominated by fossil fuels and increasingly expensive centralised power.
It’s decentralisation at escape velocity.
This is #Bettrification.
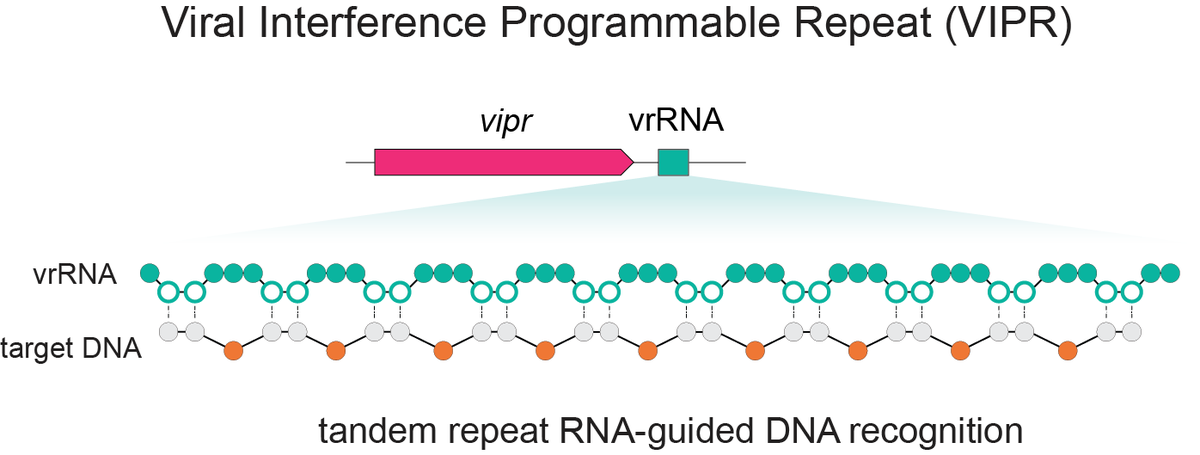
Excited to share our discovery of a new programmable RNA-guided DNA-targeting system hiding inside bacteriophages that predates CRISPR.
We call it VIPR (Viral Interference Programmable Repeat), and it uses an entirely new logic to find its targets.
Thread + link below.
Two Pakistani candidates Muhammad Zeeshan Ali and Khurram Daud have been selected as the first foreign astronauts to train for China's space station missions, the China Manned Space Agency announced on Wednesday. #XinhuaNews
Following on from Kitchen table genomes/liquid biopsy. There are two forces at work, a centralization one and a decentralization one. Large companies are trying to trap everything in central data centers with proprietary data streams, giving them a moat and control, others are pushing to run AI and other things locally empowering individual users. Same is happening to bio/medical data including sequencing.
I sequenced my genome at home, on my kitchen table.
I wrote up exactly how I did it - the equipment, protocol, theory, and cost:
https://t.co/Nkjqaho2zm
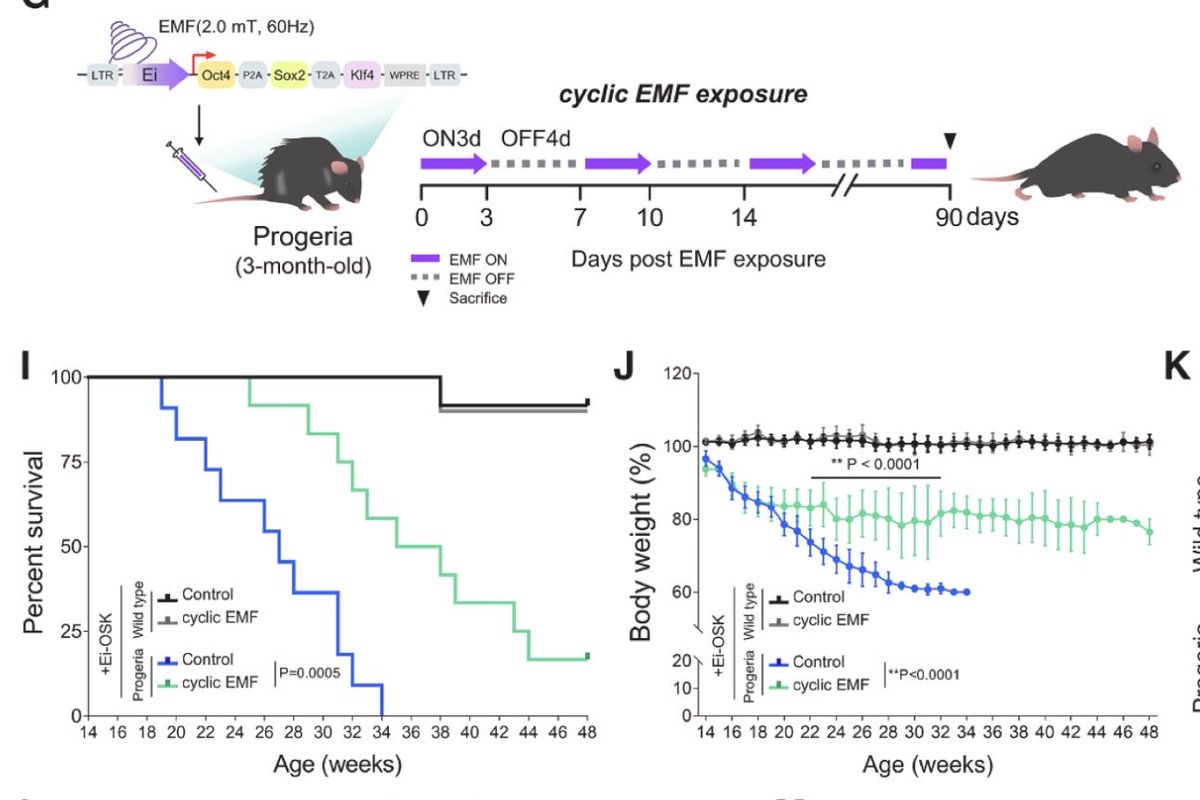
REMOTE CONTROL MICE! A group from Seoul has just published in Cell that they’ve discovered a crazy-weird protein (Cyb5b) that can be used to turn on any gene when exposed to EMFs!
They used it to turn on OSK and extend the lifespan of a progeroid mouse. More to come on this…
🇦🇺An Australian tech founder with zero biology background sequenced his dog’s tumor DNA, then used ChatGPT and AlphaFold to design a custom mRNA cancer vaccine.
A month later, the tumors shrank by half.
And this is just the start of AI medicine.