My Ph.D. dissertation on "Unsupervised sound separation" is online https://t.co/Fg3d1QG2WC 😎 If you are interested in self-supervised, multi-modal, efficient and federated learning aspects for sound separation, feel free to take a look 👀
“A major source of objection to a free economy is precisely that it does this task so well: it gives people what they want instead of what a particular group thinks they ought to want.”
— Milton Friedman
Larry Page & Sergey Brin had the PageRank paper (the algorithm behind Google Search) rejected. A reviewer called it “disjointed.”
Geoffrey Hinton's Dropout was rejected for being “too simple.”
I often feel the academic peer review is like a random process, especially when a paper is very innovative and changes the paradigm; it often looks "wrong" to reviewers in the old paradigm.
And that's Google's ‘Ironwood,’ its most powerful 7-th gen TPU.
- delivers 4,614 FP8 TFLOPS of performance and is equipped with 192 GB of HBM3E memory, offering a bandwidth of up to 7.37 TB/s.
- Ironwood pods scale up to 9,216 AI accelerators, delivering a total of 42.5 FP8 ExaFLOPS for training and inference, which by far exceeds the FP8 capabilities of Nvidia's GB300 NVL72 system that stands at 0.36 ExaFLOPS.
- The pod is interconnected using a proprietary 9.6 Tb/s Inter-Chip Interconnect network, and carries roughly 1.77 PB of HBM3E memory in total, once again exceeding what Nvidia's competing platform can offer.
---
From `Google Cloud` YT channel
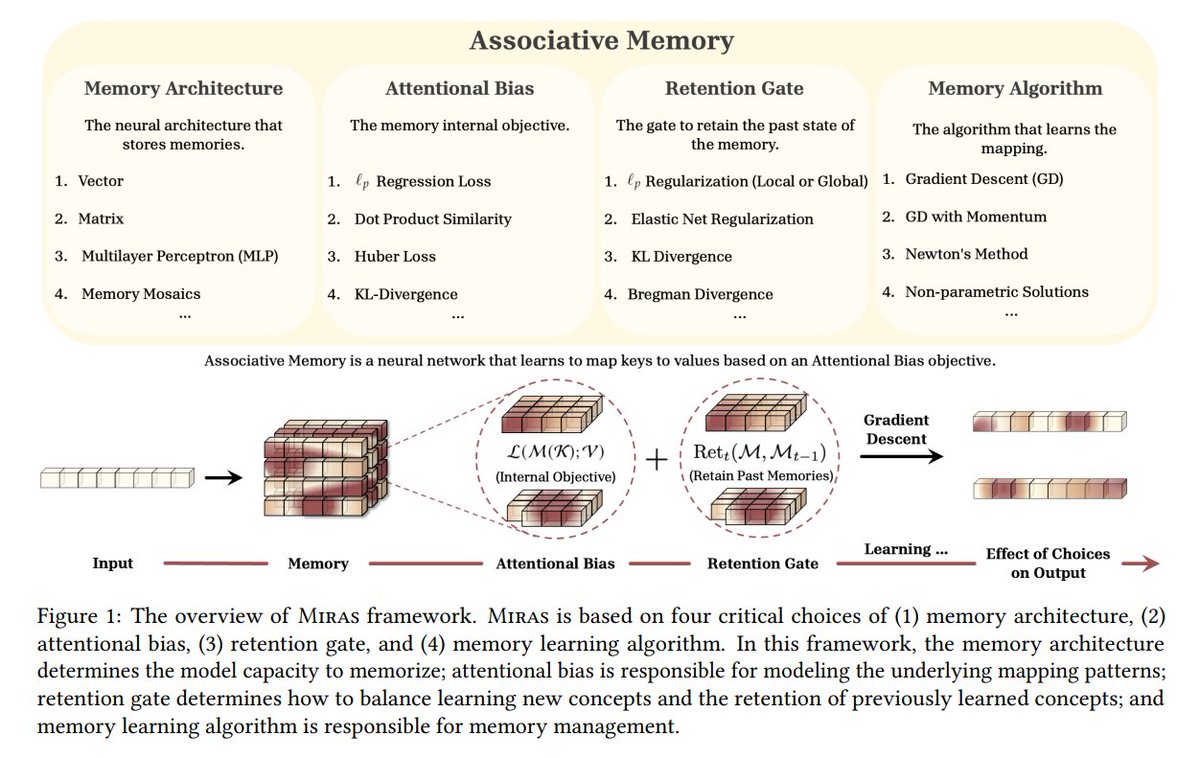
This Google paper presented at #NeurIPS2025 is a true gem.
In their search for a better backbone for sequence models, they:
• Reframe Transformers & RNNs as associative memory systems driven by attentional bias
• Reinterpret "forgetting" as retention regularization, not as erasure
• Combine these insights into Miras – a unified framework for designing next-gen sequence architectures
From this perspective, they introduce 3 new models, Moneta, Yaad, and Memora, that:
- Beat Transformers, Mamba2, DeltaNet, and hybrids across key benchmarks
- Scale better to long contexts
- Deliver state-of-the-art recall on needle-in-a-haystack tests
Here are the details (really worth exploring):
Check out our new work "Score-Guided Diffusion for 3D Human Recovery", a.k.a. ScoreHMR, with @ligongh and Dimitris Metaxas that will appear at #CVPR2024!
Paper: https://t.co/lKMFBh2eow
Project Page: https://t.co/arDU2sMDKh
Code & models: https://t.co/xlO0FjYqKz
This is the proper usage of machine learning models, removing communication barriers and enabling ideas of freedom to reach people's minds. Exceptional speech from Milei stating the obvious truths.
Milei’s talk at Davos
This never happened.
But with AI (HeyGen) his voice is cloned and turned to English (Elevenlabs) and his mouth is re-synched to match the English words.
This is the true power of AI, anything can be consumed in any language
We debated whether or not to share these horrific images, but the world needs to know what we are up against.
These aren’t “freedom fighters”. They are Hamas terrorists, but no different than ISIS terrorists.
Same tactics, different names.
Butchering families, kidnapping grandmothers. Desecrating bodies.
Help us get this message out.
Speech restoration method Miipher (used to generate LibriTTS-R) has been accepted to WASPAA!! It converts degraded speech to studio quality, and generates almost inexhaustible training data for speech generation.
Demo: https://t.co/nsrcIpIPaq
Paper: https://t.co/3D611h2E4C
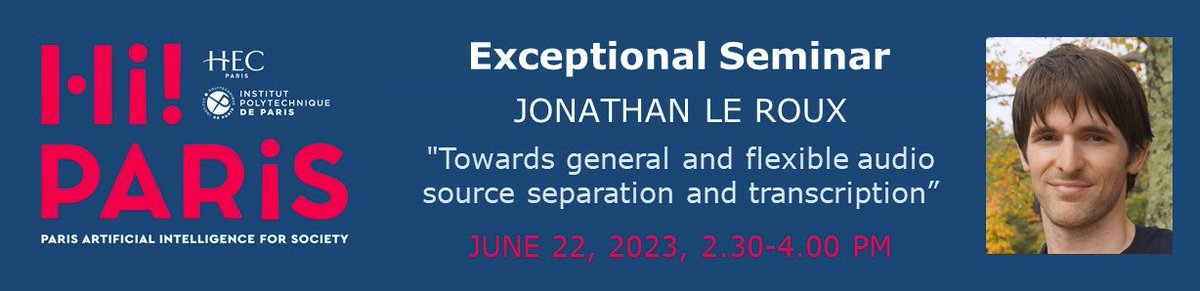
I will be presenting MERL's work on audio source separation and transcription during a seminar organized by #HiPARIScenter this Thursday, 6/22 @telecomparis and on Zoom.
@merl_news@IP_Paris_@HECParis
Registration⬇️
https://t.co/VT5B3sPSzL
Excited to share that I will be presenting our audio synthesis paper at the CVPR Sight & Sound Workshop! 🤩
In this paper, we proposed a new text-to-audio synthesis model that can be trained using videos and a pretrained language-vision model.
#CVPR2023
https://t.co/1Q4PljvniO
I am super excited to share that I just started as a Research Scientist @Google this week!🤩 Looking forward to delving deeper into audio-visual perception and building great products with the @GooglePixelFC folks!😃
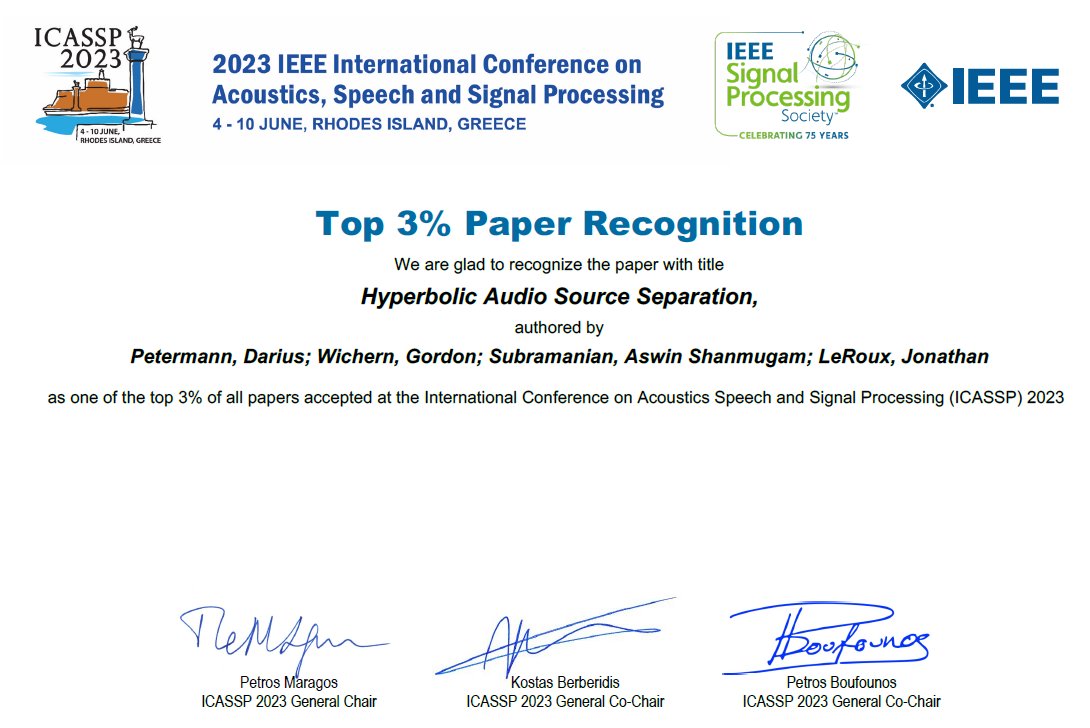
Darius's "Hyperbolic Audio Source Separation" paper has been recognized as one of the top 3% of all papers accepted at #ICASSP2023@ieeeICASSP 👏🎉🍾
Paper: https://t.co/ggl93cdub1
Code: https://t.co/SujTNzkjT3
Demo video: https://t.co/rpqnWzuAL8
Feel free to stop by around 4pm to learn more about optimal condition training for sound separation! Higher upper bounds for conditional separation systems and state-of-the-art text-based separation performance! 🤩 @ieeeICASSP
Our @ieeeICASSP23 optimal condition training presentation is online!https://t.co/v3UpyE5stp
Read our paper with @JonathanLeRoux,Gordon,Paris to learn how to train robust multi-condition separation systems + how to get SOTA text-based separation results!🧐https://t.co/fV95xTF2Gl