Running @ViC305's GLM-5.3 753b recipe on 4 Sparks took four fixes on our cluster:
build the CUDA kernels before loading (warm-up OOM)
one NFS copy of the 319GB pack
hand-written hosts (cloned machine-ids)
swap off
Result: 84.4. All scripts are open:
https://t.co/c3qGayNxpS
Credits: @ViC305 (quant + recipe), TensorFold, the DFlash2 drafter @Zai_org
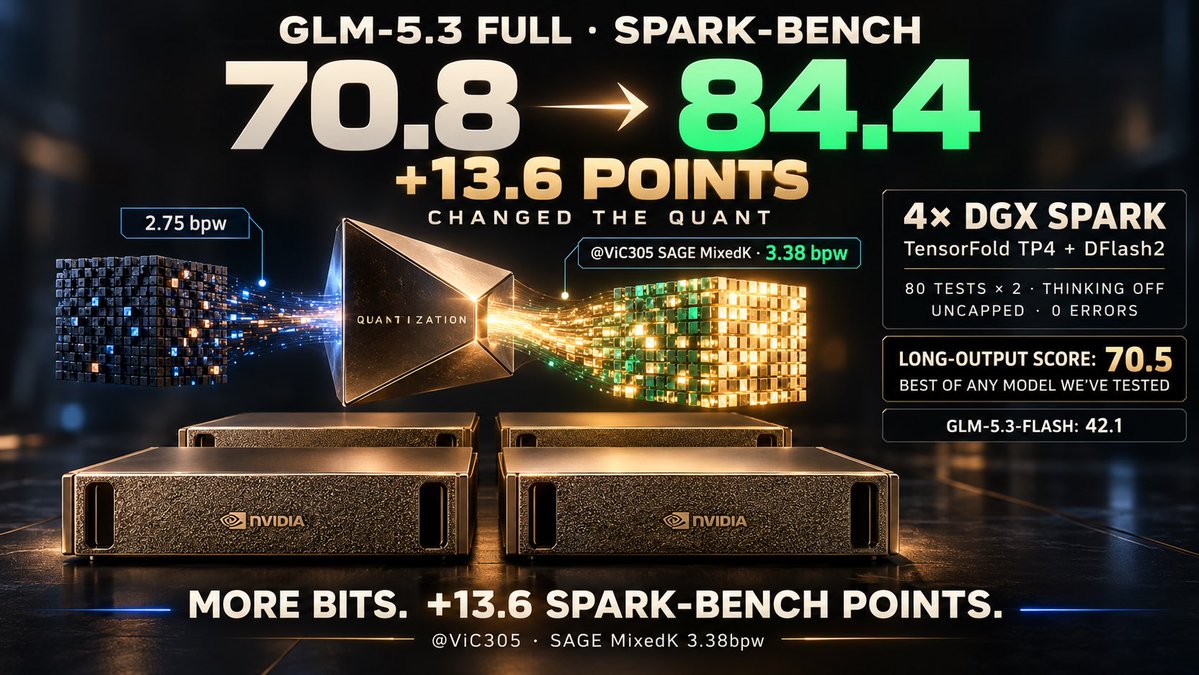
GLM-5.3 753b went from 70.8 to 84.4 on Spark-Bench by changing the quant.
@ViC305's SAGE MixedK 3.38bpw, 4x DGX
Spark, TensorFold TP4 + DFlash2. Vs the 2.75bpw run: +13.6 points.
80 tests, 2 repeats, thinking off, uncapped. O errors.
GLM-5.3 full scored 70.5 on our long-output builds, the best of any model we've tested.
GLM-5.3-Flash got 42.1.
Overall 84.4 on 4x DGX Spark
Reliability (both repeats pass), Full vs Flash
Code: 75.7 vs 90.0.
Robustness: 75.0 vs 50.0.
Long output: 89.2 vs 56.2.
Agentic: 88.0 vs 83.3.
Visual: 82.0 vs 84.2
My DGX Spark was hard powering off every day or two. No kernel panic, no OOM, no logs. Just dead until you power cycle it. Turns out the GB10's embedded controller cuts power on a thermal spike faster than Linux can even write a log line.
The fix is one command: sudo nvidia-smi -lgc 0,2200
3 days crash-free now, cost us ~5% throughput. Wrote up the full diagnosis, a systemd unit so it survives reboots, and the deeper fixes here:
https://t.co/I3yT5ZB3Tp
Shoutout @ivanfioravanti and @pbastowski whose measurements confirm what we found in the trenches.
Two DGX Station GB300s in a Cluster: GLM-5.3: 188 output tok/s on one Station, 5,018 on the pair. GLM-5.2: 11x at 32 streams. DeepSeek V4.1 Flash: 5,248 tok/s. Five models tested:
https://t.co/lCCugGCdsM
#DGXStation#GB300#AIInfrastructure@NVIDIAAI