

Top Tweets for #LLMevals


If you're picking a coding agent off a leaderboard, test it the way your team actually talks to it. The dataset is open:
https://t.co/kWo9Zamffq
#AIAgents #CodingAgents #LLMEvals #DevTools


https://t.co/WKr8UHZidT
#AIEngineering #RAG #Jev #AIInfrastructure #LLMEvals #jev
#DataEngineering #Temporal #dbt

Before: a prompt change ships, pass rate looks fine, users find the regression a week later.
After: a config file in the repo fails CI on the PR.
Here is why 👇
https://t.co/LL5HBZk8l8
#AI #LLM #GenerativeAI #LlmEvals
Which part took you the longest to get right?


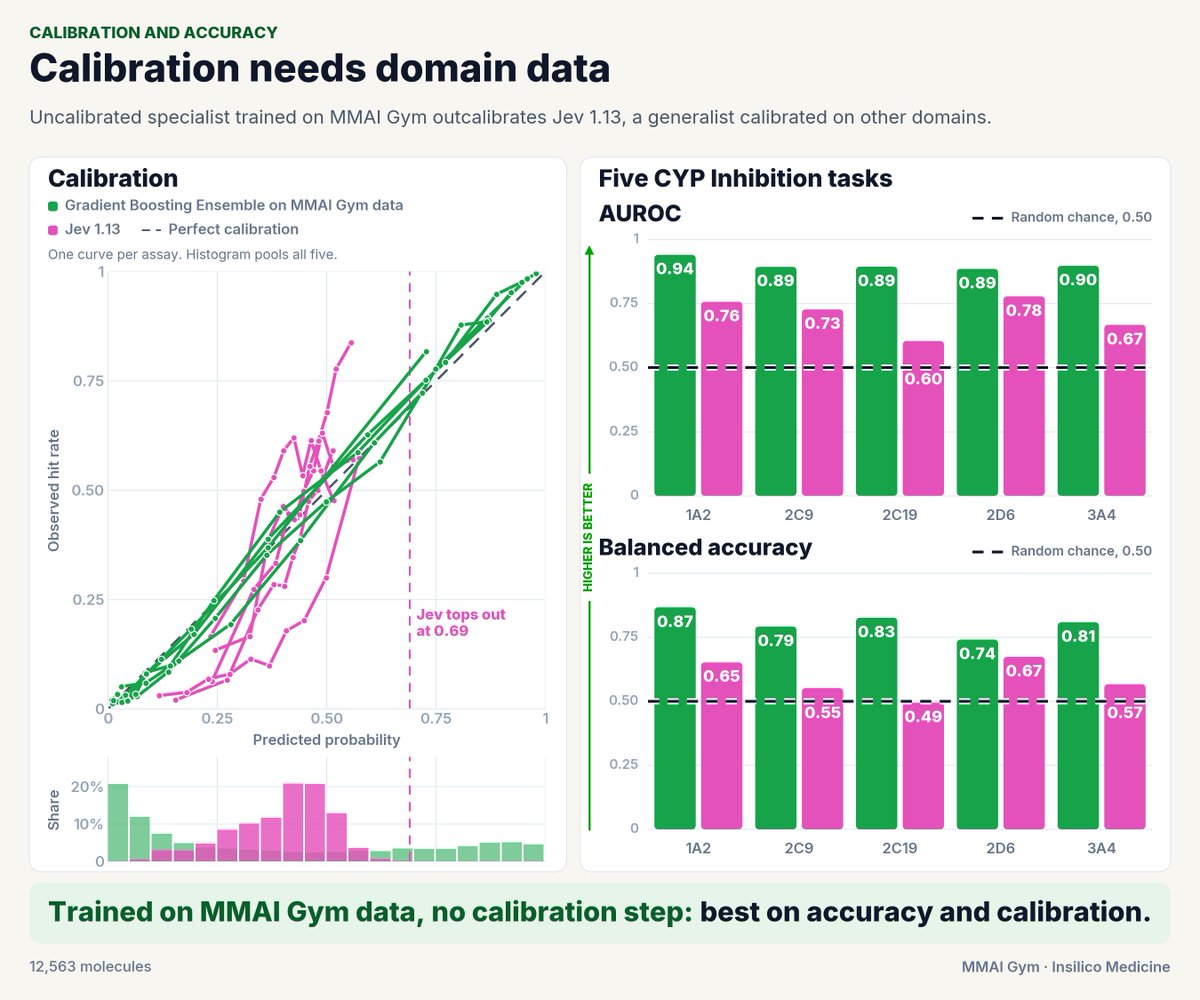
A specialist with no calibration step outcalibrates a calibrated generalist 🤔
A GB model trained on MMAI Gym data beats Jev on both discrimination and calibration across five CYP inhibition tasks.
Balanced accuracy: 0.74-0.87 vs 0.49-0.67.
@InSilicoMeds

Ornith-1.5 proposes its own tasks, builds its own scaffolds, and generates its own RL rollouts — a model creating the experiences it learns from.
Open weights, MIT, Opus-4.8-comparable. #LLMEvals #OpenWeights

Aloha! 🌺Introducing Ornith-1.5, a family of open-source LLMs spanning 9B Dense, 35B MoE, and 397B MoE, trained with self-improving strategies.
It achieves state-of-the-art performance among open-source models of comparable size and delivers performance comparable to Claude Opus 4.8 across reasoning, agentic, and coding tasks:
✅Terminal-Bench 2.1 (86.1)
✅SWE-Bench (86 on verified, 65.1 on pro, 79.6 on Multilingual)
✅DeepSWE (56)
✅HLE (44.6)
✅ClawEval (81.4)
✅Tool Decathlon (71.2)
Ornith-1.5 takes a major step toward training foundation models through end-to-end self-improvement, extending the self-scaffolding strategies introduced in Ornith-1.0 into a more complete self-improvement loop: the model proposes new tasks, generates task-specific scaffolds, and produces solution rollouts for reinforcement learning, continuously creating new learning experiences from which it can improve.
All models, along with their quantized versions (FP8, GGUF, MLX, and NVFP4), have been released under the MIT License, enabling unrestricted commercial and research use.
📘Tech Blog: https://t.co/OZ63scRWLB
🤗Huggingface: https://t.co/mGJLwhrQOM


💊 Protein drugs can be sticky.
They can clump together or stick to vials, filters, and needles, creating costly problems downstream.
🔬 Can frontier models predict which proteins will be sticky before years of lab work?
Our new benchmark puts current models to the test on protein stickiness prediction.

Everyone is asking: how is new Qwen 3.8-Max in #URSAbench for synthesis planning ⁉️
1⃣ Well, it is much better than new Kimi K3
2⃣ Winter ❄️ (3.5) to summer, ☀️ Qwen's performance boosted +650% 🚀 , while Kimi is only +60%
3⃣ Qwen reached the level of Grok 4.5 (not bad), but beyond Opus (19%) and Sol 5.6 (26%).
Great job so far @Ali_TongyiLab @Alibaba_Qwen 👏
For more details, check our Benchmark Explorer at #DDDBench by @InSilicoMeds ⬇️

Great reminder from @morganlinton: run models multiple times and the leaderboard changes. On VulcanBench, 3-pass runs pushed Grok 4.5 High to #1 and dropped DeepSeek V4-Flash two spots. Single-pass rankings hide variance. #LLMEvals #LLMOps

So I decided to try something interesting last night.
Since DeepSeek and Grok are so cost-effective, I can afford to run them with 3 passes on @VulcanBench.
When I did, the rankings changed. DeepSeek V4-Flash actually dropped in the rankings by two and Grok 4.5 High took the #1 spot.
My challenge now is, while I'd love to run all the other models at 3 passes, this would cost over $350, and VulcanBench is just a little self-funded project of mine.
For now I've added whiskers to the chart and a footnote to make it clear which models have been run @ 1 pass vs. @ 3 passes.

Big jump from @AnthropicAI: Opus 5.0 improves 90% (10→19) on the hardest #URSAbench synthesis-planning set vs Opus 4.8 — and without ANY tools or orchestration. #LLMEvals #AI4DD
I am not a specialist in all of these disproved/proved conjectures and Erdős problems. But as a chemist I can see decisive improvements by the frontier models by @AnthropicAI to solve synthesis planning without ANY tools/orchestration.
Opus 5.0 has jumped 90% ! (10 to 19) on our hardest #URSAbench set from Opus 4.8! Amazing progress 🚀! Kudos to @mgdurrant @nc_frey @dagarfield @AlecTPhD 👏


msa-only evals lie.
real uae chats are gulf dialect, english mix, and shorthand. if your agent only passes textbook arabic, it'll flop on day one.
add dialect samples before you ship.
#ArabicAI #UAE #Agents #LLMEvals #DubaiTech

Model choice should be measured, not guessed.
Before switching LLMs, evaluate your agent on:
- completion rate
- hallucinations
- tool accuracy
- latency
- consistency
- cost-performance tradeoff
That is how you build portable AI agents.
https://t.co/b7TO6WnSUP
#LLMEvals #AIAgents #AIEngineering #LLMOps #ProductHunt

Once built, evals integrate everywhere: development, CI/CD, production monitoring, real-time guardrails.
My full talk on this with Cursor breakdown: https://t.co/hA8DTie7yW
Try Truesight: https://t.co/ZCsR99KBZE
#LLMEvals #AIEngineering

🧩 La Pieza Faltante en el Desarrollo de LLMs
¿Cuántas veces ha lanzado una aplicación de IA con un simple "test de sensación" (vibe check) y luego ha terminado jugando a "golpear topos" (whack-a-mole) en producción? 😩
#ShinyConf2025 #LLMEvals #RStats #RAG


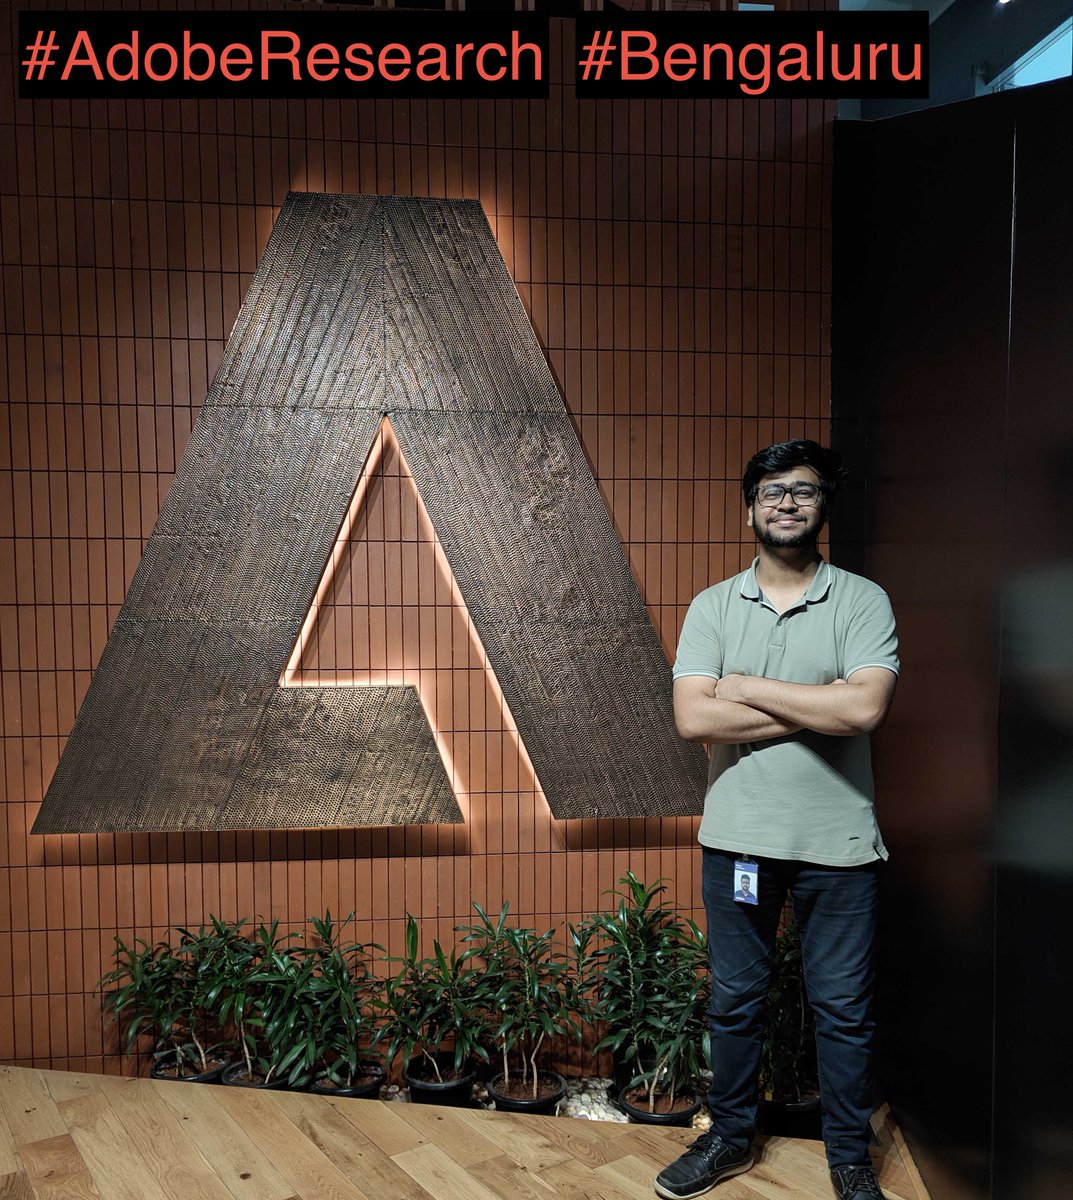
🚀 @KavathekarIshan → @Adobe Research #Bengaluru internship for the next few months! 🎉🎊👏🏽 He is interested in #AgenticAI #MultiAgentSystems #LLMEvals #AISafety. Ishan's Google Scholar profile https://t.co/QAQoikcTSp IK would love to connect! 👋🏾 #IIITHStudentsRock #ProfGiri
Last Seen Hashtags on Sotwe
nolimitt() +filter:native_video
Seen from India
bonnieblue filter:videos
Seen from United Kingdom
bokepsma
Seen from Indonesia
lolafeetgirl
Seen from Belgium
体训
Seen from United States
moancewe diperkosa
Seen from Indonesia
Parbhani Maharashtra
Seen from Belgium
92i beurette
Seen from Netherlands
hijab nude
Seen from Turkey
sleeping() +filter:native_video
Seen from Turkey
Trends for you
Most Popular Users

Elon Musk 
@elonmusk
241.5M followers

Barack Obama
@barackobama
118.8M followers

Cristiano Ronaldo
@cristiano
114.5M followers

Donald J. Trump
@realdonaldtrump
111.8M followers

Narendra Modi
@narendramodi
107.1M followers

Rihanna
@rihanna
98.7M followers

NASA
@nasa
92.3M followers

Justin Bieber
@justinbieber
91.8M followers

KATY PERRY
@katyperry
90M followers

Taylor Swift
@taylorswift13
84M followers

Lady Gaga
@ladygaga
75.5M followers

Virat Kohli
@imvkohli
73.5M followers

Kim Kardashian
@kimkardashian
70.9M followers

YouTube
@youtube
68.8M followers

Neymar Jr
@neymarjr
66.5M followers

Bill Gates
@billgates
65.3M followers

Selena Gomez
@selenagomez
63.1M followers

The Ellen Show
@theellenshow
62.2M followers

CNN
@cnn
61.7M followers

X
@x
60.7M followers