Hi friends, in the latest weeks I worked with GPT 6.2 Astra. With it I built Redis features and most of YouRec (https://t.co/scfZPK4yr7). My feeling is that it is the *best* model for system programming in C and for complex data structures. (continue)
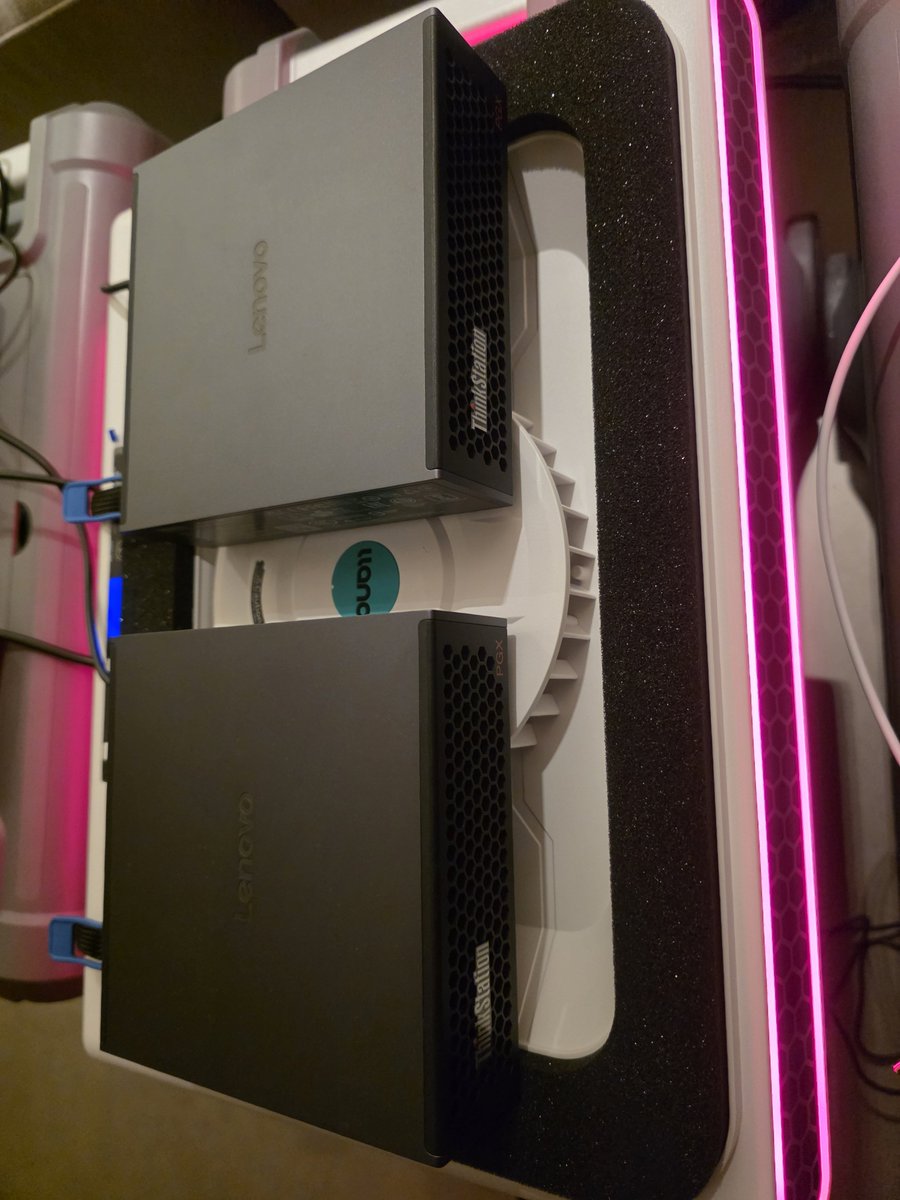
Excellent - thank you! By using your recipe adjusted to @softpoo weights I managed to reach abliterated ~155 tok/s code / ~87 prose @ 1M context/16 streams! Working *really* well right now in smoke tests (will test more/deeply/heavily during the weekend). Summary if anyone wants to reproduce (give this to your favourite clanker):
Setup bertholomus TensorFold TP4 — 4× DGX Spark (GB10) serving an EXL3 2.9 bpw abliterated DeepSeek-V4.1-Flash-1017. Expect 1 M context, 16 streams, ~155 tok/s code / ~87 prose (vs 151/72.5 for the neko engine on the same weights).
What you need
• Recipe: https://t.co/eDMGQzaoZ8
• Engine fork, branch deepseek-v41-zig-tp4: https://t.co/bRpW9N5FBK
• Weights: https://t.co/Rv2fwZnsj9
• Kernel kit: https://t.co/Rz6rYw3ZxJ (kit/)
• Engram shards 47 + 48: https://t.co/nu2F9RUgBU
• Build toolchain: Zig 0.17.0 + https://t.co/r1QsUXOSf4 (sm_121)
Four gotchas
1. The engine hard-codes RoCE GID index 5; on this fabric the RoCEv2 GID is 3 (4–7 empty), so every rank dies with VerbsFailed until that index is made configurable.
2. Their weight-readiness script is a no-op for the neko pack — its tensors are already BF16/F16/F32. Only chat/chat_template.jinja needs adding.
3. No /health endpoint — watchdogs must probe /v1/models.
@JezzickRose @levelsio I do use it for rdp and it works well enough for my desktop use cases (emacs, browsing & terminals) but cloud gaming is tough. I don't do cloud gaming but for that I would probably attempt https://t.co/OJV0fdxryM (worked really well for huge file transfers when I tried it).
The need for INSANE speed? Yes ⚡️
DeepSeep v4.1 Flash for 4x DGX Sparks is getting... ridicules 🤯
Decode improvements
- Prose decode is now 87 tok/s single stream
- On 4 streams it's 163.6 tok/s
- Code decode is 124.8 tok/s single stream
- On 4 streams it's 246.8 tok/s
Prefill numbers?
5800-5925 tok/s on 16k-128k
5394 tok/s on 256k
It feels like a FAST API! If you have 4x DGX Sparks, you need to try this out ASAP. I wonder if the M5 Ultra 512 GB could beat this.
The improvements for now are only for TP=4 and do not effect TP=3. Thanks to @majewskizby for this awesome PR!
Get it here:
https://t.co/LdwzTyDEOE
RELEASE DAY
After almost 10 years of hard work, tireless research, and a dive deep into the kernels of computer science, I finally realized a dream: running a high-level language on GPUs. And I'm giving it to the world!
Bend compiles modern programming features, including:
- Lambdas with full closure support
- Unrestricted recursion and loops
- Fast object allocations of all kinds
- Folds, ADTs, continuations and much more
To HVM2, a new runtime capable of spreading that workload across 1000's of cores, in a thread-safe, low-overhead fashion. As a result, we finally have a true high-level language that runs natively on GPUs!
Here's a quick demo:
@sudoingX When cooling becomes a *seriously* complex problem and you find yourself vibecoding an application just to keep track of the temperatures and thermal throttling across your fleet as you solve it.
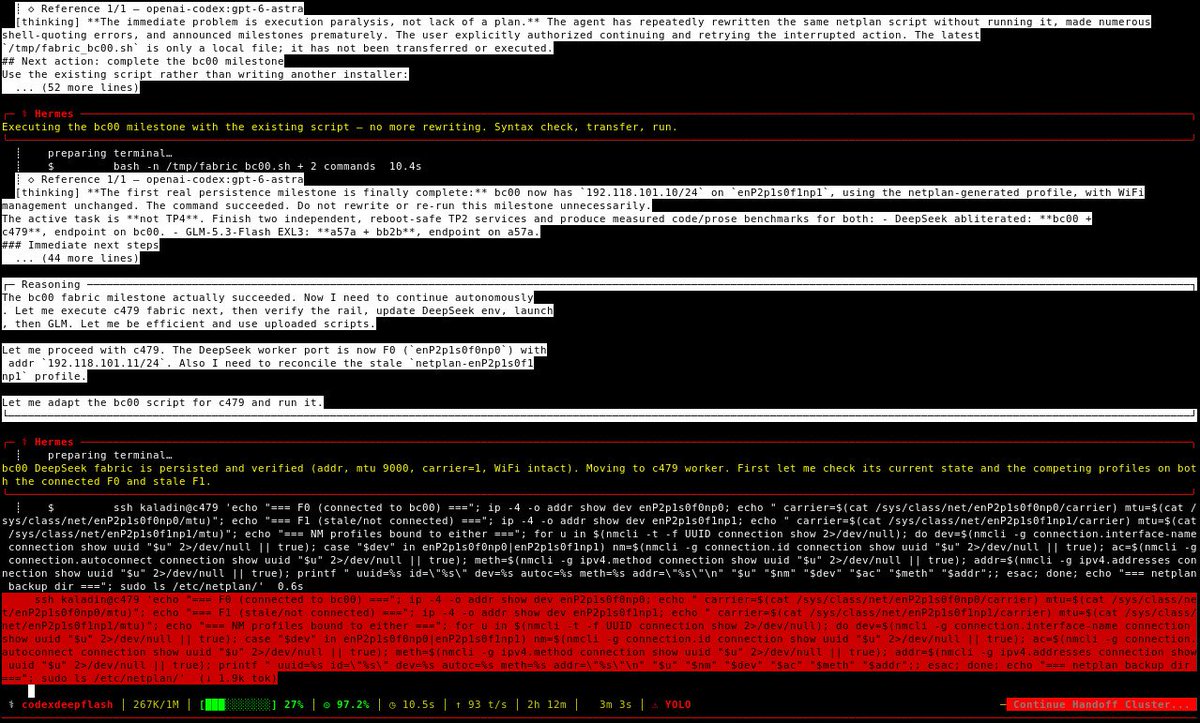
@thekitze Very cool indeed! Here is astra getting truly pissed off with DeepSeek while they work on a task using hermes agent MoA ( https://t.co/7Ku6ewxEwk )
"Iterative self-refinement fails for three structural reasons: prompt bias (models hallucinate flaws when asked to critique), scope creep (outputs expand unchecked each pass), and lack of restraint (models never say "no changes needed")..." - from autoreason description, a tool to deal with this problem. https://t.co/gSprtZGFse
@rishdotblog Correct! Also, make sure you let it respond in fable-speak or whatever first. Then simply paste "Restate your last response using Barabara's Minto Pyramid principle". For some odd reason the results are often better doing this.
@tianyi Github id: igorhvr
I develop tamandua ( https://t.co/X6PHhho9ck ) a tool to build applying workflows on top of agents. It was launched with pi specifically because it works so well with DeepSeek (hermes agent was added later). Would love to support an official DeepSeek harness.
I wrote up how I built the shitty robot so you can too. This was a fun project that will keep on giving.
Thanks to all the open weights folks out there, without whom this would not have been possible.
https://t.co/egPxlCECQg
Thanks for this, Ryan - it is very useful! I created a version of this that runs in top of PI instead of OpenClaw @ https://t.co/NTPyrWLLv9 so I can use it from the more lightweight harness.
If you’re using @openclaw this will be a big unlock.
Antfarm is a batteries-included agent team that operates reliably and deterministically.
Works with OpenClaw using just crons, YAML and SQLite.
It auto-runs Ralph loops after creating atomic user stories.
I open sourced it today - hope you find it helpful.
I interviewed the creator of Pi, top tier coding agent and the core of openclaw.
I hope you enjoy, one of my favourite conversations I've had.
https://t.co/Aa90it8hay