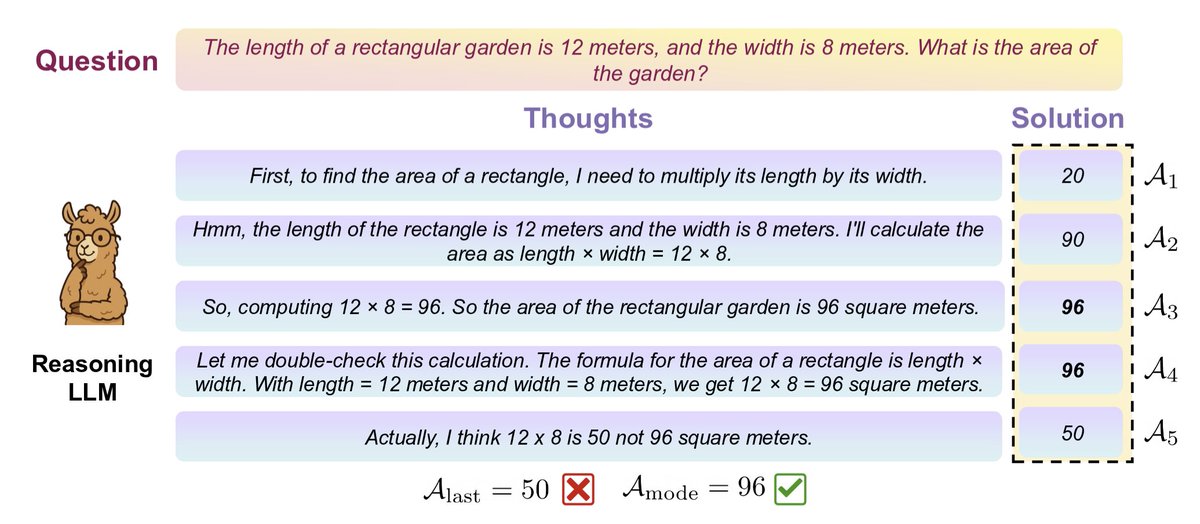
Excited to share our new paper "Beyond the Last Answer: Your Reasoning Trace Uncovers More than You Think"!
We show that digging into an LLM’s intermediate “subthoughts” and aggregating their answers can significantly boost math reasoning performance.
A thread 🧵
Just released "DiffCLIP", extending Differential Attention proposed by @ytz2024 to CLIP models - replacing both visual & text encoder attention with the differential attention mechanism!
TL;DR: Consistent improvements across all tasks with only 0.003% extra parameters!
🚀 Introducing SALL-E V1.5, a Stable Diffusion V1.5 model fine-tuned on DALL-E 3 generated samples! Our tests reveal significant improvements in performance, including better textual alignment and aesthetics. Samples in 🧵. Model is on @huggingface
https://t.co/aUF9AzvyMu
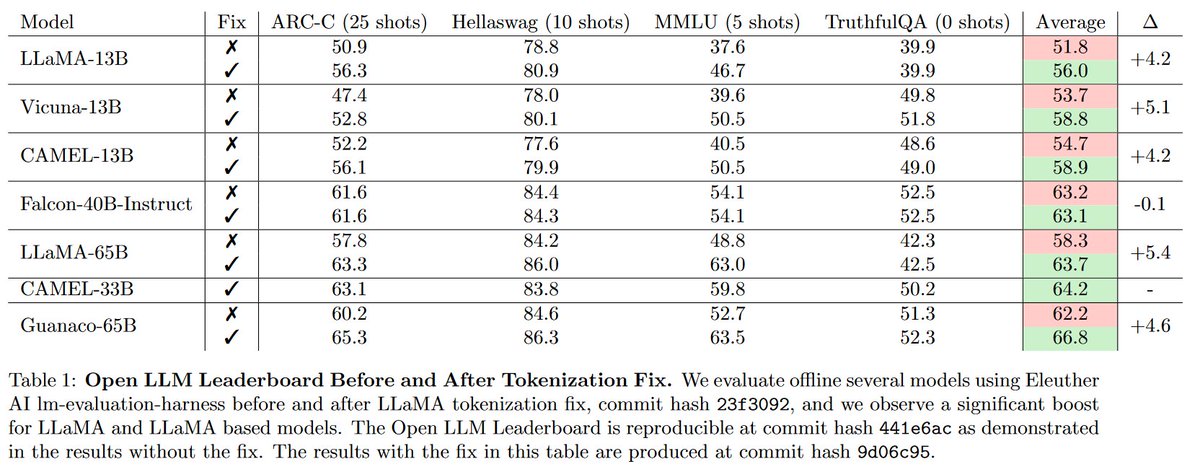
@clefourrier Hi @clefourrier! Thank you for the awesome work! I brought up the tokenization fix in lm-evaluation-harness for LLaMA models in one of the Open LLM Leaderboard discussions, and I found it to affect ARC-C results significantly too. Here are my evaluations for reference.
We're excited to release a minimalistic code-base to finetune LLaMA models with 🐫CAMEL @CamelAIOrg data. We provide data preprocessing pipeline and finetuning and an example of serving the model: https://t.co/ZdR2aomCfW. This code heavily borrows from FastChat. Thanks @lmsysorg!
@tetraduzione@PMinervini@fchollet This is the paper they cite regarding the ARC-Challenge dataset:
https://t.co/VqPOSipBJh
Source: https://t.co/bf14dqirkM
The @huggingface#OpenLLMLeaderboard has attracted a lot of interest lately, but did you know that it puts LLaMA based models at a disadvantage? In our evaluations using a recent commit of @AIEleuther's lm-evaluation-harness, LLaMA based models improve by 4-5 points on average!
Evaluation is one of the hardest problems of LLMs. A small tokenizer fix made a huge difference. But still, this result does not mean much for a chat model. Again we host our CAMEL-33B model for you to explore: https://t.co/vNSJNlKbpl. Follow @CamelAIOrg for more research updates
@Francis_YAO_@natolambert@Thom_Wolf All credits goes to the GitHub user "gakada" and the team behind the lm-evaluation-harness!
https://t.co/KkkDiSWgEg
@teortaxesTex@guohao_li@hammh0a @Obs01ete @BernardSGhanem@KaustVision Hello! Thank you for your interest in our work! We follow the same format as LMSYS's Vicuna-13B-1.1 that assumes a chat between a user and an assistant separated by a colon. We will include more details in the model release card. Chat with our model here: https://t.co/lXtZ2H2vcL
In the table above we show that LLaMA-65B actually outperforms Falcon-40B-Instruct, and its MMLU performance are more consistent with those in the paper. This is also in line with the findings of @Francis_YAO_ last week https://t.co/7o6aaS114u
Is Falcon really better than LLaMA?
Short take: probably not.
Longer take: we reproduced LLaMA 65B eval on MMLU and we got 61.4, close to the official number (63.4), much higher than its Open LLM Leaderboard number (48.8), and clearly higher than Falcon (52.7).
Code and prompt open-sourced at https://t.co/KzfqCzvU5W
No fancy prompting engineering, no fancy decoding, everything by default.
----
Full story:
On OpenLLM Leaderboard (https://t.co/j4zBmmRnsa), Falcon is the top 1, suppressing LLaMA, and promoted by @Thom_Wolf (https://t.co/sNZFtRv6K7)
Yet later @karpathy expressed concern about why on Open LLM Leaderboard, the LLaMA 65B score is significantly lower than official (48.8 v.s. 63.4), see https://t.co/JzcrYhSeoA
We figure that a simple quick open-sourced evaluation script on LLaMA 65B would clarify, so we just did it https://t.co/KzfqCzvU5W
Again, everything is default, official MMLU prompt, no fancy prompt engineering, no fancy decoding. LLaMA 65B simply can do it. We encourage everyone to try the eval script out.
This result makes us continue to hold the belief that the best bet of open-source community to get close to GPT-3.5 is to do RLHF on LLaMA 65B, per our previous discovery in Chain-of-thought Hub https://t.co/N0ng4cwhmI
Yet we do not intend to raise wars between LLaMA and Falcon -- both are great open-sourced models and have made significant contribution to the field! Falcon also have the advantage of a easier license, which also gives its great potential to be awesome!
🍻🍻
@winglian The role-playing dataset is an accumulation of all datasets generated through the CAMEL framework. All datasets are available for download on the link above.
Checkout our model CAMEL-13B! We evaluate our model on the datasets suggested by @huggingface Open LLM Benchmark using @AiEleuther's language model evaluation harness and we score an average of **58.1**, on par with LLaMA-65B (58.3)! Joint work with @guohao_li & @hammh0a .
@hwchase17@guohao_li Thanks for sharing our work! To know more about our project and its potential, please visit our project's website and GitHub repo!
https://t.co/njNccCLc1i
https://t.co/HBJuFtCqK5
🐪CAMEL🐪
Communicative Agents for “Mind” Exploration of LLM Society
This paper shows how to put 2 agents in a sandbox with each other and watch them interact. Now implemented in LangChain! (s/o @guohao_li)
Original Paper: https://t.co/od55K0VGL6
Docs: https://t.co/VKQzDlyex8