@MiaAI_lab@InferenceEx@JensenHuang individual security needs. The goal is an open protocol for industry to steer us towards a defense in depth approach to the software supply chain ensuring that only via a 0 day kernel exploit on MacOS or Linux can an attacker snoop on the plaintext.
@MiaAI_lab@InferenceEx@JensenHuang With the AI rollout, average consumers are getting a taste via Apple Silicon, Nvidia DGX Spark, etc. of what the roadmap for semiconductors have in store for humanity. Leveraging the community power of local LLMs, we can experience dramatically cheaper prices while meeting our
@usr_bin_roygbiv I believe @JensenHuang is quoted as saying that a data center’s cost can be paid back in a year. I’m currently building something to equalize the information asymmetry and empower consumers. It sounds to me like token selling is maximizing its margin on individuals,SMEs,big corps
@TheShortBear@ChatGPT May I ask what your approach is towards building these large scalable systems? Please correct me if I’m wrong, but my assumption is that you’re a trader asking the AI to be your SWE and build everything for you. How to become confident that you’re iterating on best practices?
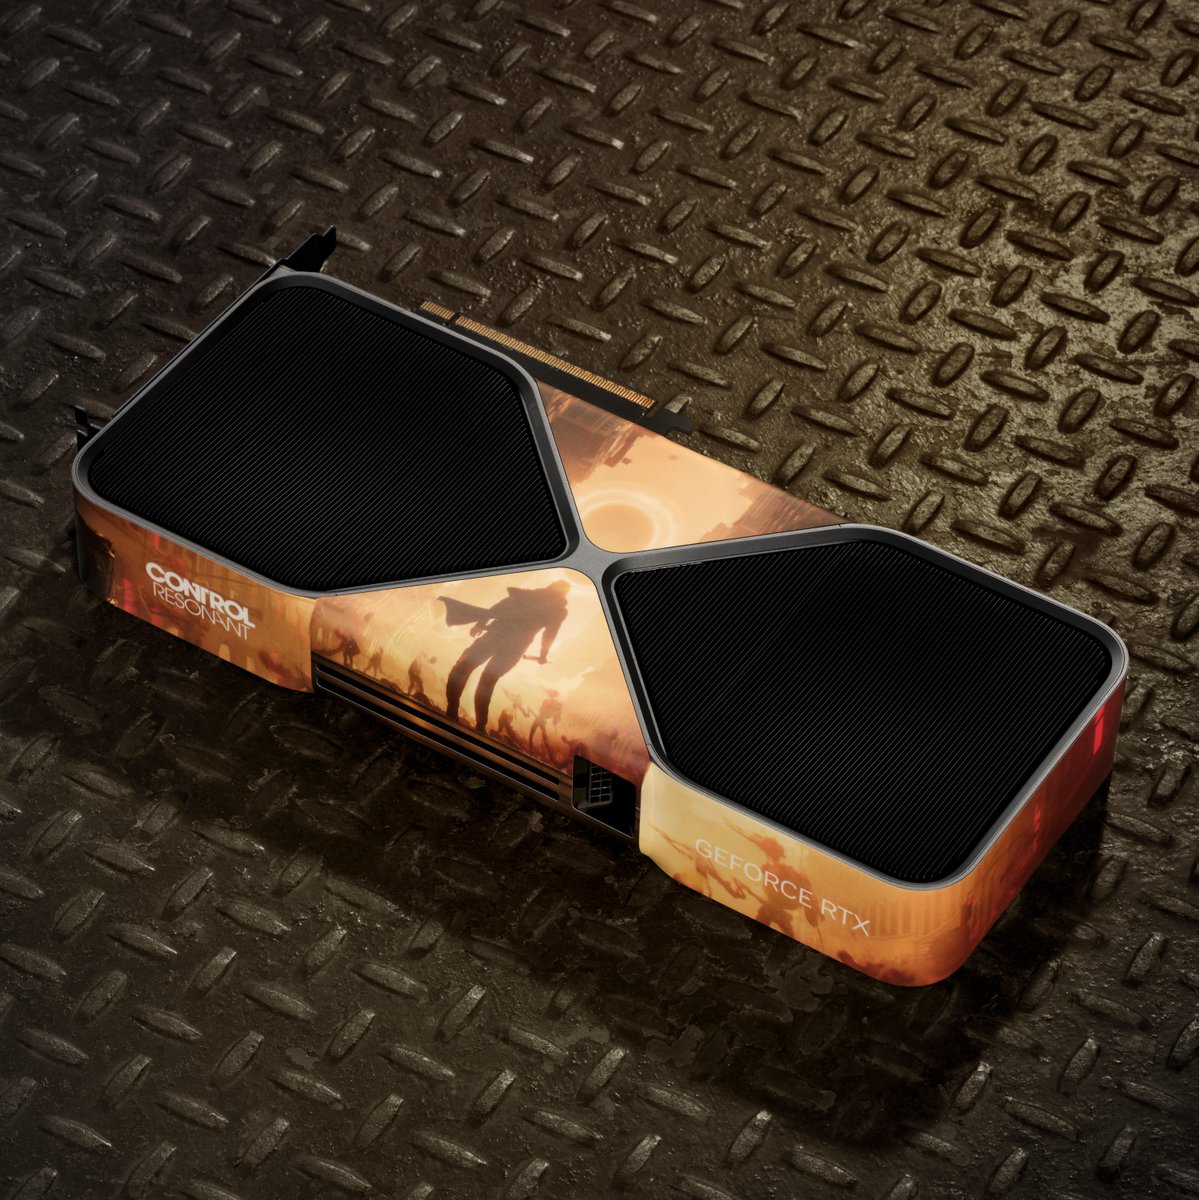
We're giving away a CONTROL Resonant custom wrapped NVIDIA GeForce RTX 5080 to celebrate its official release with #RTXON.
To enter:
🟢 Share this post
🟢 Comment #RTXON
T&Cs: https://t.co/Mbf7w3j1q3
@Baxate Hi Baxate, may you please share your thoughts on an open protocol for confidential computing with consumer hardware (e.g. DGX Spark, Apple Silicon, etc.)? With local LLM’s expanding, I believe the industry needs to consolidate on definitions for safely sending prompts online.
@Kurcide Awesome work, are you interested in collaborating on an open source confidential computing protocol for consumer hardware? I’ve done some work with Apple Silicon, and I’ve been looking to expand to Nvidia. TLDR: ensure hardware encrypted processing of prompts for the community.
Thanks everyone for participating. Did some AI statistics and it seems that the sample size is not too large. Does anyone have feedback? Is it because people are using different models (e.g. people doing big models and heavy tasks while others use small models for simple ones)?
Hi all, looking to learn from the community what costs they’re seeing from running these agents. May I please get some feedback to learn how much others are paying on a monthly basis to run your Hermes setup?
@gregosuri@TheAhmadOsman Hi Greg, what are your thoughts on an open protocol for local confidential compute/inference. I think across Apple Silicon, Nvidia, AMD, Intel, etc., there’s an increasing need to have secure AI workloads at the hardware level.
@TheAhmadOsman Hi Ahmad, may I please have your thoughts on an open protocol for confidential inference? For example given your hardware setup of I’m guessing Linux + Nvidia GPUs, how can the community align on a secure way (at the hardware level) to run inference on other user’s prompts.
@alexandr_wang Please allow users to use their custom LLM endpoints. We should be able to explore the world of agents across various LLM backends. As a proponent of open source I think you’d best understand.