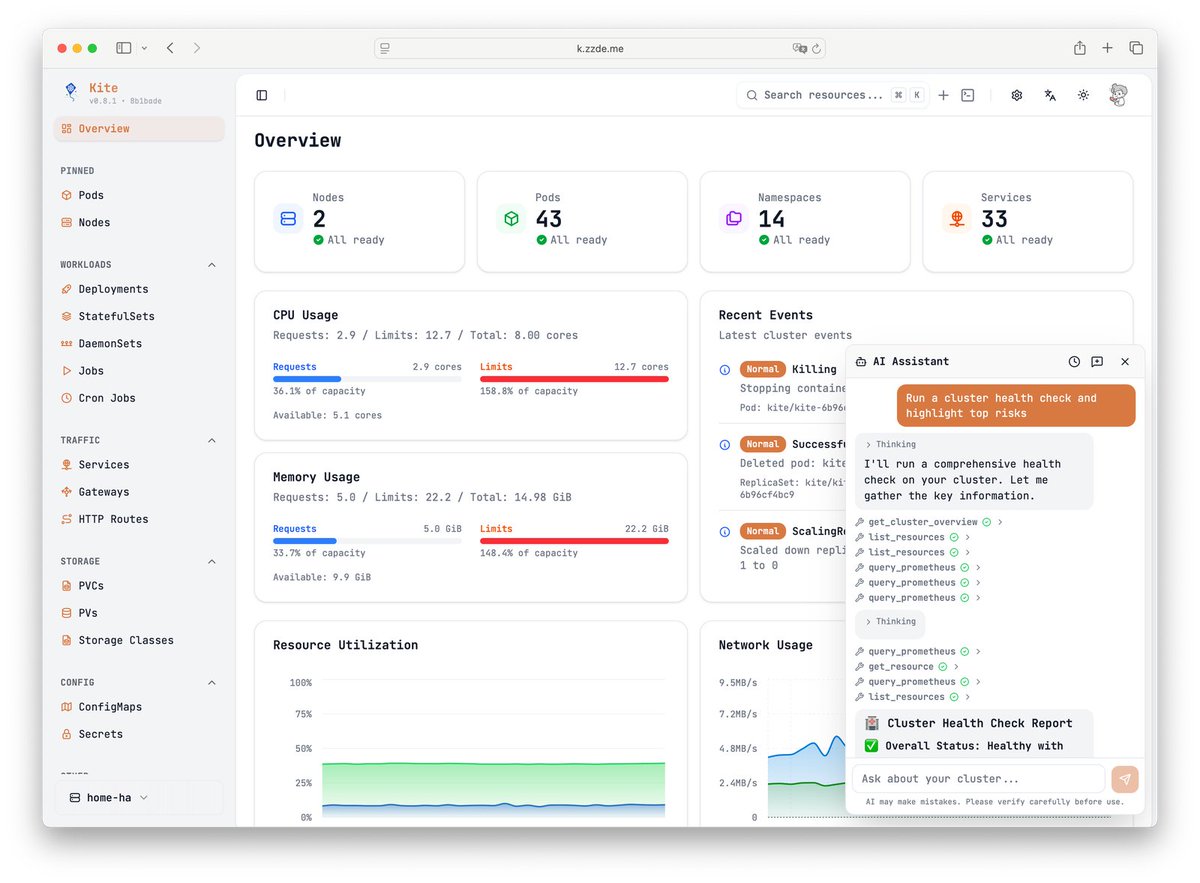
Docker Compose will become a first-class citizen in Kiri 0.2.2.
• See your Compose file as a visual workflow: every service and how they connect
• Edit your Compose file right in Kiri
• Read logs as a group: web, db and api side by side in one view
Kiri is the modern container runtime: faster, and lighter on CPU and memory than Docker Desktop, OrbStack and Colima.
https://t.co/1WQaGOpZyA
https://t.co/v5LqpfeKzq
Crazy...this is Kubernetes moment for AI Agents.
Run millions of agents on Kubernetes. Idle agents go to sleep and wake up in under 500ms. 10x more agents on the same hardware.
100% Opensource.
https://t.co/s3LFYZX4mP
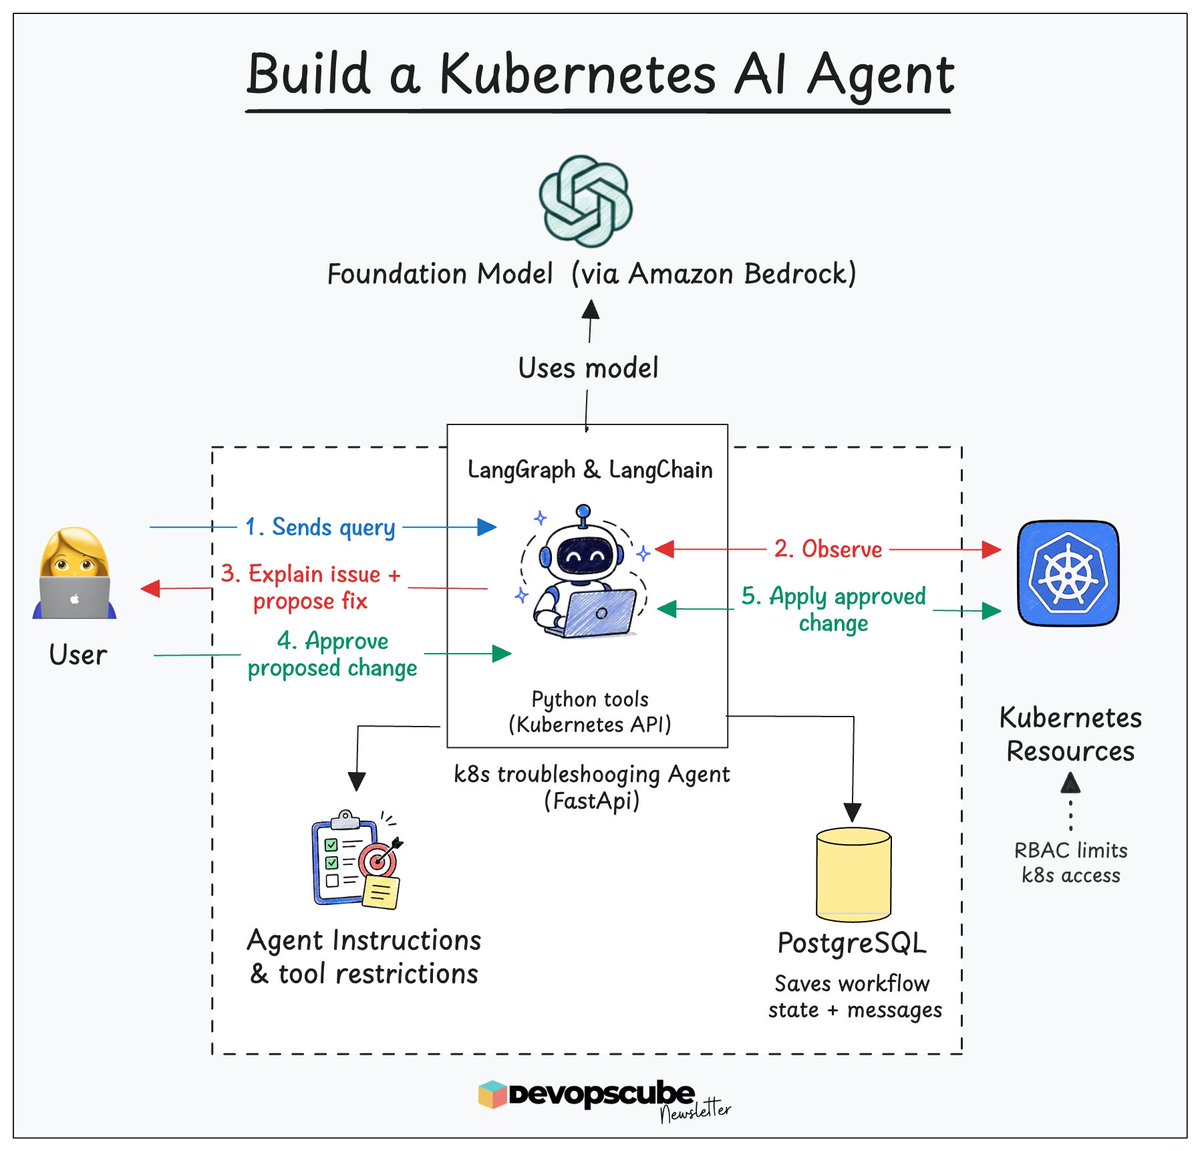
Build a Kubernetes AI Agent (hands-On) 🚀
In the previous AI Agent architecture guide,
We covered the fundamental concepts of an AI agent.
You can put those concepts into practice using the hands-on guide.
It covers the following.
- Understanding Agent code structure
- Build an Agent from scratch using LangGraph and LangChain
- Choosing the right AWS Bedrock models for the agent
- Deploy the Agent on AWS EKS
- Understand the end-to-end agent request flow
You will see how the agent loop, tools, state, and human approval work in a real setup.
𝗗𝗲𝘁𝗮𝗶𝗹𝗲𝗱 𝗚𝘂𝗶𝗱𝗲: https://t.co/yPuSewV4K8
We want to make one thing clear
The goal here isn’t to say every DevOps engineer should build their own AI agents.
However, from an infrastructure perspective, you should understand,
Agent Tool access, Context, Security and Observability.
Found it useful?
♻️ Repost and share it with the community 🙂
#kubernetes #aiops #devops
How to build an AI harness around your coding agent in four steps:
1. Context and memory (sessions, state)
2. Tools and workflows (MCP, ADK)
3. Sandboxes and prompt injection defense
4. Evals (code, LLM judge, human)
Watch the crash course → https://t.co/pOlUGGg7Ux
DPF is a Kubernetes-native framework for provisioning and orchestrating NVIDIA BlueField-3 DPUs
It abstracts DPU management and offloads networking and storage workloads from host servers to Linux-based arm64 DPUs using the DOCA software stack
➤ https://t.co/otg6x13ppY
SnowOps Labs is a Kubernetes practice lab that builds a local cluster, injects realistic failures, and grades your fixes through guided scenarios and incidents
➤ https://t.co/fzfEYtMOVd
Fine-tune LLM agents without fine-tuning LLMs!
Memento is a memory based continual learning framework for LLM agents that lets them learn from experience over time without touching model weights.
It maintains a Case Bank of past trajectories including tasks, step sequences, tool usage, and outcomes.
When a new task comes in, the agent plans and acts by pulling from similar past cases instead of starting from zero.
Memento follows a planner and executor setup:
1. The Planner (an LLM) breaks the task into subtasks, retrieves relevant cases, and chooses a plan.
2. The Executor runs those subtasks using tools like search, code execution, or document processing through the Model Context Protocol (MCP), then logs the results back into memory.
Key Features:
• Memory based continual learning that improves agents through stored experience
• Planner and executor architecture with case based reasoning for task decomposition
• Unified tool ecosystem for search, code execution, document processing, media analysis and more
• Learning without weight updates by retrieving and reusing relevant past cases
• Strong results on long horizon and out of distribution tasks in reported benchmarks
It is 100% open source.
Link to the GitHub repo in the comments!
Knowledge Catalog, Google Cloud's universal context engine, turns knowledge into shared business context so agents answer and act with higher accuracy and trust ↓
Kitesurf, our experimental browser engine for AI agents, is now open source. Inspect the code, run it locally, or deploy your own instance on Cloudflare Workers. https://t.co/gZeSsQzmr2
«Todo el código es basura, excepto el mío». Lauren Tan, ingeniera de GrokBot en SpaceXSI.
En el AI Engineer Code Summit acaba de mostrar toda su configuración de desarrollo.
Cada error de un agente se convierte en una regla de linting, no en un prompt. Los agentes verifican su propio trabajo con vídeos, capturas de pantalla y tests.
¿El resultado? 3.000 PRs llevadas a producción en un mes.
Su base de código está ahora tan limpia que los agentes fusionan la mayoría de sus propias PRs.
Mira esto antes de automatizar cualquier cosa.
𝗦𝗟𝗢 𝘃𝘀 𝗦𝗟𝗜 𝘃𝘀 𝗦𝗟𝗔.
An 𝗦𝗟𝗜 (Service Level Indicator) measures what’s actually happening in your system; like request latency, error rate, or uptime. It’s the raw signal that tells you how your service is performing.
An 𝗦𝗟𝗢 (Service Level Objective) defines the acceptable range for an SLI, like “99.9% of requests succeed within 200ms.” It’s what your team aims to achieve to maintain reliability.
An 𝗦𝗟𝗔 (Service Level Agreement) is a formal contract with users or customers, often tied to penalties if targets aren’t met. It defines the consequences, not just the goal.
But a service isn't the only thing teams hold to a target.
A roadmap is a target too: which initiatives get the people, time and budget. Most roadmaps have no SLI behind them. People move, priorities shift, AI agents take on work without status updates, and the gap between plan and reality grows quietly.
Measuring that gap starts with the data work already produces. Tempo Loop connects time, capacity, spend and financials into one continuously updated view of whether the work still matches the strategy that funded it, for human and AI work alike.
𝗘𝘅𝗽𝗹𝗼𝗿𝗲 𝗧𝗲𝗺𝗽𝗼 𝗟𝗼𝗼𝗽 → https://t.co/zB2PlJ4Ouw
What else would you add?
——
♻️ Repost to help others learn and grow.
🙏 Thanks to @TempoHQ for sponsoring this post.
➕ Follow me ( Nikki Siapno ) to improve at AI and system design.