Introducing Contrastive Language Model (CLM): an ultra-fast System One Model trained with a contrastive learning objective that connects states and actions.
CLM-8B is pre-trained on internet-scale data and delivers up to 9× faster inference than Jev ⚡ while achieving comparable performance across computer-use, gaming, and tool-calling tasks.
With lightweight fine-tuning, CLM-8B sets a new SOTA on challenging agentic coding benchmarks, such as DeepSWE (81.6%) and Terminal-Bench 2.1 (87.6%). In contrast, Jev fails to serve as an effective verifier for these long-horizon tasks.
We also build an efficient training and serving infra for CLMs by disaggregating states and actions, allowing their embeddings to be cached and reused independently. This substantially reduces inference latency in settings where the state evolves continuously while the action set remains fixed.
Finally, we establish scaling laws for CLMs and show that the test contrastive loss decreases predictably as a power law in training compute, model size, and dataset size.
📄 Blog: https://t.co/zwi9JOHKGx
💻 Code: https://t.co/rsHRYCGR8I
🗣️ Discord: https://t.co/Uqtdefvo3J
🤗 Data & Models: https://t.co/wdSWGGO3hu
More details on CLM’s architecture, data recipe, and scaling laws in the thread below 🧵
#NJ#Oldbridge have been now extorting its residence by increasing property taxes by 25%+. I wonder we should go back to smaller houses or rentals. Median income in old bridge is $106K. #propertytaxes
Newark airport #ewr#unitedairlines we are still waiting on the runway for the flight to take off. #ua1190 this is horrible and now flight smells of gasoline due to taxing
Promising. Everyone should hope that we can throw away tokenization in LLMs. Doing so naively creates (byte-level) sequences that are too long, so the devil is in the details.
Tokenization means that LLMs are not actually fully end-to-end. There is a whole separate stage with its own training and inference, and additional libraries. It complicates the ingest of additional modalities. Tokenization also has many subtle sharp edges. Few examples:
That "trailing whitespace" error you've potentially seen in Playground? If you end your (text completion API) prompt with space you are surprisingly creating a big domain gap, a likely source of many bugs:
https://t.co/f2PBaw2iA8
Tokenization is why GPTs are bad at a number of very simple spelling / character manipulation tasks, e.g.:
https://t.co/XR3d5g4uwp
Tokenization creates attack surfaces, e.g. SolidGoldMagikarp, where some tokens are much more common during the training of tokenizer than they are during the training of the GPT, feeding unoptimized activations into processing at test time:
https://t.co/y72eaIeRrP
The list goes on, TLDR everyone should hope that tokenization could be thrown away. Maybe even more importantly, we may find general-purpose strategies for multi-scale training in the process.
@marktenenholtz If you have small dataset, go with a naive rule based assumptions to see how things are working. Benchmark it and create a test data with human annotations. Now bring in important models and do cost benefit analysis. Not just benefit 😊 keep improving the test data
This is the worse AI will ever be.
The Music industry is completely gonna be turned upside down.
Every artist will have their own custom trained model, and Spotify will own this space why?
🧵 A thread
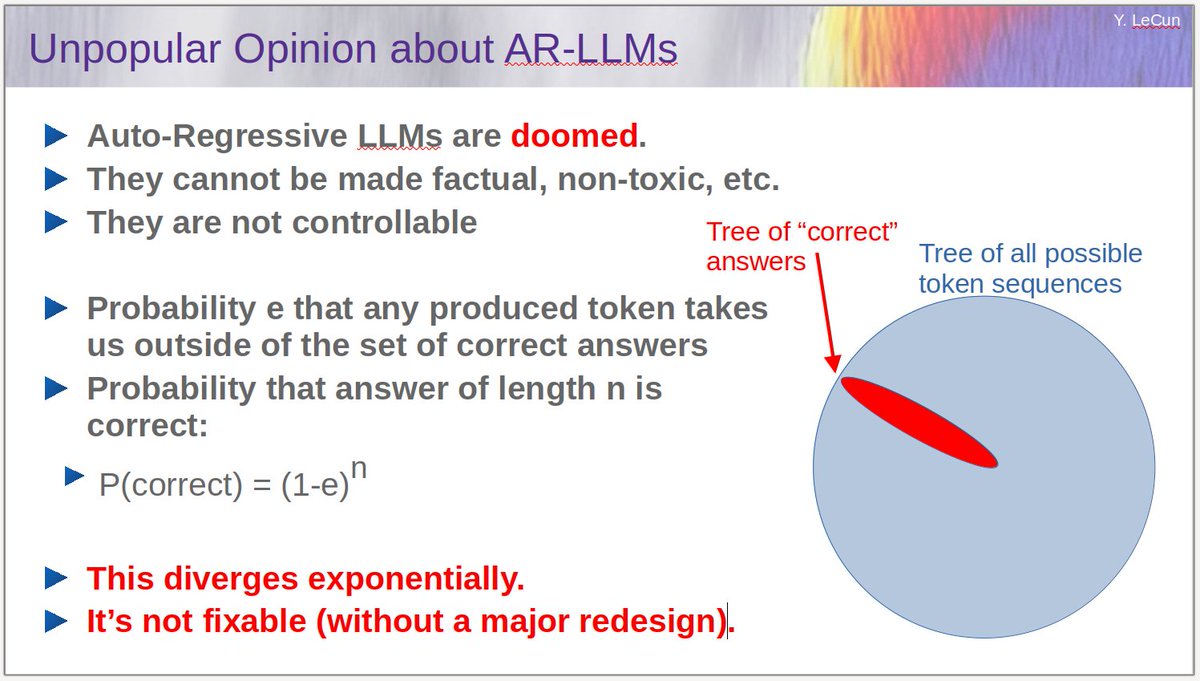
I have claimed that Auto-Regressive LLMs are exponentially diverging diffusion processes.
Here is the argument:
Let e be the probability that any generated token exits the tree of "correct" answers.
Then the probability that an answer of length n is correct is (1-e)^n
1/
🤯🤯Well this is something else.
GPT-4 passes basically every exam. And doesn't just pass...
The Bar Exam: 90%
LSAT: 88%
GRE Quantitative: 80%, Verbal: 99%
Every AP, the SAT...
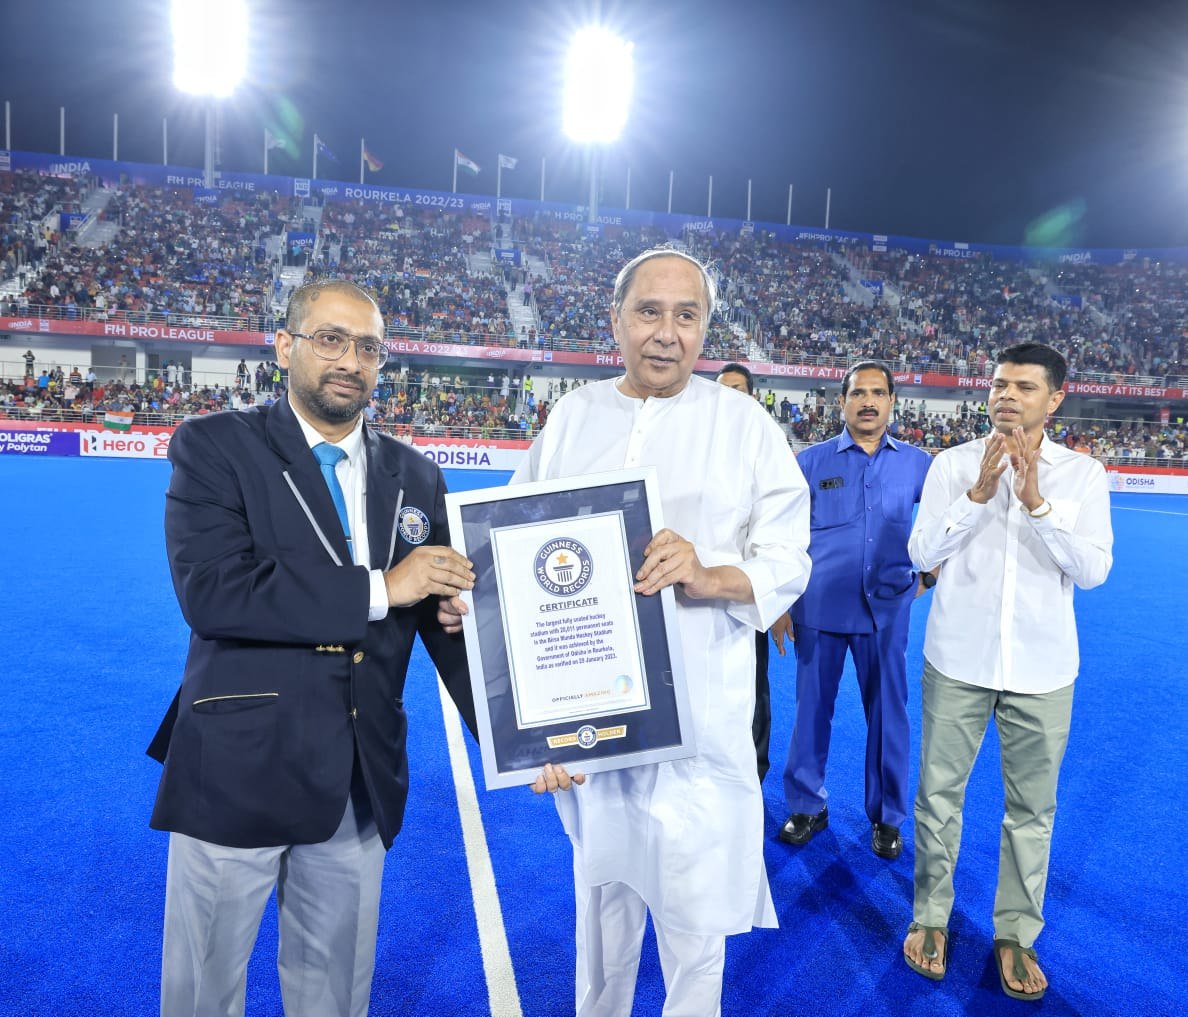
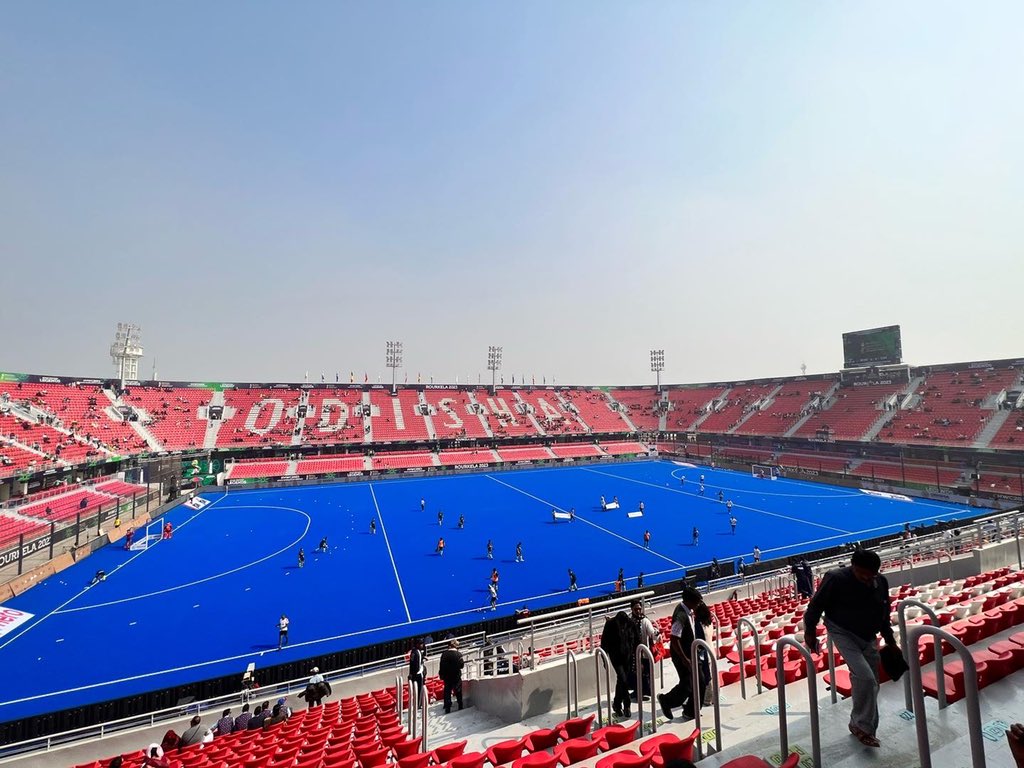
CM @Naveen_Odisha awarded with certificate of recognition from Guinness Book of World Records (@GWR) for #BirsaMundaHockeyStadium, Rourkela being world's largest fully seated hockey stadium. Built in record 15 months, the 20,011 seat stadium is now a benchmark in hockey infra.
@Saboo_Shubham_@OpenAI Again a case of sampling bias and depends on who is annotating examples. Glad you didn’t tag Indian news channels. It could become the next sensation on AajTak. 😂 Jokes apart I am trying to highlight a reasonable issue here.
Heard this work from Yu-Xiang Wang of UCSB https://t.co/c9VJswQIZm at SLowDNN. By far the best work known revealing the true role of deep networks in regression, by integrating different pieces of the puzzle: classic splines, weight decay, depth, sparsity, dictionary learning.