🔥Want to try it or build with it? Check out the code and model weights:
💻 GitHub: https://t.co/AuHSkoKkn1
🤗 Hugging Face: https://t.co/gM4IaGoWhQ
🔬Technical Report: https://t.co/vajUwxLNM8
🚀Meet Kandinsky Avatar 1.0 — an open-source AI model that turns a single image and an audio track into a realistic talking video avatar.
It generates synchronized lip movements, natural facial expressions, head movements and gestures.⚡
⚡The model supports videos up to 1 minute at 24 FPS and comes in Pro and lightweight Lite versions.
Released under the MIT license, it can be used commercially. A great opportunity for developers to build on top of it!🚀
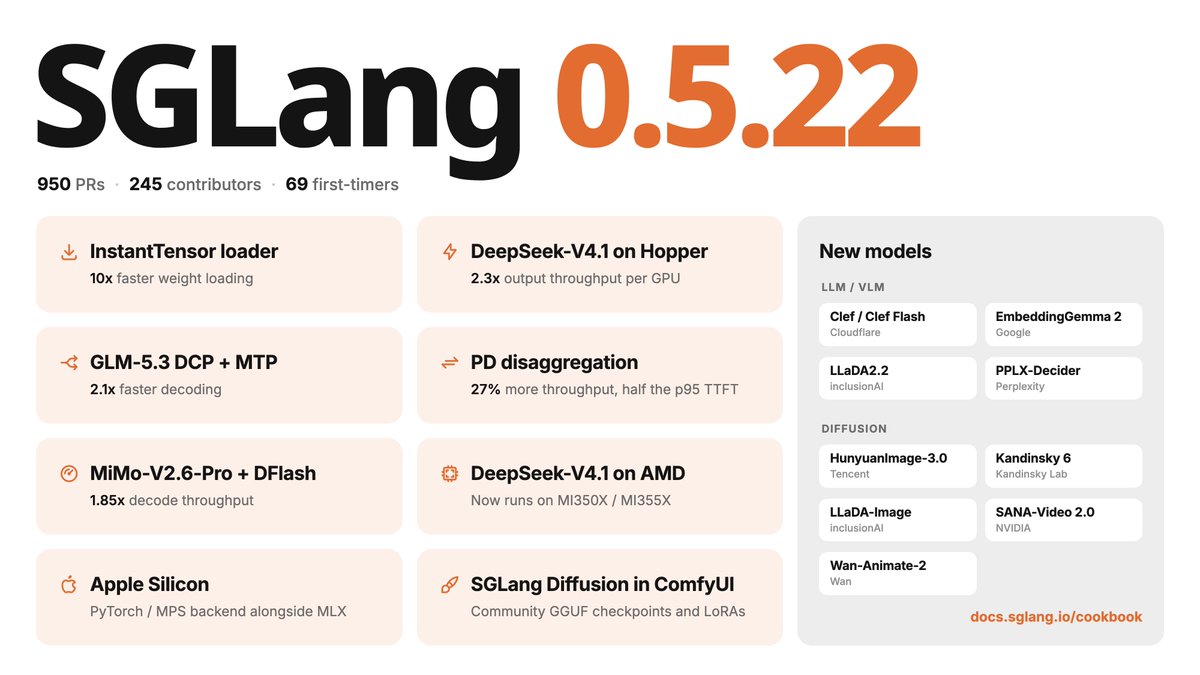
SGLang v0.5.22 is out! 950 PRs from 245 contributors, including 69 new contributors 🧡
Some of our favorite updates:
- InstantTensor brings up to 10x faster weight loading
- DeepSeek-V4.1-Flash gets up to 2.3x output token throughput on Hopper
- Up to 2.1x faster decoding on GLM-5.3, with decode context parallelism with MTP
- PD disaggregation gets up to 27% more throughput and half the p95 TTFT on agentic tasks
- MiMo-V2.6-Pro gets 1.85x decode throughput with DFlash
- Apple Silicon Macs can now use the standard PyTorch/MPS backend alongside MLX
- SGLang Diffusion now supports community GGUF checkpoints and LoRAs on ComfyUI
New models include Clef / Clef Flash, PPLX-Decider v1 / v1.1, EmbeddingGemma 2, LLaDA2.2, HunyuanImage-3.0-Instruct, Kandinsky 6, SANA-Video 2.0, and more.
Full release notes: https://t.co/QnVEsPKith
Kandinsky 6.0 is now live on fal
- Pro for cinematic, high-fidelity generation
- Lite for fast, low-cost iteration
- Native synchronized audio
- Built-in upscaling, plus standalone VSR and VSR Lite for video super-resolution
Day-0 support for Kandinsky 6.0 Video in vLLM-Omni: https://t.co/gtjWU6I8eT!
Great work from @kandinskylab_ai: 5-second video clips with synchronized audio and lip-sync, from text or image inputs. Open code and checkpoints under MIT, with inference support ready at launch.
New MIT open-weight video (+audio) model from Kandinsky 🔥
Comes in 6 different variants, balancing speed, memory, & quality. Has two super-res checkpoints, too!
Enjoy the day0 integration in Diffusers 🤗
SGLang now supports Kandinsky 6.0 Video from @kandinskylab_ai! It generates video and synchronized audio together from text or an image. Speech, sound, and lip-sync come out of a single model.
> 2 sizes: Lite (3B) and Pro (29B) with text-to-audio-video and image-to-audio-video modes
> Built-in super-resolution up to 1920×1080
> Dual-stream CrossDiT: a pretrained video stream and a new audio stream, linked by bidirectional cross-attention
Run it with SGLang Diffusion:
🤝 Every integration opens new doors for the community. Thank you, @sgl_project, for supporting Kandinsky 6.0 Video in SGLang and helping more developers build with our model!
SGLang now supports Kandinsky 6.0 Video from @kandinskylab_ai! It generates video and synchronized audio together from text or an image. Speech, sound, and lip-sync come out of a single model.
> 2 sizes: Lite (3B) and Pro (29B) with text-to-audio-video and image-to-audio-video modes
> Built-in super-resolution up to 1920×1080
> Dual-stream CrossDiT: a pretrained video stream and a new audio stream, linked by bidirectional cross-attention
Run it with SGLang Diffusion:
Announcing support for Kandinsky 6 in FastVideo 🚀
Text/image → video with synchronized audio, in two sizes:
- Pro · 30B
- Lite · 3B
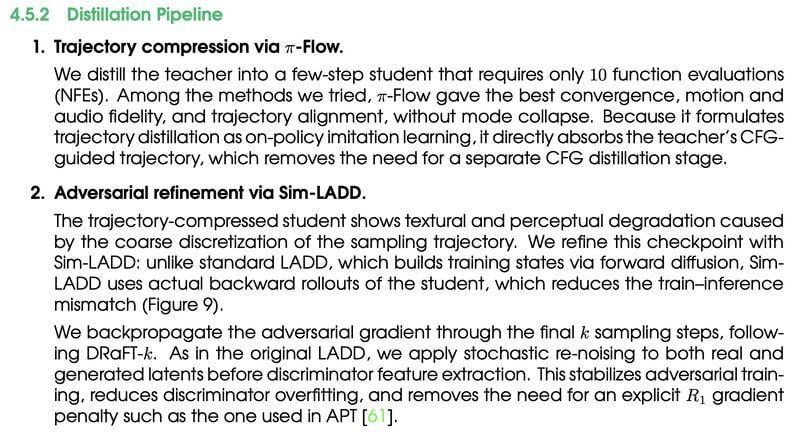
Each has a 10-step distilled pi-Flow version, plus video super-resolution up to 4x.
Recipes 👇
https://t.co/fJg8cyBK2k
Great work by @kandinskylab_ai team for open sourcing the models!
⚡ Kandinsky 6.0 Video meets FastVideo! Thank you, @haoailab, for adding our model to the framework and giving the community another way to experiment with synchronized video and audio generation. Great to see the ecosystem growing!
Announcing support for Kandinsky 6 in FastVideo 🚀
Text/image → video with synchronized audio, in two sizes:
- Pro · 30B
- Lite · 3B
Each has a 10-step distilled pi-Flow version, plus video super-resolution up to 4x.
Recipes 👇
https://t.co/fJg8cyBK2k
Great work by @kandinskylab_ai team for open sourcing the models!
🤗 Open source moves faster when people like @RisingSayak get involved. Thank you for the day-0 integration and for helping our model reach more builders and researchers!
New MIT open-weight video (+audio) model from Kandinsky 🔥
Comes in 6 different variants, balancing speed, memory, & quality. Has two super-res checkpoints, too!
Enjoy the day0 integration in Diffusers 🤗
Day-0 support for Kandinsky 6.0 Video in vLLM-Omni: https://t.co/gtjWU6I8eT!
Great work from @kandinskylab_ai: 5-second video clips with synchronized audio and lip-sync, from text or image inputs. Open code and checkpoints under MIT, with inference support ready at launch.
🙌 Thanks @fal for bringing Kandinsky 6.0 Video to your platform! We're excited to see what the community creates. Try it on fal and share your results!
Kandinsky 6.0 is now live on fal
- Pro for cinematic, high-fidelity generation
- Lite for fast, low-cost iteration
- Native synchronized audio
- Built-in upscaling, plus standalone VSR and VSR Lite for video super-resolution
📄 Our Kandinsky 6.0 Video technical report covers all the details: architecture, training, inference, and benchmarks. Dive in, and give the paper a like on Hugging Face!
https://t.co/On8gW7hwJi
🚀 Kandinsky 6.0 Video is open source! Meet Lite (3B) and Pro (29B) for video generation with synchronized audio. Code and weights are released under MIT. Try them out and share what you create!
https://t.co/iBAjhU3wHJ
🎬 Try Kandinsky 6.0 Video Pro Distill for free on Hugging Face! Turn a prompt or an image into a 5-second video with synchronized audio. We'd love to see what you create!
https://t.co/3fM3VS8QTE