Half a year worth of work to finally show Midpoint Models to the world!
Thanks to my senior colleagues I became a part of this awesome work!
Meet a new 1-step generation paradigm!
Flow Matching connects two distributions.
Can a one-step generator learn from the flow between its own samples and real data?
Meet Midpoint Generative Models (MGM), our new training framework built on this idea.
Here’s how. 🧵
Flow Matching connects two distributions.
Can a one-step generator learn from the flow between its own samples and real data?
Meet Midpoint Generative Models (MGM), our new training framework built on this idea.
Here’s how. 🧵
@dummerspast39 Hope it gets shipped soon!
Congrats, GigaChat team 💪💪💪!
Speaking of Russian Models! Checkout Kandinsky if you want Image, Video and Audio (https://t.co/XtS8YXXXfb) generation!
Announcing support for Kandinsky 6 in FastVideo 🚀
Text/image → video with synchronized audio, in two sizes:
- Pro · 30B
- Lite · 3B
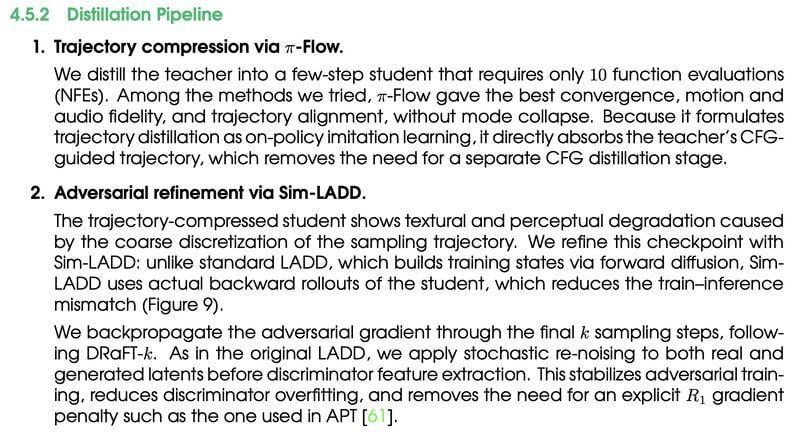
Each has a 10-step distilled pi-Flow version, plus video super-resolution up to 4x.
Recipes 👇
https://t.co/fJg8cyBK2k
Great work by @kandinskylab_ai team for open sourcing the models!
New MIT open-weight video (+audio) model from Kandinsky 🔥
Comes in 6 different variants, balancing speed, memory, & quality. Has two super-res checkpoints, too!
Enjoy the day0 integration in Diffusers 🤗
Day-0 support for Kandinsky 6.0 Video in vLLM-Omni: https://t.co/gtjWU6I8eT!
Great work from @kandinskylab_ai: 5-second video clips with synchronized audio and lip-sync, from text or image inputs. Open code and checkpoints under MIT, with inference support ready at launch.
Day-0 support for Kandinsky 6.0 Video in vLLM-Omni: https://t.co/gtjWU6I8eT!
Great work from @kandinskylab_ai: 5-second video clips with synchronized audio and lip-sync, from text or image inputs. Open code and checkpoints under MIT, with inference support ready at launch.
Kandinsky 6.0 is now live on fal
- Pro for cinematic, high-fidelity generation
- Lite for fast, low-cost iteration
- Native synchronized audio
- Built-in upscaling, plus standalone VSR and VSR Lite for video super-resolution
Kandinsky 6.0 is now live on fal
- Pro for cinematic, high-fidelity generation
- Lite for fast, low-cost iteration
- Native synchronized audio
- Built-in upscaling, plus standalone VSR and VSR Lite for video super-resolution
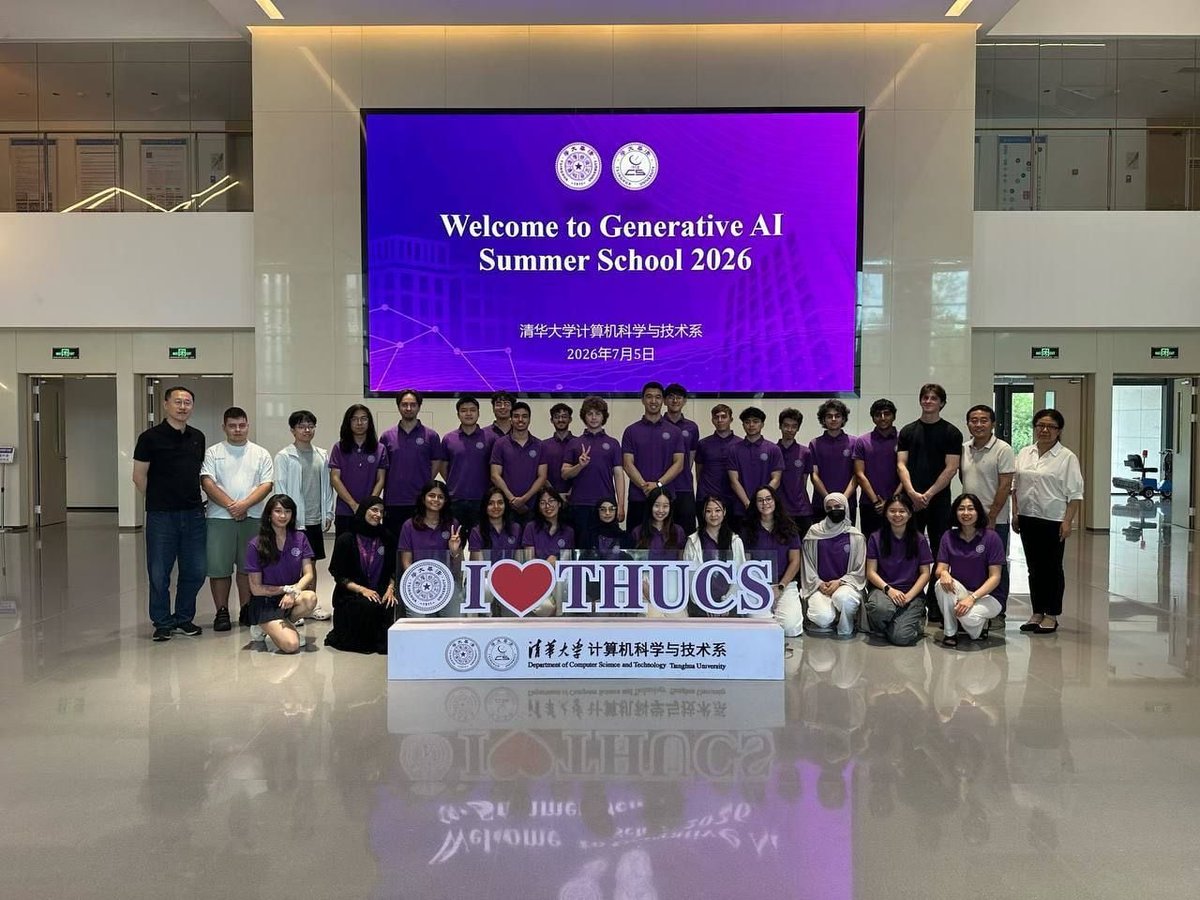
I had great time at the Tsinghua GenAI Summer School 2026!
Got great lectures from the co-founder of https://t.co/0X7rQ3g1tI, professor Tang Jie and Vidu co-founder professor Jun Zhu!
#Tsinghua#THU#Zai#Zhipu#GenAI#AI
Excited to see the new open-source Helios model for real-time long video generation released 🚀
Proud that Kandinsky 5.0 Video models are recognized by peers for top-tier quality and as leading non-autoregressive open-source models.
https://t.co/INa29HQkgd
Kandinsky 5 Video Pro just hit SOTA among open-source models on RISE-Video🔥
RISE-Video benchmarks reasoning alignment, temporal consistency, physical realism & visual quality🚀
https://t.co/eA9hzzfvUE
Looking for a PhD position!
Hi everyone!
I am currently a Research Engineer at Kandinsky Lab (https://t.co/105E4uj0QN)(we have a SOTA Open source T2V), and I am starting to plan my next step: a PhD in AI starting in 2027 (I know it’s early).
CV: https://t.co/EPi19ax7mX