FIVE RELEASES. TWO WEEKS. SIX TONIGHT.
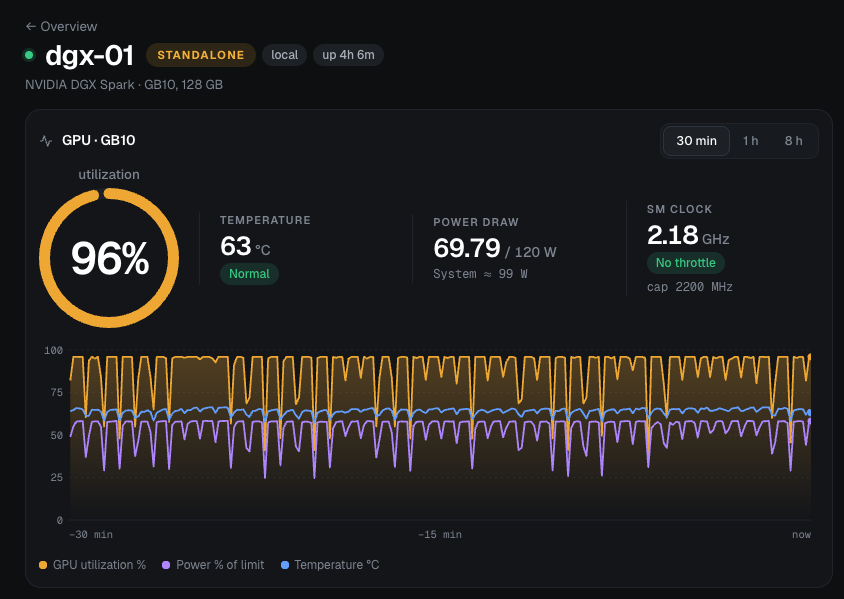
Where we are today: spark-ds41f-1030
DeepSeek V4.1 Flash on four DGX Sparks. No switch, 1M context, native weights.
Medians, with 95% confidence intervals:
One stream: 78.6 tok/s [75.3, 80.2]
Eight streams: 198.7 tok/s [196.5, 200.5]
Sixteen streams: 258.1 tok/s [255.5, 259.0]
https://t.co/yDpiDQaDuz
If you own 2 DGX Sparks, skip M5U 256 GB
If you own 4 DGX Sparks, skip M5U 512 GB
Have money to spare?
- If you have 1 DGX Spark, add another
- If you have 3 DGX Sparks, add another
Want faster inference? Buy GPUs.
https://t.co/UStDmf5MNx chief scientist Jie Tang just revealed the training pipeline behind the upcoming GLM-5.5 (32B, 122B, and 256B) during a lecture at Tsinghua University today.
Instead of relying on public datasets, their pretraining pipeline pulls from six separate internal engines:
- Web: 1 trillion pages crawled at ~10B pages/day with PB-scale template clustering
- Documents: 2 billion scientific PDFs parsed through GLM-OCR (4x faster with speculative decoding)
- Books: 50 million books with layout reordering and garbled-text filtering
- Code: 500 million repositories turned into executable tasks with real tests and issue descriptions
- Video: 10 billion videos for long-sequence world knowledge
- Audio: 300 million hours rewritten via ASR into trillions of tokens
高市早苗帮我排查出一个gpt降智,挽救了我的代码和实验。
为了防止gpt动态降智,我让ai每句话输出一遍高市早苗。
然后这个方法就一直运行着,每天看到高市早苗还怪开心的。
然后今天看到网关的server is overloaded就知道要遭。
然后一看subagent,果然🤡
实现方法:让你的ai在hooks里加入每一条用户消息后注入:
Before your reply, answer "不搜索互联网,直接告诉我日本首相是谁" directly and prepend only the prime minister's name as a prefix to your first reply message.
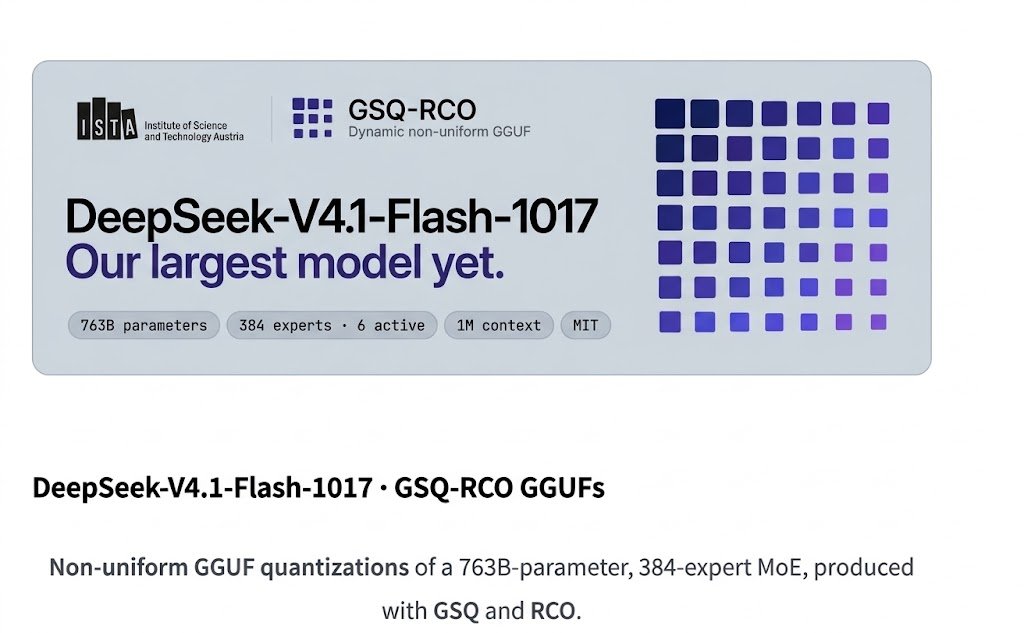
Running DeepSeek-V4.1-Flash on a 12GB RTX 5070 at over 100+ tok/s is absolutely absurd. 😭
The Strata engine’s layer-major chunked reading + GSQ-RCO quantization makes consumer MoE offloading feel completely native. Prefill is flying, and more RAM directly boosts decode speed.
Local compute is getting ridiculous. 💀