Excited to release 3.8 Flash following our 3.7 release just 3 weeks ago! It’s a substantial jump in agentic, coding and cyber capabilities. Lots of ingredients came together for this launch and we are so excited for what’s to come! Can’t wait to see what people build with it.
Introducing Gemini 3.8 Flash, another jump in Gemini's agentic + coding capabilities, and our 3rd updated Flash model in only 6 weeks...
This model has been a ton of fun to work with, excited to see what you all think!
Today, we’re continuing to push the boundaries of AI with our release of Gemini 3.1 Pro.
This updated model scores 77.1% on ARC-AGI-2, more than double the reasoning performance of its predecessor, Gemini 3 Pro.
Check out the visible improvement in this side-by-side comparison, showing Gemini 3.1 Pro’s crisp animation built with pure code.
Read more about today’s 3.1 Pro update: https://t.co/vABdcMSE3f
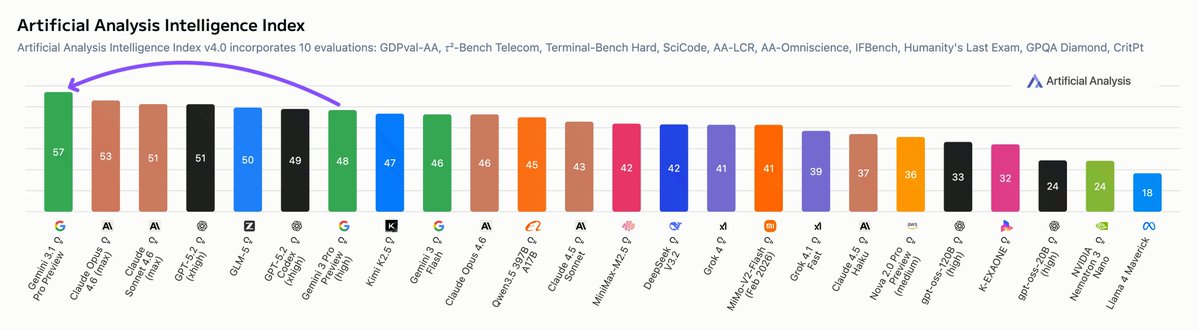
Google is once again the leader in AI: Gemini 3.1 Pro Preview leads the Artificial Analysis Intelligence Index, 4 points ahead of Claude Opus 4.6 while costing less than half as much to run
@GoogleDeepMind gave us pre-release access to Gemini 3.1 Pro Preview. It leads 6 of the 10 evaluations that make up the Artificial Analysis Intelligence Index and improves significantly over Gemini 3 Pro Preview across capabilities, with the biggest gains in reasoning and knowledge, coding, and hallucination reduction.
Gemini 3.1 Pro Preview also remains relatively token efficient, using ~57M tokens to run the Artificial Analysis Intelligence Index (+1M from Gemini 3 Pro Preview), lower than other frontier models at max reasoning settings such as Opus 4.6 (max) and GPT-5.2 (xhigh). Combined with lower per-token pricing, Gemini 3.1 Pro Preview is cost-efficient among frontier peers, costing less than half as much as Opus 4.6 (max) to run the full Intelligence Index, though still nearly 2x the leading open-weights model, GLM-5.
Key Takeaways:
➤ State-of-the-art intelligence at lower costs: Gemini 3.1 Pro Preview is leading 6 of the 10 evaluations that make up the Artificial Analysis Intelligence Index at less than half the cost to run of frontier peers from @OpenAI and @AnthropicAI. It obtains the highest score in Terminal-Bench Hard (agentic coding), AA-Omniscience (knowledge & hallucination), Humanity’s Last Exam (reasoning & knowledge), GPQA-Diamond (scientific reasoning), SciCode (coding) and CritPt (research-level physics). The CritPt score is particularly notable, scoring 18% on unpublished, research-level physics reasoning problems, over 5 p.p. above the next best model
➤ Improved real-world agentic performance, but not leading: Gemini 3.1 Pro Preview shows an improvement in GDPval-AA, our agentic evaluation focusing on real-world tasks, but is still not the leading model in this area. The model increases its ELO score over 100 points to 1316 (up from Gemini 3 Pro Preview), however still sits behind Claude Sonnet 4.6, Opus 4.6, GPT-5.2 (xhigh), and GLM-5
➤ Leading coding abilities: Gemini 3.1 Pro Preview leads the Artificial Analysis Coding Index, achieving the highest score in both Terminal-Bench Hard (54%) and SciCode (59%)
➤ Reduced hallucinations: Gemini 3.1 Pro Preview shows a major improvement in tendency to guess incorrectly when it doesn’t know the answer, reducing its AA-Omniscience hallucination rate by 38 p.p. from Gemini 3 Pro Preview
➤ Maintained token and cost efficiency: Gemini 3.1 Pro Preview improves without material increases in cost or token usage. It uses only ~2% more tokens to run the Artificial Analysis Intelligence Index than Gemini 3 Pro Preview, and keeps the same pricing ($2/$12 per 1M input/output tokens for ≤200k context). Its cost to run the Artificial Analysis Intelligence Index of $892 is less than half of frontier models such as Opus 4.6 (max) and GPT-5.2 (xhigh), though still ~2x the cost of leading open weights models such as GLM 5 ($547)
➤ Google takes top 3 spots in multi-modality: Gemini 3.1 Pro Preview ranks #1 on MMMU-Pro, our multimodal understanding and reasoning benchmark, ahead of Gemini 3 Pro Preview and Gemini 3 Flash, reinforcing Google’s leadership in multimodal reasoning
➤ Other model details: Gemini 3.1 Pro Preview retains the same 1 million token context window as its predecessor, and includes support for tool calling, structured outputs, and JSON mode
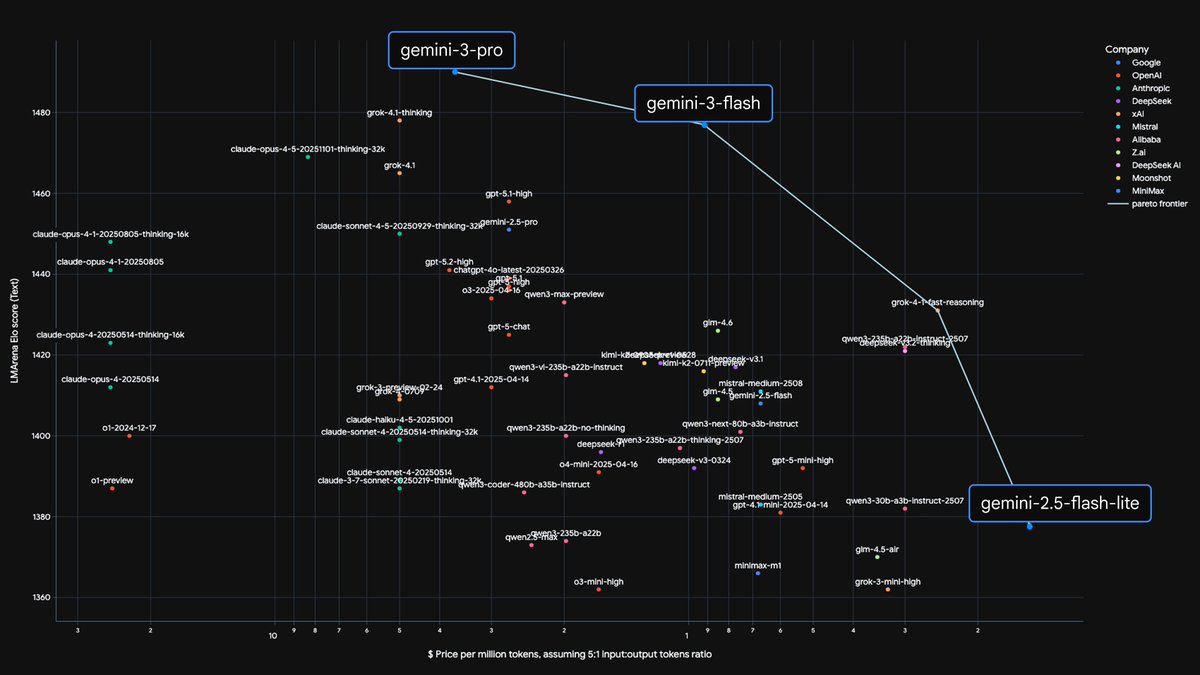
We’ve pushed out the Pareto frontier of efficiency vs. intelligence again.
With Gemini 3 Flash ⚡️, we are seeing reasoning capabilities previously reserved for our largest models, now running at Flash-level latency. This opens up entirely new categories of near real-time applications that require complex thought.
It’s available in the API, and rolling out today as the default model in AI Mode in Search and Gemini app globally.
Read more on the blog at: https://t.co/Uw9bmlJvhI
More in thread ⬇️
Introducing Gemini 3 Flash, our frontier intelligence model, available at scale for everyone. It excels at coding, tool calling, and is stronger than 2.5 Pro across most metrics!! ⚡️
Available in the API at $0.50 in / 1M tokens and $3.00 out / 1M tokens across.
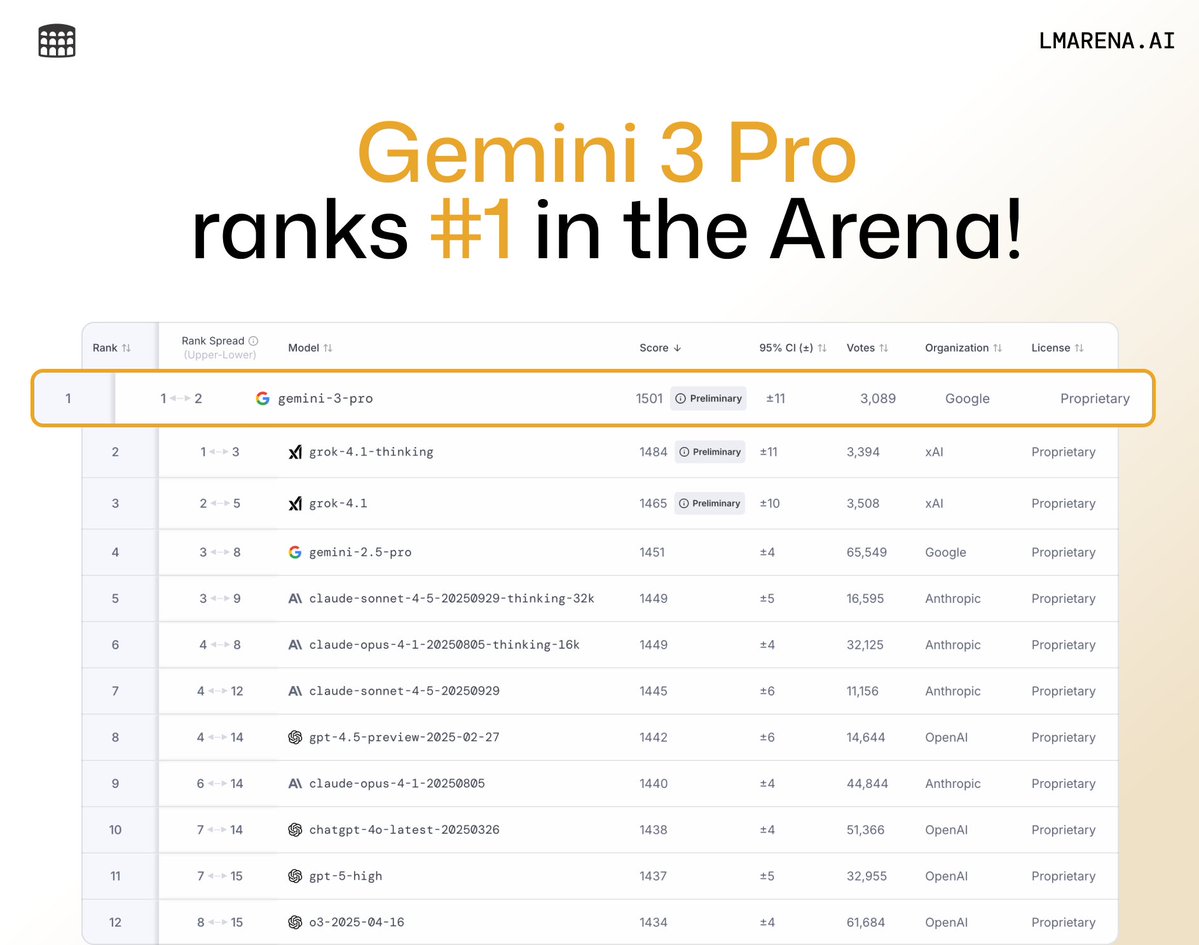
🚨BREAKING: @GoogleDeepMind’s Gemini-3-Pro is now #1 across all major Arena leaderboards
🥇#1 in Text, Vision, and WebDev - surpassing Grok-4.1, Claude-4.5, and GPT-5
🥇#1 in Coding, Math, Creative Writing, Long Queries, and nearly all occupational leaderboards.
Massive gains over Gemini-2.5:
🔸WebDev in Code Arena: 1487 (+280 pts vs 2.5)
🔸Text: 1501 (+50 pts)
🔸Vision: 1328 (+70 pts)
🔸Arena Expert: Top-3 (just 3 pts behind #1)
Huge congrats to the @GoogleDeepMind team on this breakthrough! 👏
@_coenen Perhaps QuickType ? https://t.co/zF42tlSppo
It export JSON schema to many languages (including Python, Typescript), but I don't think it converts to XML.
What a way to celebrate one year of incredible Gemini progress -- #1🥇across the board on overall ranking, as well as on hard prompts, coding, math, instruction following, and more, including with style control on.
Thanks to the hard work of everyone in the Gemini team and elsewhere at Google! 🎊
Today’s the one year anniversary of our first Gemini model releases! And it’s never looked better.
Check out our newest release, Gemini-exp-1206, in Google AI Studio and the Gemini API!
https://t.co/oxVzotWmzp
Excited to present our work RICHES at #EMNLP2024, an alternative to RAG that interleaves retrieval with text generation tasks, all within a single LLM decoding pass!
Shout out to my collaborators @tmkwiat@liviobs https://t.co/sdBJuNMWTm #NLProc#LLMs#Retrieval
Excited to share our prompt tuning playbook! (Not an official product. Just authors tips & tricks for better prompting). I'm most excited about first half on mental models for post-training & prompting. Feedback/forks welcome! #LLM#PromptEngineering
https://t.co/TrVhKVJc64
🚀 Join the Gemini Multilinguality team @GoogleDeepMind 🌐 We’re looking for researchers passionate about making LLMs helpful for all. Dramatically improve model quality, coverage, and cultural relevance across hundreds of languages. #NLProc#MultilingualAI#i18n#LLMs https://t.co/RzwiRM5zWr
I am absolutely thrilled to announce the release of Gemma 2! Today, we're releasing both pre-trained-only and fully post-trained 9B and 27B models. The full technical report is here: https://t.co/QIYalQ3jaB and it's live *right now* on https://t.co/XoiJYticj3.
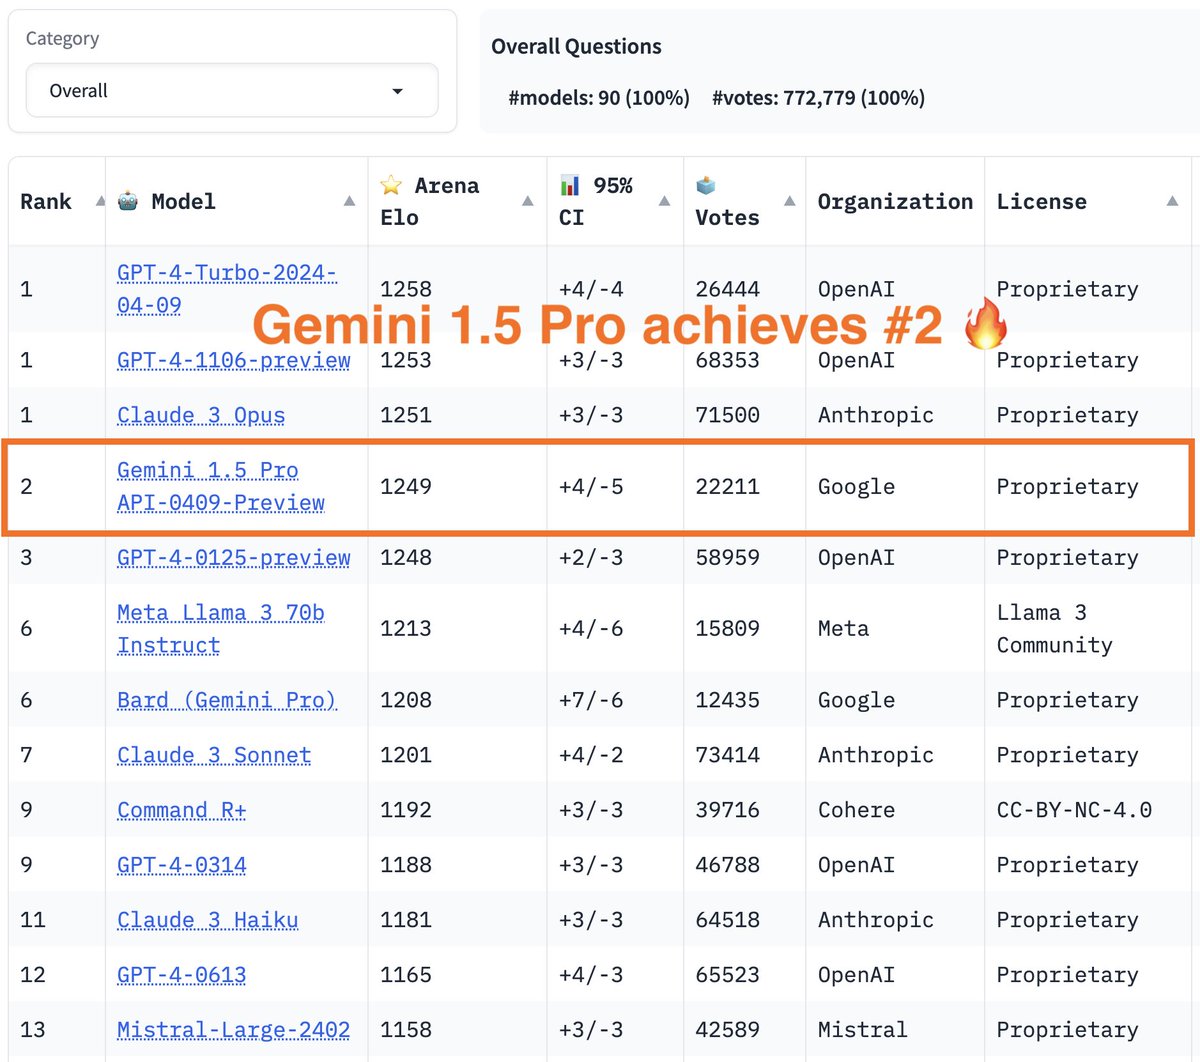
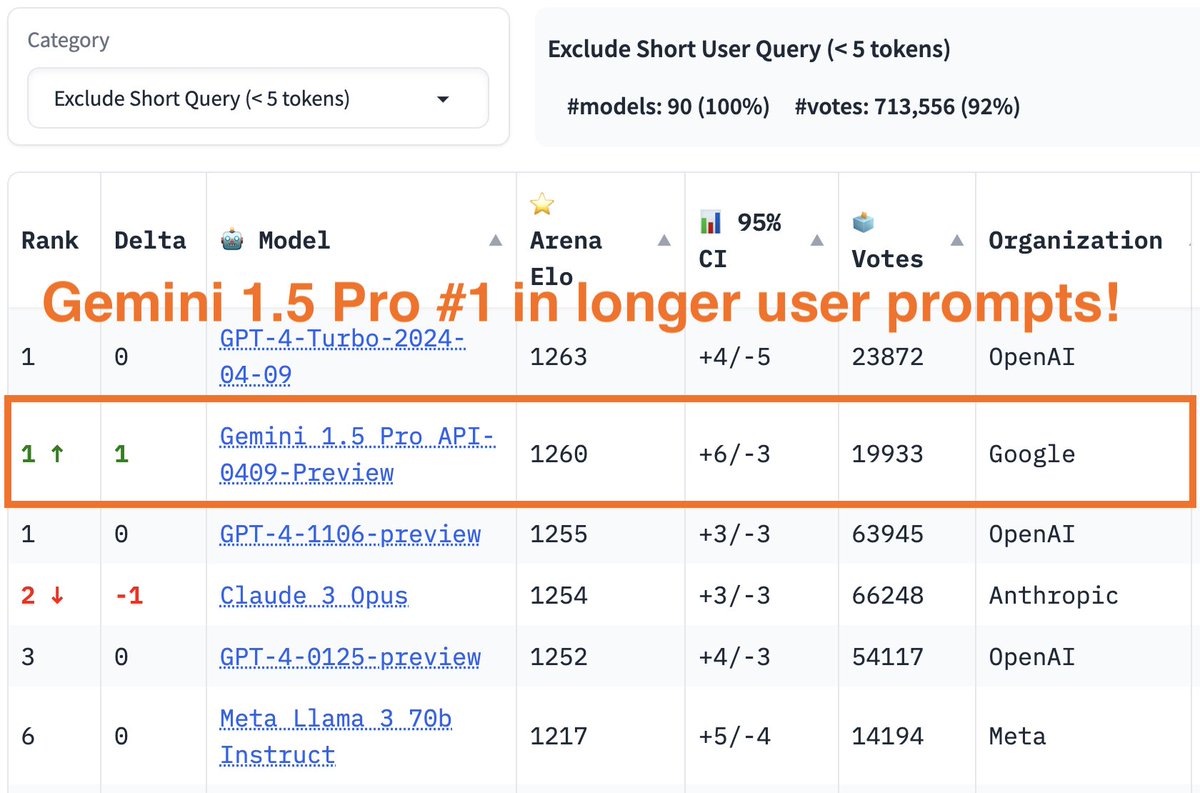
More exciting news today -- Gemini 1.5 Pro result is out!
Gemini 1.5 Pro API-0409-preview now achieves #2 on the leaderboard, surpassing #3 GPT4-0125-preview to almost top-1!
Gemini shows even stronger performance on longer prompts, in which it ranks joint #1 with the latest GPT-4-Turbo🔥
Big congrats to @GoogleDeepMind on shipping this powerful Gemini API to developers & community. Very excited to see what app can be built on top!
Better yet, I discovered the best independent bookstore (for me). The only small bookstore where I've seen The Master and Margarita on Staff picks... in the US https://t.co/cuAURQeV4a
Read their story: https://t.co/VLgA8TyExu
Finally I'm in the right place! My new hood doesn't have (only) a bar crawl, but an independent bookstore crawl. https://t.co/SMC4msg9qL Synchronized with Spring Break. You guys rock! #bklyn
Come chat with us (@jeremy_r_cole and myself) about our work on efficient text retrieval using LLMs, lexicalized representations and non-autoregressive decoders. Today at 9AM at the poster session at #EMNLP2023
Interested in fast and efficient retrieval? Want to use modern LLMs, but don't have the accelerator budget to deal with volume of queries?
Introducing "NAIL: Lexical Retrieval Indices with Efficient Non-Autoregressive Decoders" at #EMNLP2023
🧵
https://t.co/hIRWW53RkQ
@palak_jain_14 and I will be presenting our 1Pager work soon at the Google research booth at #EMNLP2023. Drop by for a casual chat about this work or working at Google.
https://t.co/vHobHOOG3E
Current retrieval paradigms are complex, pipelined systems. Visit the #EMNLP2023 Google booth today at 10:30 AM to learn about 1-Pager, a system that aligns retrieval and reasoning as a unified task with a single Transformer-based model and decoding pass.
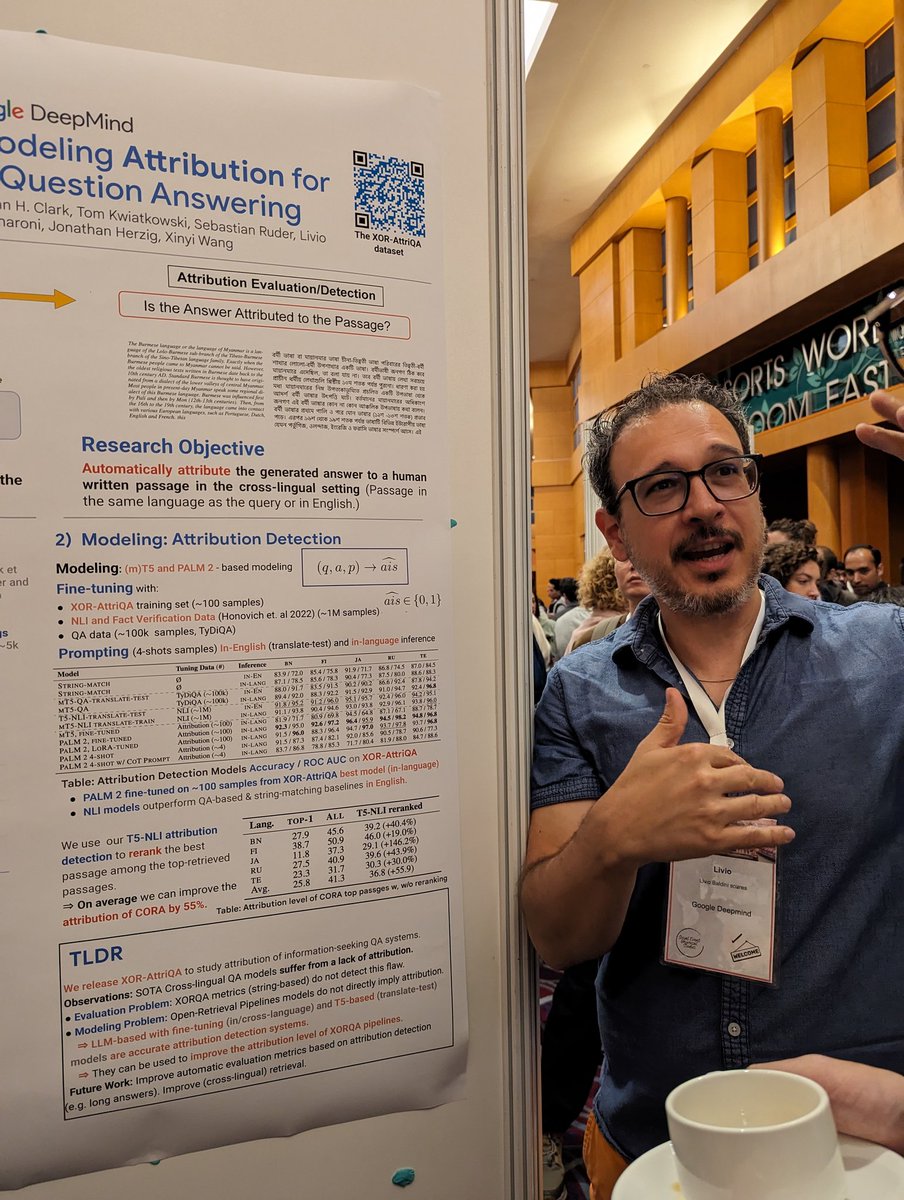
Check out our work on Evaluating and Modeling Attribution for Cross-Lingual Question Answering presented by @ben_mlr and @liviobs at #EMNLP2023
https://t.co/vcGFnPntCa