As LLMs have become endowed with vision, are they able to play video games by viewing individual frames and passing input via text?
We put this to the test on Tetris, with GPT-4V, Gemini Pro and LLaVA – and fail to find much good in their play.
Feb 2024: GPT-4V and Gemini Pro Vision both place 20 pieces on average and clear 0 lines.
Sep 2026: GPT-6 Astra placed 121 pieces and cleared 34 lines.
We only rerun the benchmark intermittently on models throughout these 2 years, partly because they were so bad it didn't feel worth testing.
But now Astra almost saturates it! Not hard to imagine a version of it soon being able to play indefinitely.
Built a small drawer plugin for Omarchy called Nook, since my bar was getting crowded after trying out many plugins haha
It opens below the bar rather than along it, so it doesn't cover or shift existing items. You can just drag widgets in and out.
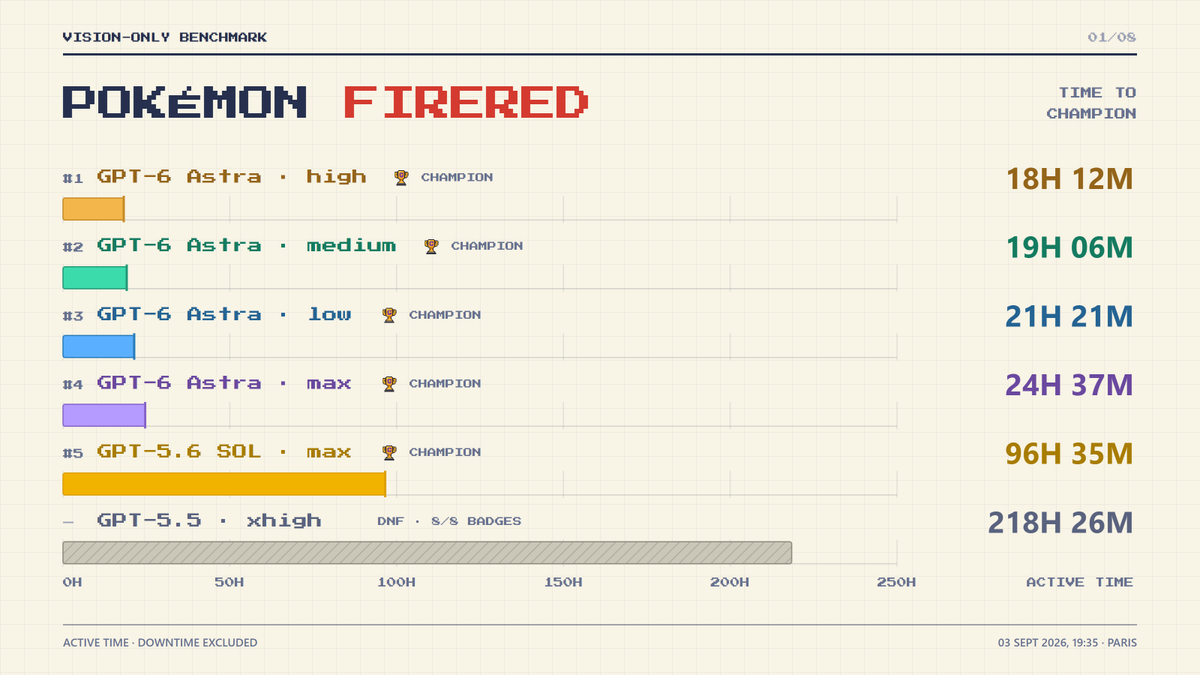
A few weeks ago, I called GPT-5.6 Sol "insane at Pokémon"
I got early access to GPT-6 Astra. It beat the game over 5x faster.
Time to become Champion:
• GPT-6 Astra (high): 18h 12m
• GPT-5.6 Sol (max): 96h 35m
For perspective, GPT-5.5 still hadn’t finished after 218 hours.
From struggling to finish to beating the game in under a day. The pace of progress is wild.
Fresh run coming to the GPT Plays Pokémon Twitch channel!
Screenshots only. No RAM, no hints, no walkthrough. Fully autonomous.
https://t.co/Ko4siZGaQ6
Agents on Rails: We ran 8 models against 21 atomic tasks to see which were best at writing Rails code. 3 runs each: a bug report, a security finding, a feature request.
The first benchmark report with findings is now live. So: what did we discover?
As of August 2026:
- Most accurate: @claudeai Opus 5 by @AnthropicAI (by a hair). Solved 92% of runs (58 of 63). (But for a little more than half the cost, you get almost the same accuracy with @Kimi_Moonshot.)
- Cheapest: @OpenAI GPT-5.6 Luna. 73% of runs solved at default medium reasoning effort, and all 63 of its runs cost 90 cents combined.
- Fastest: Luna again, at a median of 3.3 minutes per run task.
- Best combination of all three: @OpenAI GPT-5.6 Sol. 84% accuracy, costing $0.52 and 5 minutes per run.
Read all the findings in the first full benchmark report from @evilmartians here: https://t.co/SxyPPUwDJw
For anyone with endless ideas, this agent age is nirvana as those ideas are met with endless execution, endless exploration. I've never had has much fun working with computers as I do right now. What a time to be alive.
We removed ~80% of the Claude Code system prompt for our newest models, this is what we've learned about writing system prompts, skills and Claude.MDs for them. https://t.co/6DZwSrZjE9
I've been re-running the "GPT plays Pokémon" benchmark with GPT-5.5, this time on Pokémon Emerald against GPT-5.2 (didn't have time to let GPT-5.4 play Emerald, @OpenAIDevs releases models too fast).
GPT-5.5 demolished it.
→ Hall of Fame in 2.8 days vs 9.0 days for GPT-5.2 → 3.2× faster overall → 2.2× fewer in-game actions (6,775 vs 15,054)
Same prompt, same ROM, same tools. Only the model changed.
From what I've observed, GPT-5.5 is a beast at spatial reasoning, navigation, and puzzle solving.
GPT-5.2 brute-forces its way to Champion. GPT-5.5 actually thinks before pressing buttons.
Cool chart made with Claude. The fastest man-made object in space moves at 0.064% the speed of light (and not even under its own power). We have a long way to go
Action. Wonder. Adventure. Artemis II has got it all. Don't miss the moment. Our crewed Moon mission will launch as early as April 1.
Learn how to watch: https://t.co/fAg0bGAqEc
@trq212 Pretty cool and useful! It focused on my most recent sessions though, I'd like to see it dig deeper into older sessions to suggest more improvements for https://t.co/WW1pVC4Tdm or skills
curious about the training data of OpenAI's new gpt-oss models? i was too.
so i generated 10M examples from gpt-oss-20b, ran some analysis, and the results were... pretty bizarre
time for a deep dive 🧵
wrong, wrong, wrong
it's not desire or motivation or willpower, but positive CONTEXTS that are scarce
when you're in france you speak french, when you're in cambridge you go to class, when you're at a hackathon you code. we need to scale the right kinds of contexts to inculcate the kinds of brilliant people we want in the world