Java4Shell has a very interesting history, similar to PHP2Shell.
The bug had been reported since June, but was only patched after our centaur hacker showed it was exploitable.
Full disclosure timeline: https://t.co/NvPFLNZlzV
This is super cool, and exposes a recently shipped feature I've been meaning to share: Rex now works across SSH, including one command to install over SSH: `rex server install ssh://<address>` and then you're up and running! Works in all our clients too.
(Finally) wrote up "Understanding Positional Embeddings in Modern LLMs."
A RoPE from-scratch tutorial missing from my LLM building blocks collection + what recent architectures do (NoPE, partial RoPE, hybrids).
Prob not the flashiest topic, but essential for understanding LLMs
DNS requests to Playstation spiking like time off requests 🕹️🌴😂
GTA 6 launch starts its regional rollout in New Zealand where DNS requests to Playstation download domains increased up to 8x as much during the preload unlock and 15x as much at midnight local time for the official launch.
Radar is tracking the releases around the world - stay tuned!
AI abundance is coming. But can we handle the side-effects of getting this right?
I sat down with @harari_yuval to talk about ai, consciousness, abundance and human flourishing.
Issue 2 of the Humanist Review of AI is out today!
https://t.co/rYD8ld2qtu
posted this into our Rex discord today... the new `𝚛𝚎𝚡.𝚞𝚒` primitives provides a new set of simple but powerful methods to build interactive scripts within Rex that require user interaction.
Now you can build the workflow of your dreams, that little action you always wanted or just a pizza topping selector.
I wrote some docs up that go into detail about how this feature works https://t.co/4UXo1zSrBt
Another day in security.
1. @Apple Pay and other services went down. Apple says an internal update caused the outage. Their customers couldn't buy products at stores during this period.
2. @NSAGov’s internal network experienced disruption. They claim it was scheduled maintenance.
3. Java4Shell: a critical Java vulnerability reported by @calif_io.
4. @Equinor EU's largest natural gas supplier disclosed a cyberattack on its IT systems.
5. @McDonalds users reportedly received suspicious push notifications that looks similar to agents probing for bugs.
6. Reports of AI agents being used in ransomware extortion. Agents are negotiating amounts based on the revenue data they collect from the breach.
7. @FCC and @FEMA conducted a nationwide emergency alert test for TV and radio. Reports exist about these tests failing.
8. @IIHFHockey’s website was taken down following a cyberattack.
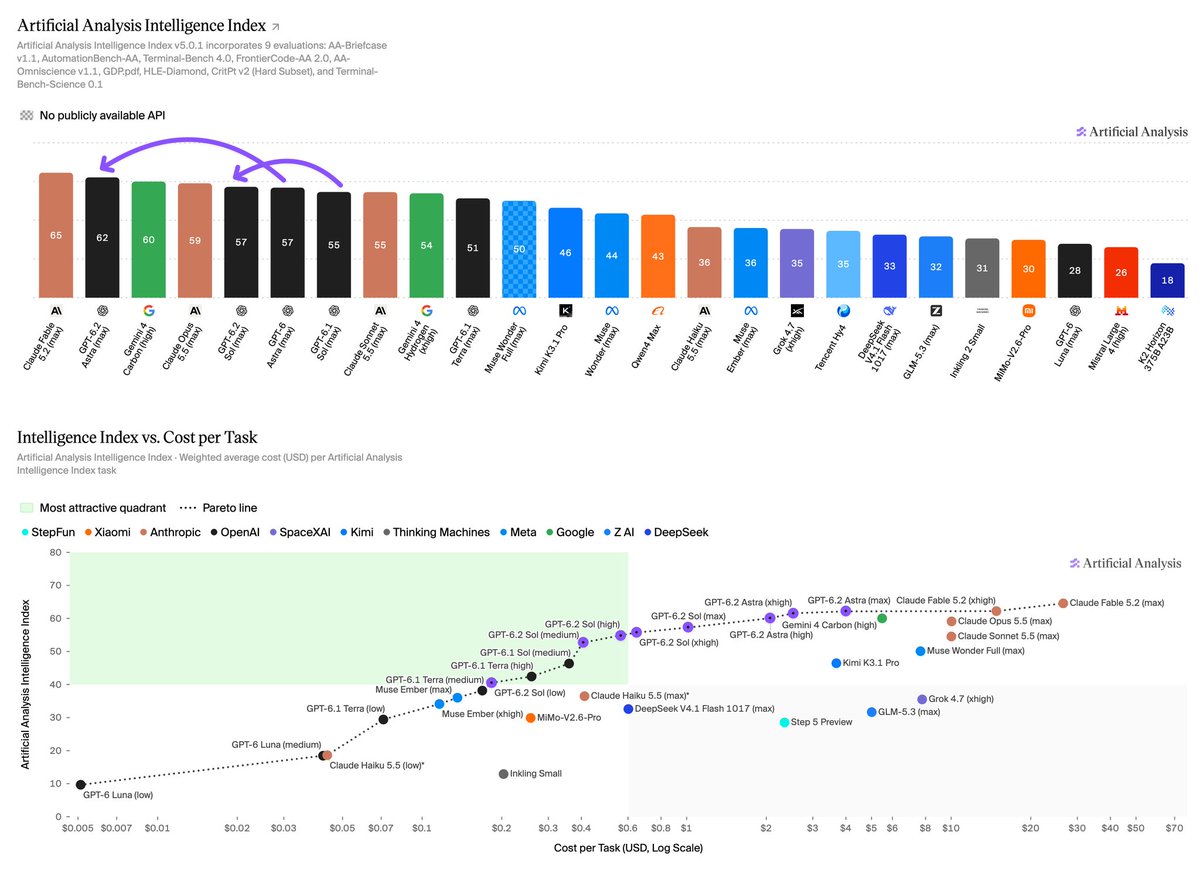
OpenAI’s release of GPT-6.2 Astra and GPT-6.2 Sol delivers the #2 model in the Artificial Analysis Intelligence Index and most of the Cost per Task Pareto frontier
@OpenAI's GPT-6.2 Astra is priced at $8/$40, 20% below GPT-6 Astra, and cached input drops to $0.40 from $1.00 per million tokens. GPT-6.2 Sol pricing is unchanged from GPT-6.1 Sol, at $2/$10 per million input/output tokens.
Key takeaways:
➤ Second in Intelligence Index: OpenAI now trails only Anthropic’s Claude Fable 5.2 in the Artificial Analysis Intelligence Index. GPT-6.2 Astra jumps 5 points from GPT-6 Astra, overtaking Gemini 4 Carbon (60) and Claude Opus 5.5 (59) at their top effort settings. GPT-6.2 Sol gains 2 points at 57, placing it on par with GPT-6 Astra at ~15% of the Cost per Task.
➤ Occupies most of cost and output token frontiers: OpenAI models now occupy most of the Cost per Task Pareto frontier, sharing the frontier with only Anthropic and Meta. OpenAI also dominates the Output Token per Task Pareto Frontier, with Claude Fable 5.2 being the only model from a non-OpenAI lab appearing on the frontier.
➤ Strengths in science and knowledge: OpenAI performs strongly in both of our key science-focused evaluations, leading Terminal-Bench-Science 0.1, covering agentic scientific research workflows, and placing second only to Claude Fable 5.2 in CritPt v2 (hard subset), covering physics reasoning. GPT-6.2 Astra performs below only Claude Fable 5.2 in factual knowledge as measured by AA-Omniscience v1.1 Accuracy, and in HLE-Diamond, a reasoning and knowledge benchmark.
➤ Leading in 3D and robotics: GPT-6.2 Astra leads AA-3D at 1318, with Claude Fable 5.2 at 1271 and GPT-6.2 Sol at 1259. This benchmark measures how well models build interactive 3D experiences, and is rated by human graders. GPT-6.2 also leads AA-Robotics v0.1, our research preview measuring how well language models can understand, plan, and act in the real world. GPT-6.2 Astra and GPT-6.2 Sol scored 79 and 78 respectively, ahead of Claude Fable 5.2 at 75. Our team is hard at work adding more difficult tasks, as OpenAI and Anthropic models can now perform the majority of basic tasks in this initial research preview.
➤ No improvement in Coding Agent Index: GPT-6.2 Astra is flat with GPT-6 Astra, and GPT-6.2 Sol loses 3 points relative to GPT-6.1 Sol in the Artificial Analysis Coding Agent Index (Codex harness at max effort). For Sol, the drop is driven by a 14-point drop in SWE-Atlas-QnA-AA, where the model is more likely than its predecessor to omit key facts in its responses. Cost efficiency however does place several effort levels of GPT-6.2 Astra and Sol on the Pareto frontier for Cost per Task.