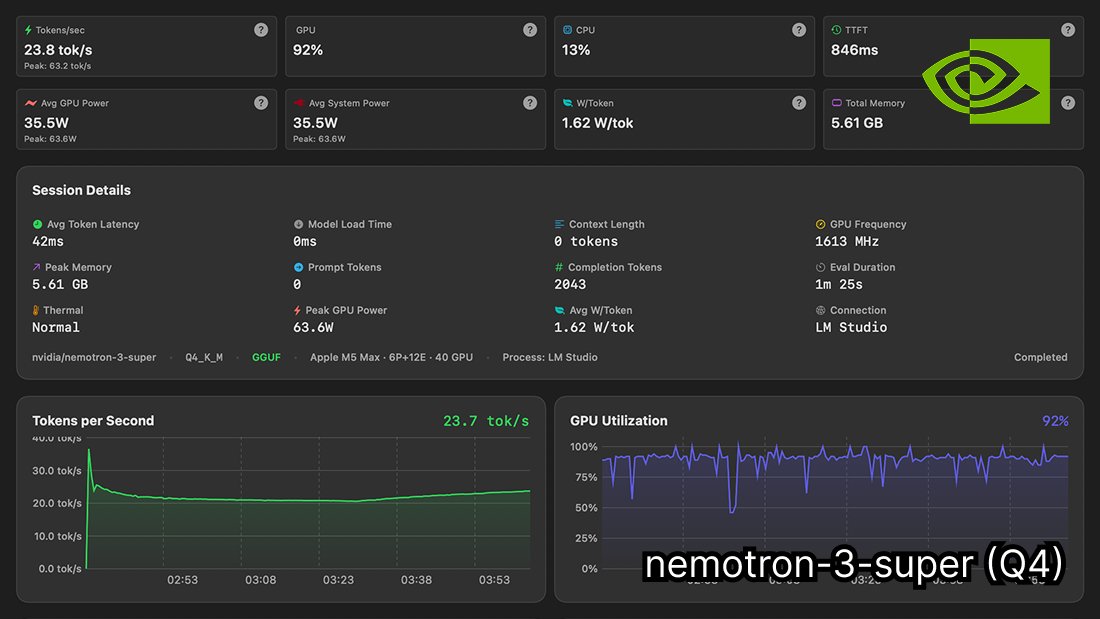
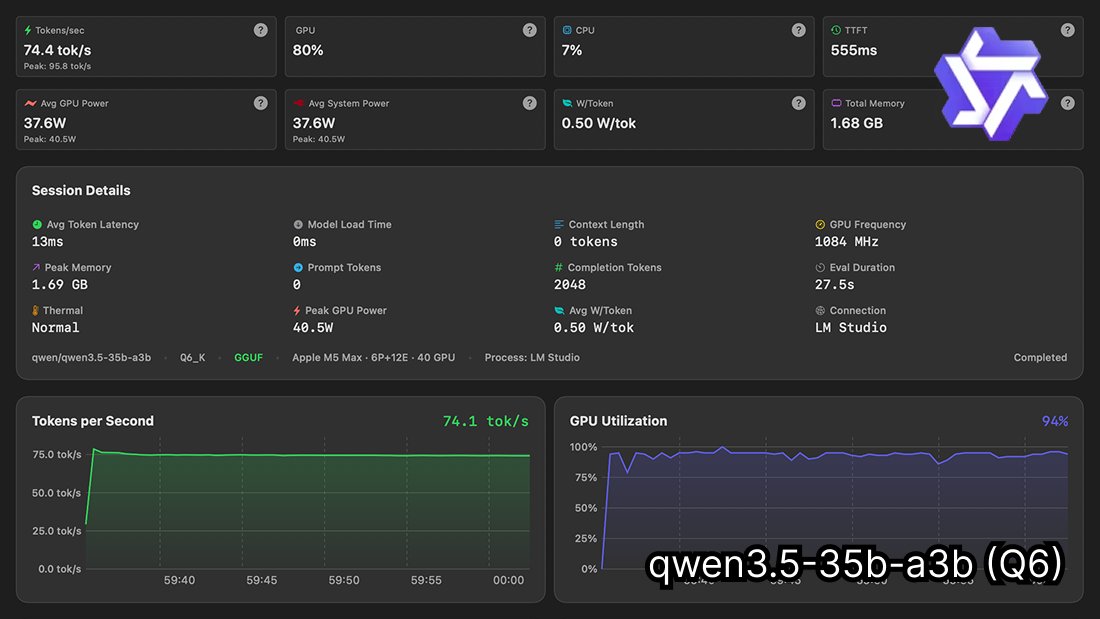
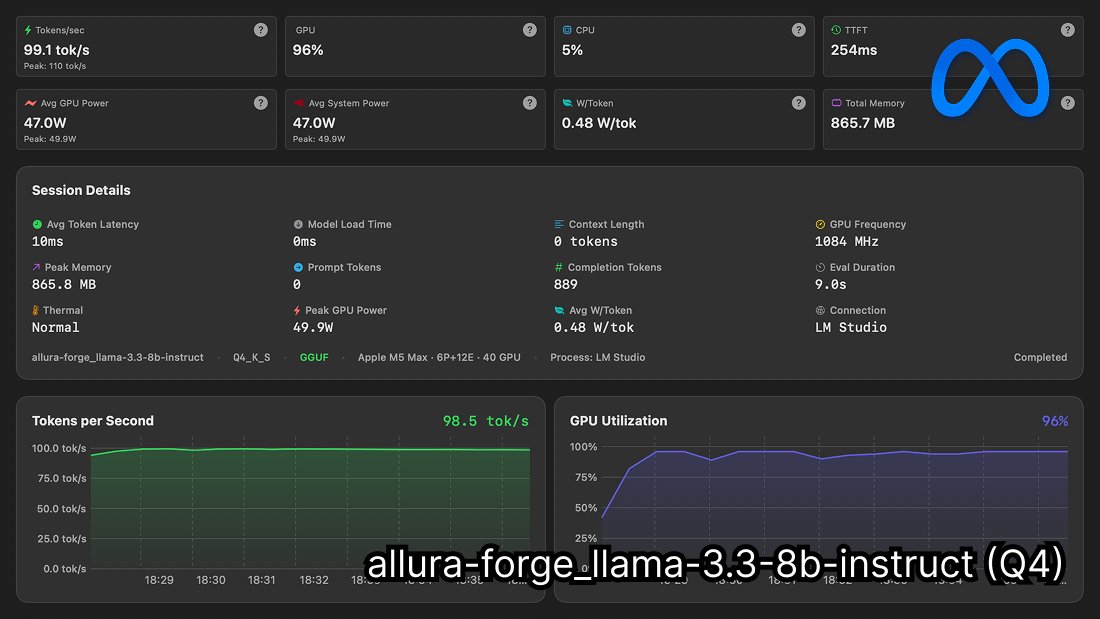
LLM speed on my MacBook M5 Max (128GB):
• Qwen3.5-35B-A3B (Q6): 74 tok/s
• Nemotron-3 Super (Q4): 24 tok/s
• Qwen3-Coder-Next (6-bit): 67 tok/s
• Llama 3.3 8B Instruct (Q4): 99 tok/s
On my M1, Llama 3.3 was my go-to for most local tasks at about 20 tok/s. On the M5 Max, it's hitting 99 tok/s.
Qwen3.5 feels like a huge upgrade and is my favorite so far.
Qwen3-Coder-Next is surprisingly good at dev tasks, although I'll probably stick with GPT-5.4 for most.
I'm also impressed by Nemotron-3 Super, but its personality feels a bit too dry.
Qwen3.5 is now updated with improved tool-calling & coding performance!
Run Qwen3.5-35B-A3B on 22GB RAM.
See improvements via Claude Code, Codex.
We also benchmarked GGUFs & removed MXFP4 layers from 3 quants.
GGUFs: https://t.co/4lSce5zZbO
Analysis: https://t.co/rHZK8JWdYM
New in Cowork: scheduled tasks.
Claude can now complete recurring tasks at specific times automatically: a morning brief, weekly spreadsheet updates, Friday team presentations.
Admins can create private plugin marketplaces to distribute them across the org.
A unified "Customize" menu also gives you more control over plugins, skills, and connectors in one place.
🤔First Text/Image-to-3D Skill?
🔥Claude Code just made a selfie for @grok & itself instantly with Rodin #3D#Skill 😂
🚀Quick Setup:
/plugin marketplace add DeemosTech/rodin3d-skills
/plugin install rodin3d-skill@rodin3d-skills
Free to use! Just ask #Claude to generate🎨
@SadlyItsBradley One question is screensharing in meetings possible to use like Google meet or slack and ms teams app? Can you share a view and a single window ?
BREAKING 🚨: Claude Skills are rolling out to all paid users! Skills are packaged and shareable instructions to guide Claude on how to approach your workflows.
Haiku 4.5 is a workhorse that makes the coding experience in Claude Code feel really fast.
While Sonnet 4.5 remains the default, Haiku 4.5 now powers the Explore subagent which can rapidly gather context on your codebase to build apps even faster.