Applied Compute update:
- crossed $100M annualized revenue run rate up from zero 18 months ago
- raised $350M at $3.25B led by Elad Gil
- 40% of customers use AC for both custom model training + production inference
- inference serving 1T tokens a day after launching 12 weeks ago
- 2X enterprise customers since last raise
- 3X team since January, 85% are researchers and engineers
- Working with customers like Microsoft, Shopify, Harvey, DoorDash, Cognition, Clay, Decagon and others
To move even faster we need people who are extremely technical AND extremely practical. If this is you, please reach out.
Introducing Phonic-1, the most advanced speech-to-speech model for agentic tasks — from @phonic_co, the speech-to-speech model company.
We’ve had a breakout year and raised a $27.5M Series A led by @firstround with participation from @Lux_Capital, @felicis, and Definition.
The fastest inference in the world is coming to @OracleCloud.
@cerebras and @Oracle partner to enable ludicrous speed on OCI.
Cerebras brings fast AI.
Oracle brings deep expertise building and running AI infrastructure at scale.
Enterprises trust Oracle with their most important data and applications for decades.
Partnering with Cerebras gives Oracle customers more choice to match each AI workload to the compute that suits it best.
Coming soon, they’ll be able to build agents, assistants, and real time experiences with super fast AI in the cloud they already use.
Thank you to @MThiagarajan_ and the @Oracle team.
Excited to build with you.
Thrilled to announce the general availability of
@positron_ai's Atlas Inference Appliance on
@OracleCloud, making Positron the first AI chip startup to be deployed at scale with a hyperscaler. Look out for more announcements this week at Oracle Cloud World! https://t.co/HlQGoPS9bo
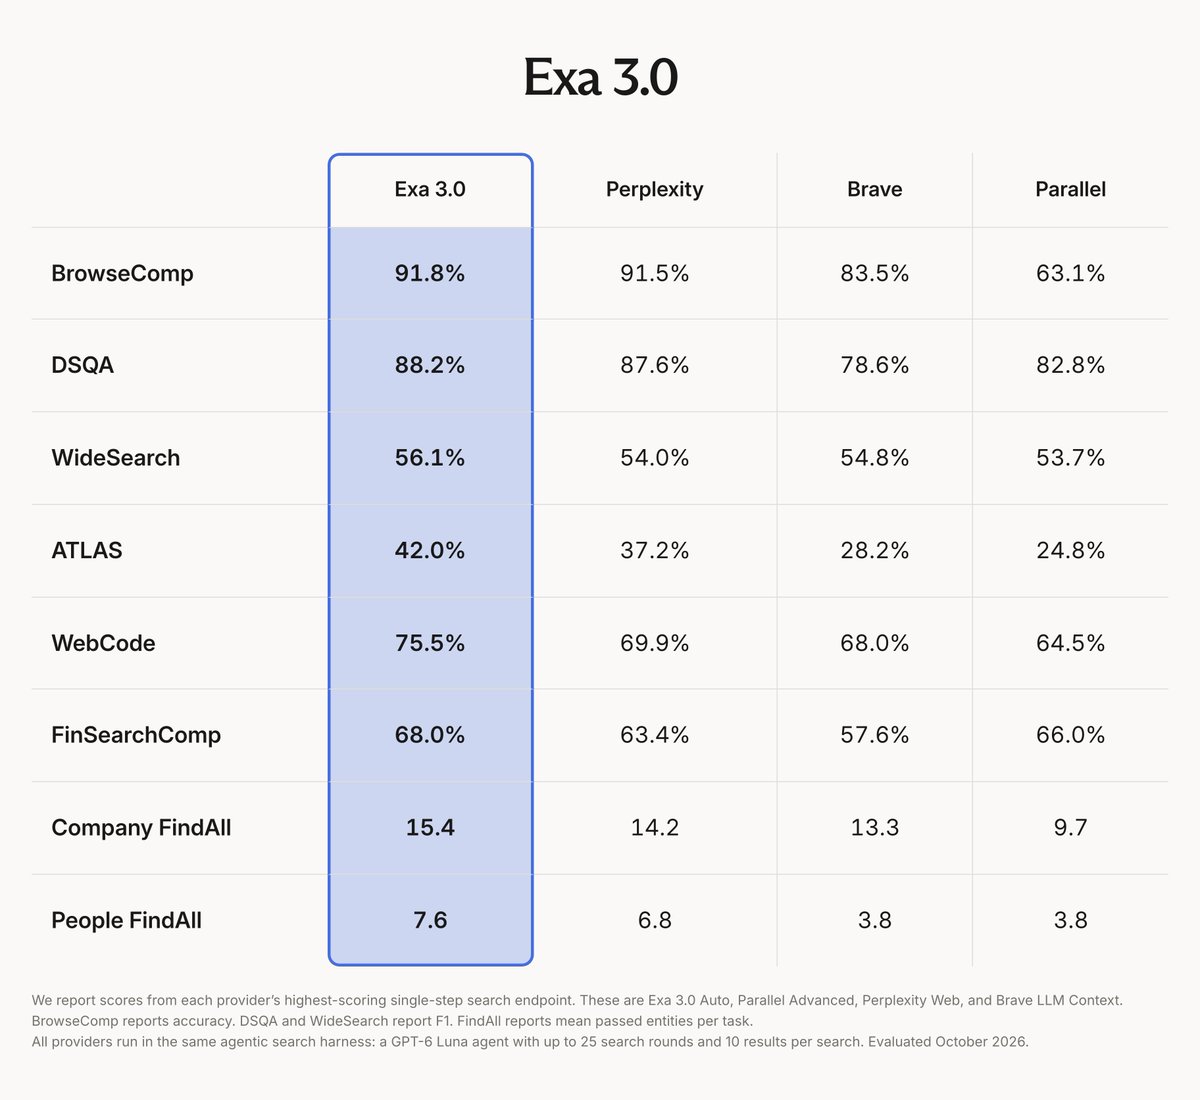
Introducing Exa 3.0: our largest ever improvement to search quality.
Exa is now #1 on every benchmark we tested, from public evals to verticals like coding and GTM intelligence.
It's the result of multiple research breakthroughs 🧵
We built a time machine for the web.
Introducing Exa Snapshot: an index of 400 billion historical snapshots of webpages that lets you search as if it's the past.
Snapshot is already being used for backtesting prediction models, RL at labs, exploring the pre-AI web, and more.
I made some public disclosures about our hardware at the @theallinpod conf this week and wanted to share the progress here. Earlier this summer we got hardware back! The execution was madness…we went from no team in Jan to a tape out in 5 months. AI enabled MUCH tighter loops of research and our execution speed shows the results.
This is the first large-scale demonstration of a causal, physical dynamical system to do real compute. 🚀
We released the Un-0 model (see link) in June and it runs on this physical system; the images below come from the actual hardware. What’s more, this chip requires <900 nJ to generate an image; this is many orders of magnitude less energy than conventional machines.
https://t.co/zYU0ezXJUq
The world is debating whether frontier AI needs to slow down. If it comes to it, do we know how?
A lab can say it stopped training. A country can sign a treaty. But, is the compute following the rules? @attestable is building that layer. New blog! 🧵
The world has identified verifiable AI as a missing civilization-scale primitive. The core technical obstacle, practical zero-knowledge proofs, was considered impossible.
We solved it.
Today, we are launching @attestable, the AI Integrity Company, and announcing a $20M seed round led by @jaminball at @AltimeterCap and @YonatanMandelba at @TLV_Partners , with participation from @HalcyonFutures, Cerca Partners, @Weiner_Lia at Netz, @nickymontanaa at Zero Knowledge Ventures, @assaf_rappaport, Asaf Ezra, Nadir Izrael, Jon Coller, Eyal Manor, @OmerPerchik.
We're coming out of stealth.
We've built our first racks after a successful A0 tapeout, $1B+ in customer contracts, and $800m raised.
Early customer tests show us achieving SOTA throughput, latency, and power efficiency on inference workloads.
Our first racks ship this summer.
Introducing our first model, Un-0!
We trained an image generator powered by a backbone of coupled oscillators in place of a more traditional conventional neural network.
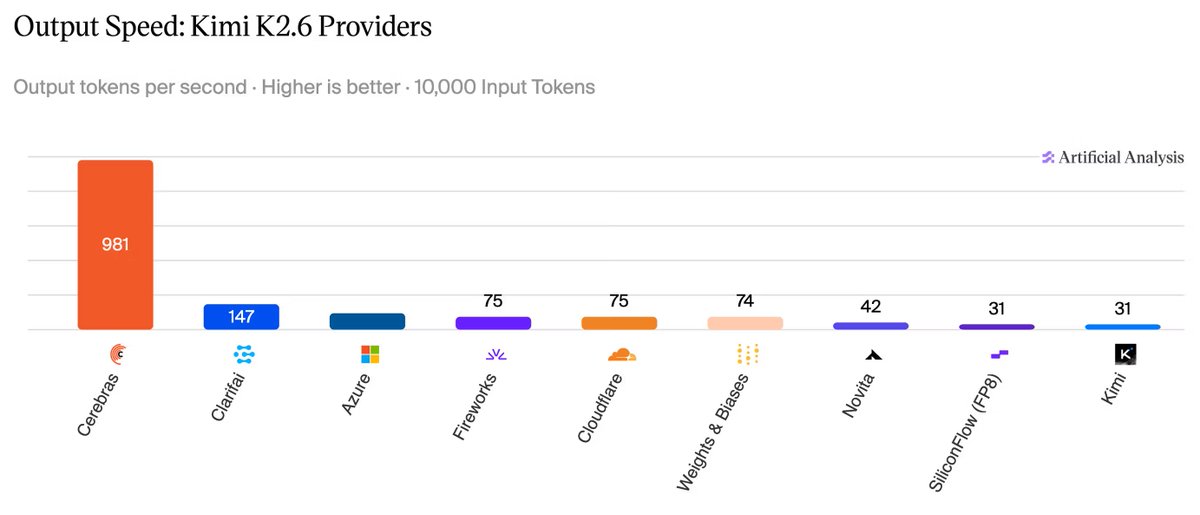
Cerebras is now running Kimi K2.6 – a trillion parameter model – in enterprise trials.
At ~1,000 tokens/s, this is the fastest frontier model performance ever measured by Artificial Analysis @ArtificialAnlys.
I've been working on a new LLM inference algorithm.
It's called Speculative Speculative Decoding (SSD) and it's up to 2x faster than the strongest inference engines in the world.
Collab w/ @tri_dao@avnermay. Details in thread.
🚀 Today we’re releasing FlashOptim: better implementations of Adam, SGD, etc, that compute the same updates but save tons of memory. You can use it right now via `pip install flashoptim`. 🚀
https://t.co/nRrLSpjnwV
A bunch of cool ideas make this possible: [1/n]